Summary
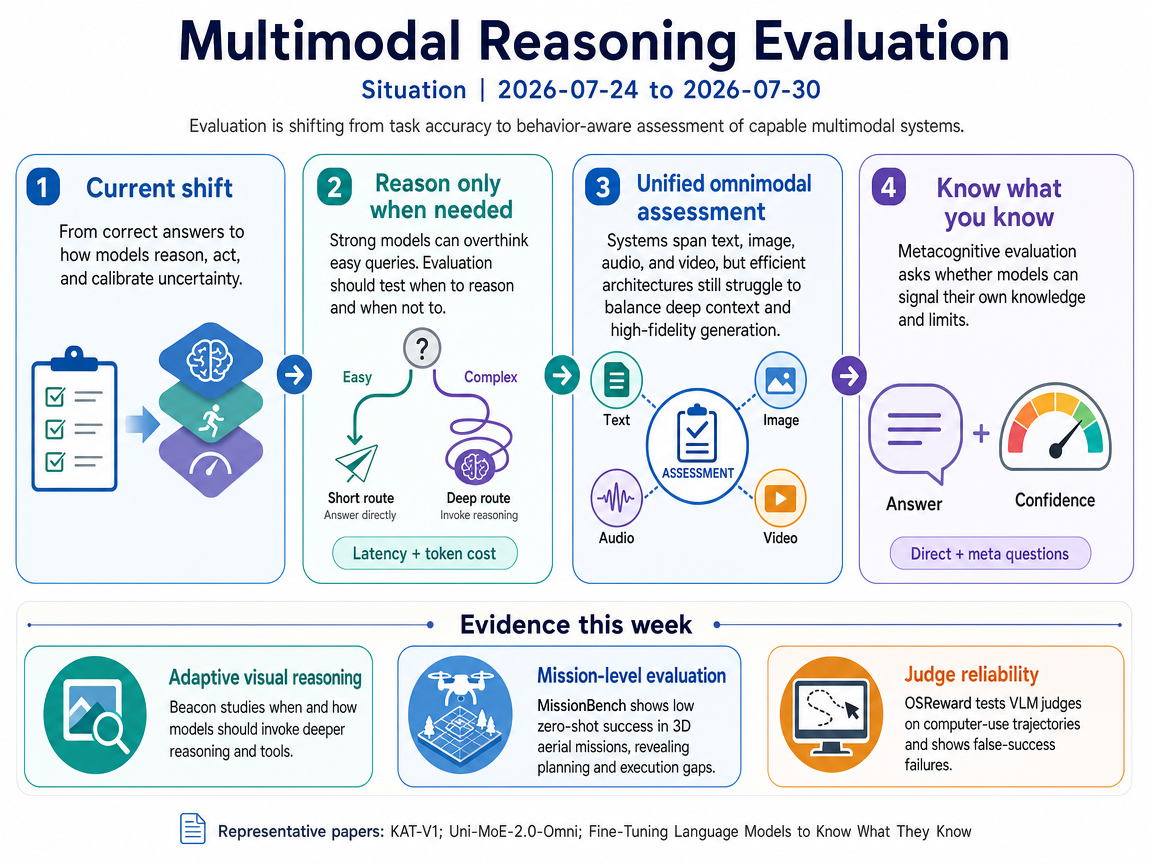
This theme centers on how increasingly capable language and multimodal models should be evaluated and controlled as they move beyond text-only benchmarks. Representative work highlights three linked needs: efficient reasoning that avoids unnecessary chain-of-thought, unified assessment of omnimodal understanding and generation, and metacognitive evaluation of whether models can accurately signal what they know.
Situation
The representative papers frame model evaluation as shifting from simple task accuracy toward behavior-aware assessment of capable systems. One line of work argues that strong reasoning models often "overthink," creating latency and token costs on easy queries, so evaluation must capture whether a model can choose when to reason and when not to. Another argues that omnimodal systems still lack a unified, computationally efficient architecture that balances deep context understanding with high-fidelity generation across text, image, audio, and video, making broad multimodal evaluation essential as these models scale.
A complementary representative paper pushes evaluation inward, asking whether a model actually knows what it knows. It introduces metacognitive measurement through paired direct and meta questions, reflecting a broader concern that modern models should not only answer correctly, but also calibrate their own knowledge and limitations. Supplemental evidence extends this direction to agentic multimodal settings, where researchers examine tool-use adaptiveness in visual reasoning and the reliability of VLM-based judges for computer-use trajectories.
Infographic (English)
Progress
Kimi K3: Open Frontier Intelligence <See Details on Fugu-MT>
Kimi K3: Open Frontier Intelligence: 我々はKimi K3を紹介した。これは2.8TパラメータMixture-of-Expertsモデルで、104億のアクティベートパラメータ、ネイティブビジョン機能、100万のコンテキストウィンドウを備えている。 Kimi K3 は Kimi Delta Attention and Attention Residuals 上に構築されている。 我々は,Kimi K3が長期コーディング,エージェント,知識,推論,ビジョンタスクにおいて,フロンティアレベルのパフォーマンスを実現することを示す。 It connects to Model Evaluation / Multimodal through the paper's concrete task, method, evidence, or application setting.
Beacon: Knowing When and How to Perform Agentic Visual Reasoning <See Details on Fugu-MT>
Beacon advances multimodal reasoning evaluation by targeting when and how an agentic vision model should invoke deeper reasoning and tools. It introduces a necessity-aware adaptive reward and hint-guided rollout in RL training, concretely addressing the gap between adaptive tool invocation and effective tool use in visual reasoning.
Zero-Shot Mission-Level Evaluation for Aerial MLLM Agents <See Details on Fugu-MT>
MissionBench broadens multimodal evaluation from perception tasks to zero-shot mission-level assessment of aerial MLLM agents in 3D environments. It reveals that even leading models succeed on fewer than 35% of missions, exposing coordinated spatial, planning, and execution gaps beyond standard single-task benchmarks.
OSReward: Instituting Standardized Evaluation for Cross-Platform Computer-Use Reward Models <See Details on Fugu-MT>
OSReward provides a standardized cross-platform benchmark for evaluating VLM judges on computer-use agent trajectories. It shows that current judges are easily fooled by false-success trajectories and releases an open 100K-sample corpus with trained reward models to close the reliability–cost gap.
Outlook
Outlook Summary
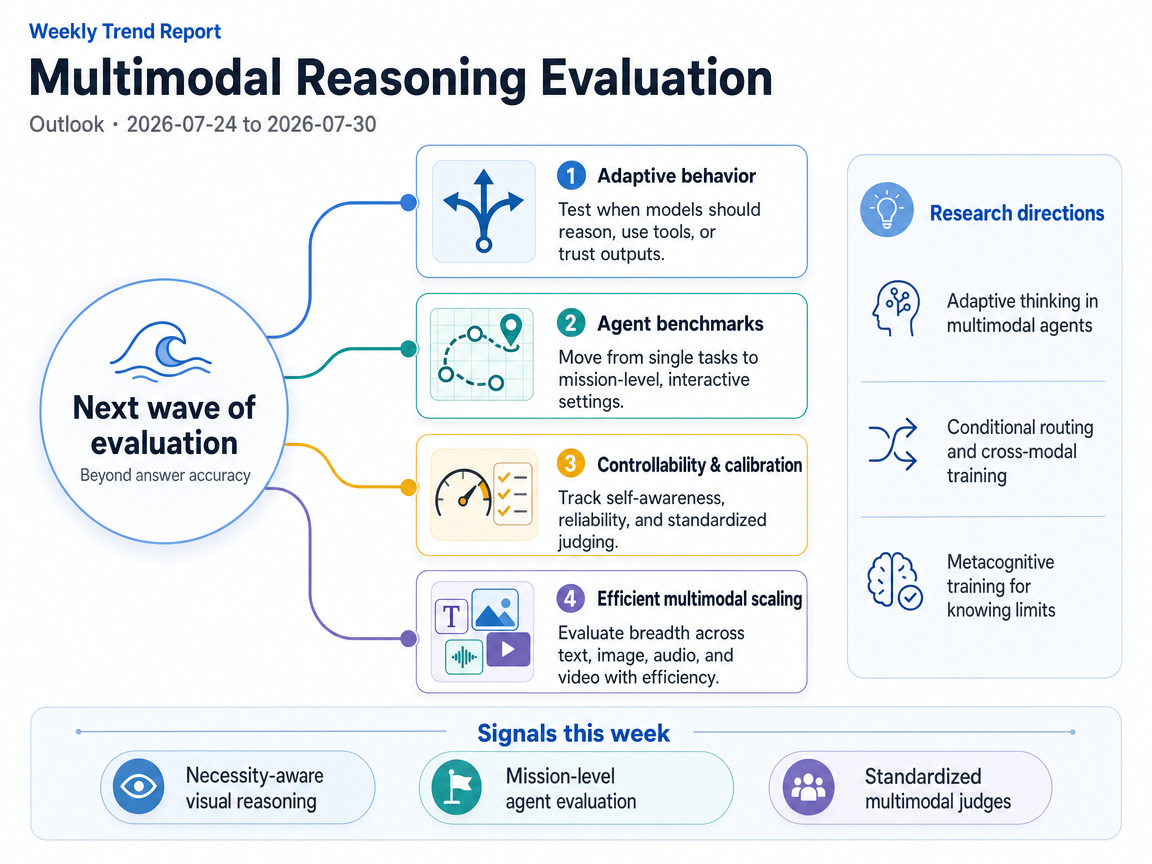
Near-term multimodal evaluation will likely move beyond answer accuracy to adaptive behavior: whether a model knows when to reason, use a tool, or question its own output. Research will increasingly test this behavior in interactive agents and mission-level tasks. As omnimodal systems scale across multiple media, evaluation will also focus on controllability, calibration, and efficiency. Conditional routing and metacognitive training may help these systems use computation selectively while remaining self-aware and reliably measurable.
Infographic (English)
Three-Year Movement
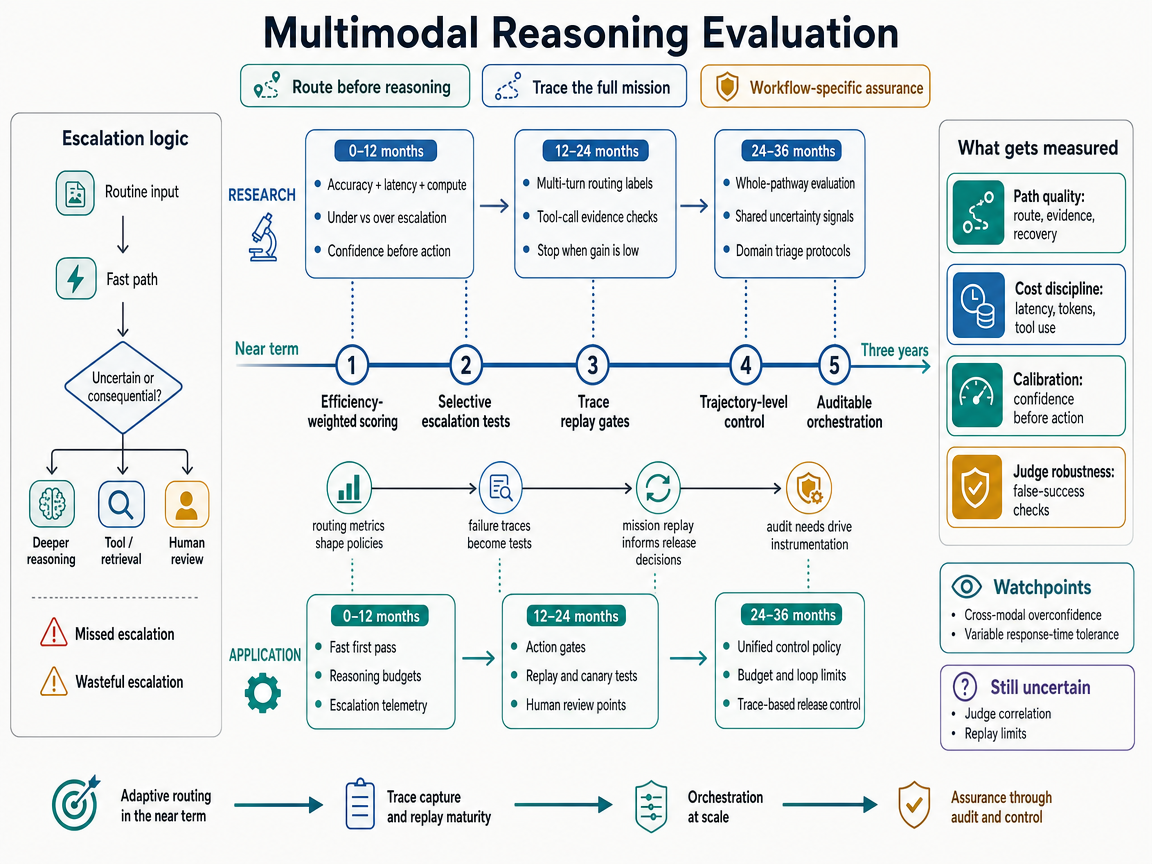
The standard scenario applies a clinical-triage mechanism to multimodal systems. A fast first pass handles routine tasks, while uncertainty, consequences, or conflicting evidence can trigger deeper reasoning or human review. In the first year, researchers will turn this idea into routing tasks that measure accuracy, latency, and resource use. They will compare learned routers with simple fixed rules and count both missed escalations and wasteful ones. Early applications will add reasoning controls and escalation records to bounded workflows, with reviewed failures used to adjust thresholds.
In the second year, evaluation will move from single answers to longer interactions. Datasets will label individual routing decisions while also checking whether the overall mission succeeded. Systems will be tested on whether they seek evidence before consequential actions and whether they stop when further reasoning is unlikely to help. Operational frameworks will place explicit gates before external actions, while logs preserve inputs, decisions, and outcomes for later review. Human oversight will remain necessary where confidence estimates change sharply across tasks or media types.
By the third year, learned escalation could become a standard orchestration layer if it repeatedly performs better than fixed policies. Evaluation would then cover the complete pathway, including the fast model, specialist resources, and handoffs to deeper review. Infrastructure could coordinate local models, hosted systems, and human reviewers under one task-specific policy. It would enforce computation limits, interrupt runaway loops, and show whether each escalation added enough useful information to justify its cost and delay. A strong monitoring cue would be independent benchmarks showing that uncertainty-based routing reduces both failures and unnecessary computation. The scenario would weaken if cross-modal overconfidence persists, evaluators keep accepting false-success trajectories, or deep reasoning becomes so inexpensive that routing offers little benefit.
The contender scenario uses software reliability engineering as its mechanism. Consequential agent runs are recorded as traces, failures are replayed, and incidents become regression tests that future versions must pass. Automated evaluators are treated as monitors that can also make mistakes. In the first year, research will connect adaptive reasoning with detailed trajectory records and mission-level evaluation. Teams will examine whether routing events, confidence changes, and tool interactions reveal hidden failures that final answers miss.
Later in the first year, shared trace formats and replay tools should make failures easier to compare across systems. Adversarial tests will probe whether evaluator models accept actions that look successful but are unsupported. Applications will begin with bounded workflows such as coding assistants, computer-use agents, and cross-modal support systems. Some teams may connect replay results to controlled releases and rollback decisions. A key threshold is a credible deployment that blocks or reverses an update because mission replay detects a regression that ordinary benchmark averages missed.
In the second year, incident-derived traces would support workflow-specific regression suites. New failures would create new tests, and those tests would change routing or release policies. This feedback loop should expose subtler problems as instrumentation improves, although human sampling will remain important because several evaluators can repeat the same error. By the third year, common mission traces could enable fairer comparisons between unified multimodal systems and modular systems that depend on external tools. An assurance layer might receive bounded authority to adjust reasoning budgets, request more evidence, or require human approval. Monitoring should focus on whether replay results consistently predict failures in live use. The scenario would weaken if traces do not reveal the cause of actions, changing environments make replay unreliable, or detailed records cannot be retained safely. Even if the mechanism succeeds, semantic correctness cannot be reduced to system uptime, so task-specific evidence and human judgment will remain necessary.
The maybe scenario uses real-workflow conformity testing. Controlled benchmarks act like laboratory tests, while portable evaluation tools replay the tasks that organizations actually expect systems to complete. In the first year, research would connect reasoning efficiency, confidence calibration, and adversarial testing of automated judges. Open and instrumentable models would help researchers observe routing and tool-use behavior rather than scoring outputs alone. The main technical question would be whether these measurements remain stable when prompts, workloads, or model versions change.
Initial practical audits would cover bounded workflows such as coding, document-and-image processing, and computer-use agents. Reports would compare task completion with resource use and the quality of the action trace. Researchers would also measure a conformity factor, meaning the gap between performance on controlled benchmarks and performance in realistic work. The scenario accelerates only if a visible false-success incident is traced to weak evaluation and several large organizations then reuse a common testing annex. That shared evidence could create a standards flywheel: wider reuse encourages providers to improve routing and calibration, which produces better workflow data for later tests.
In the second year, researchers would define acceptable limits for benchmark-to-workflow divergence and develop tests for judge models. Evaluation services could maintain specialized workload packs, while continuous conformance methods check each major system update. By the third year, long-horizon missions would become the main unit of evaluation, with tests separating plausible local actions from successful completion of the full task. Workflow-specific evaluation could then become a release gate for changes to models, routing policies, or tools. A likely stable structure would combine public capability benchmarks with private tests tailored to a particular workflow. Monitoring cues include common annex language, reusable replay tools, and public investigations of false-success incidents. The scenario would weaken if metrics remain unstable, audit methods cannot be reconciled, or automated judges remain easy to fool. Unlike a fixed physical measurement, calibration and mission success can shift after every update, so any approval process would need continuing tests rather than a one-time certificate.
1-Year / 3-Year Research-Application Infographic
References
- KAT-V1: Kwai-AutoThink Technical Report - Authors: Zizheng Zhan, Ken Deng, Huaixi Tang, Wen Xiang, Kun Wu, Weihao Li, Wenqiang Zhu, Jingxuan Xu, Lecheng Huang, Zongxian Feng, Shaojie Wang, Shangpeng Yan, Jiaheng Liu, Zhongyuan Peng, Zuchen Gao, Haoyang Huang, Ziqi Zhan, Yanan Wu, Yuanxing Zhang, Jian Yang, Guang Chen, Haotian Zhang, Bin Chen, Bing Yu, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Uni-MoE-2.0-Omni: Scaling Language-Centric Omnimodal Large Model with Advanced MoE, Training and Data - Authors: Yunxin Li, Xinyu Chen, Shenyuan Jiang, Haoyuan Shi, Zhenyu Liu, Xuanyu Zhang, Nanhao Deng, Zhenran Xu, Yicheng Ma, Meishan Zhang, Baotian Hu, Min Zhang, / <See Details on Fugu-MT> / License: CC-BY-SA-4.0
- Fine-Tuning Language Models to Know What They Know - Authors: Sangjun Park, Elliot Meyerson, Xin Qiu, Risto Miikkulainen, / <See Details on Fugu-MT> / License: CC-BY-4.0