Summary
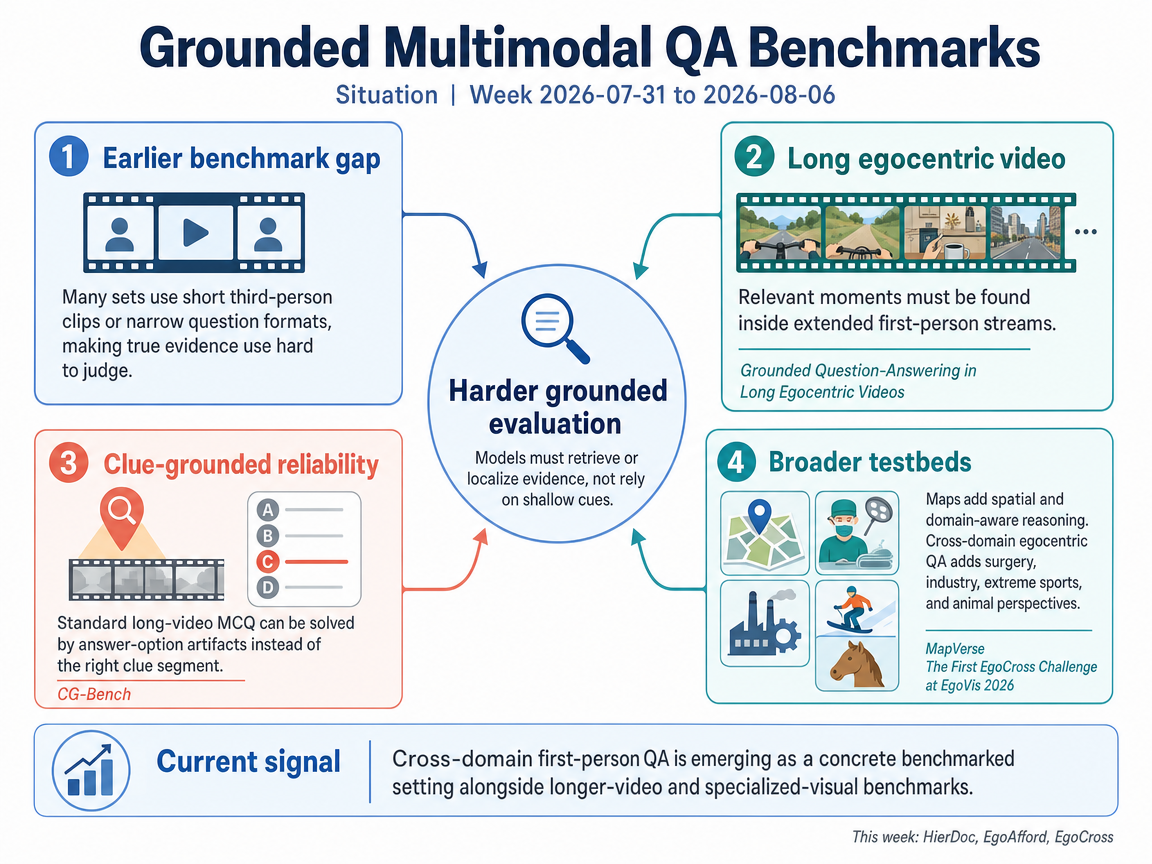
Benchmarking work is increasingly targeting harder, more credible evaluation settings for multimodal question answering, especially where models must retrieve or ground evidence rather than rely on shallow multiple-choice cues. This week's signal strengthens that trend in egocentric video, with cross-domain first-person QA emerging as a concrete benchmarked setting alongside longer-video and specialized-visual benchmarks.
Situation
Representative papers frame a common benchmarking gap: many earlier evaluation sets center on short, third-person clips or narrow question formats, making it hard to judge whether systems truly use the relevant visual evidence. Grounded Question-Answering in Long Egocentric Videos argues that long first-person QA is difficult because models must localize the relevant temporal window inside extended personal video streams, while CG-Bench further argues that standard long-video MCQ can be unreliable because models may solve questions by exploiting answer-option artifacts instead of grounding on the right clue segment.
The benchmarking push is also broadening beyond generic video. MapVerse positions maps as an underrepresented but important testbed for spatial, visual, and domain-aware reasoning, using diverse real-world maps and human-authored questions rather than narrow or heavily synthesized setups. As current-week evidence, The First EgoCross Challenge at EgoVis 2026 (2608.04589v1) extends egocentric VQA benchmarking into specialized domains such as surgery, industry, extreme sports, and animal perspectives, explicitly focusing on domain shift rather than only everyday first-person activities.
Infographic (English)
Progress
The First EgoCross Challenge at EgoVis 2026: Cross-Domain Egocentric Video Question Answering <See Details on Fugu-MT>
EgoCross advances grounded QA benchmarking by testing egocentric video question answering under explicit cross-domain shifts beyond everyday first-person scenes. Compared with earlier long-video or generic egocentric sets, it adds specialized domains as the main evaluation challenge rather than only longer context or standard activity coverage.
Outlook
Outlook Summary
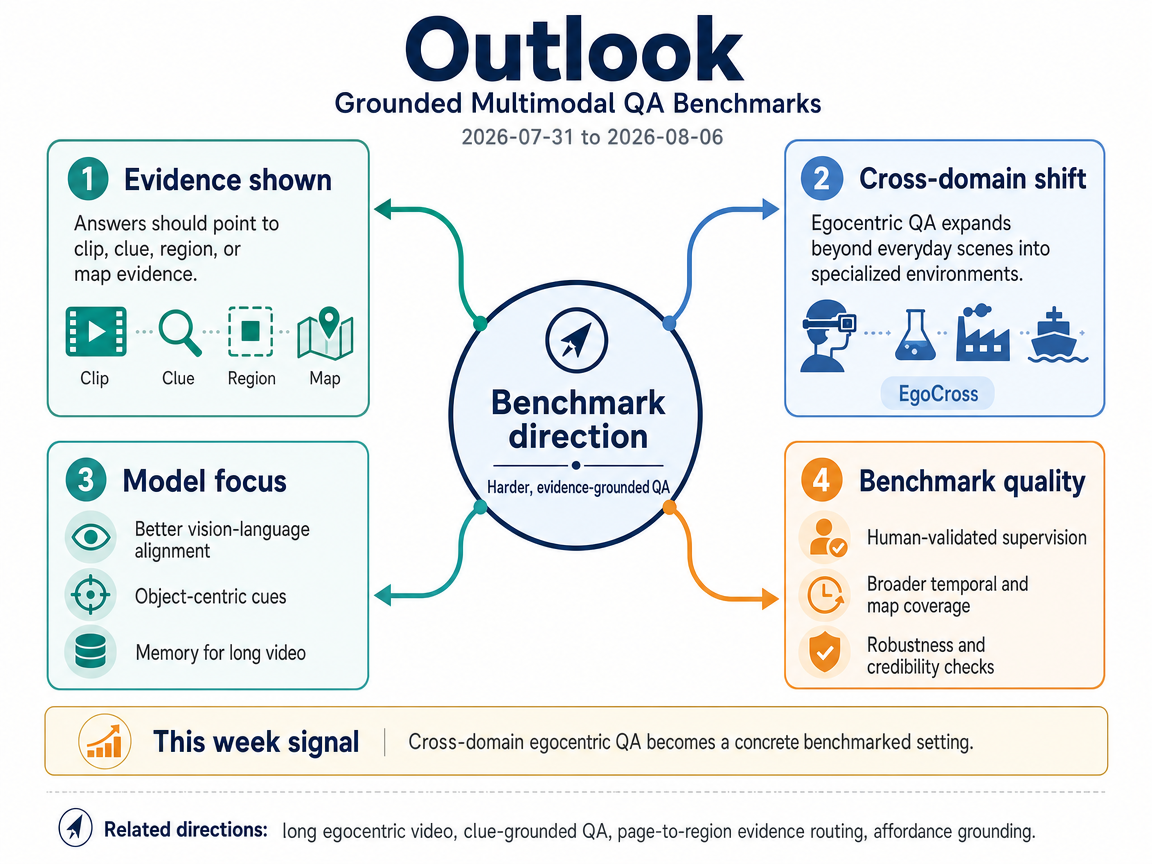
Multimodal question answering will likely move toward benchmarks that require models to identify the clip, region, or map evidence supporting each answer. Tests should cover longer contexts and unfamiliar specialized settings, with more human-validated supervision and stronger checks against shortcuts. Progress will depend on better visual-language alignment, object-centered perception, higher-quality data, and efficient memory compression. Broader benchmark coverage and stronger credibility tests should help distinguish genuine evidence use from superficial pattern matching.
Infographic (English)
Three-Year Movement
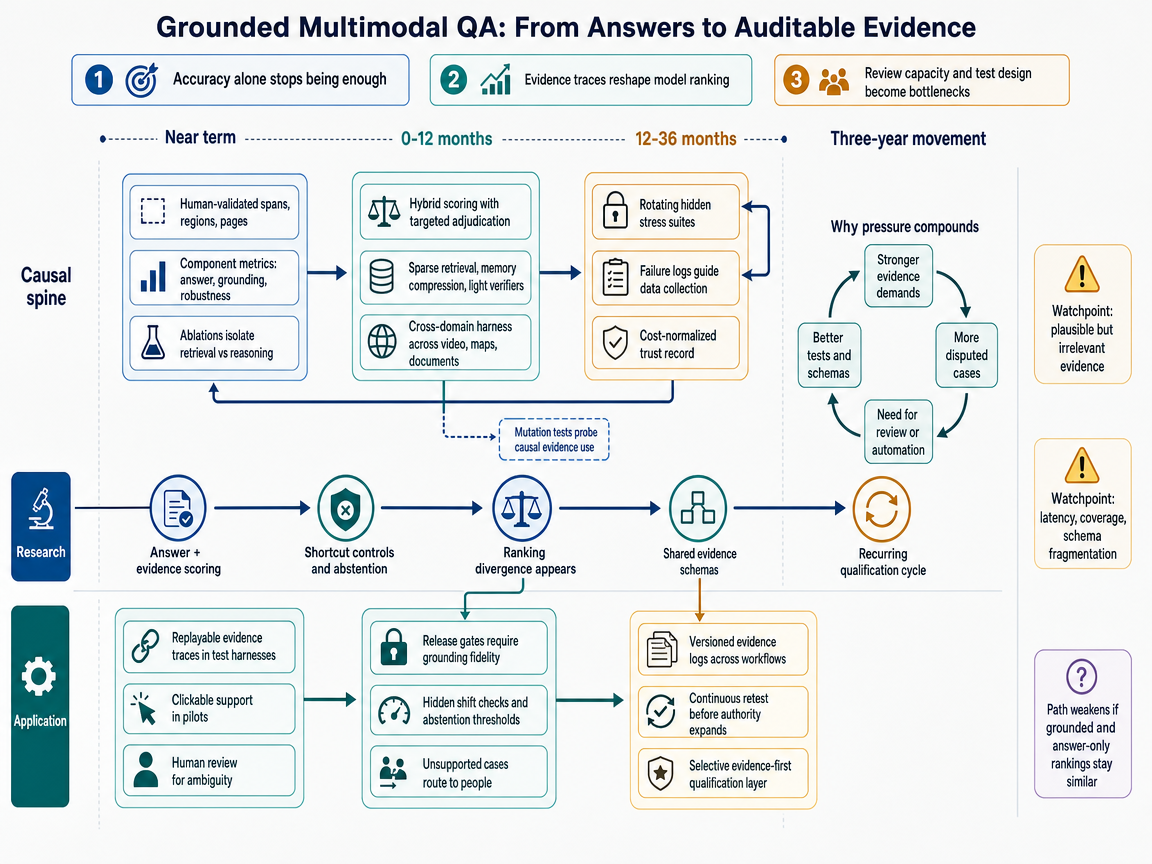
The standard path begins with benchmarks shifting from answer accuracy alone to checks of the clip, region, or passage that supports an answer. The core mechanism is an auditable evidence trace, combined with tests under unfamiliar conditions and permission for the model to refuse when support is missing. In the first year, datasets should add clearer evidence annotations and controls that remove or shuffle information to expose shortcuts. Reports will increasingly separate answer quality from grounding, robustness, and appropriate refusal. A key early signal would be a repeatable change in system rankings once these measures are included.
By the second year, shared formats could describe evidence across video, maps, and documents. Research would then focus on lowering the cost of checking long inputs through staged retrieval, compressed memory, or small verification models. Automatic scoring could handle clear cases, while people review ambiguous evidence. Replayable failure records and hidden domain-shift tests would also become more common in model release checks. This stage depends on the hybrid process being reliable enough to compare systems without making evaluation too slow.
Around the third year, rotating test suites would target sparse clues, fine-grained objects, and absent evidence. Their failure records would guide the collection of new human-validated examples, creating a continuing cycle between evaluation, data curation, and model improvement. Selected applications would require each new version to demonstrate defensible evidence, controlled refusal, acceptable robustness, and manageable computational cost before receiving greater workflow authority. Raw accuracy would remain visible, but it would become one part of a broader qualification record. The movement would weaken if evidence-aware rankings remain nearly identical to answer-only rankings, shared formats fail to emerge, or added latency makes these checks impractical.
The contender path also moves from answer-only tests toward evidence-first evaluation. Its distinguishing mechanism is formal adjudication: a second reviewer checks whether the cited clip, region, or page area truly supports the answer. During the first year, benchmarks should add joint answer-and-evidence scores and explicit categories for partial or missing support. Long-context systems will be judged on finding decisive evidence rather than merely processing more frames. Shared evidence formats may begin linking otherwise separate benchmark suites, while human reviewers remain responsible for difficult cases.
The important trigger is a shift by major challenges away from answer-only rankings. If demand for specialized review grows faster than reviewer capacity, evidence checking becomes the main bottleneck. By the second year, informal review could develop into versioned procedures that define acceptable evidence and explain when independent review is required. Automated reviewers would sort straightforward cases, while qualified people resolve disagreements. Better perception and retrieval could reduce this burden, but synthetic evidence labels would still need careful quality checks.
Around the third year, evidence-first evaluation could spread across video, maps, and documents. Systems would retain auditable records, show users the relevant support, and send disputed outputs for review. Composite measures would combine correctness with evidence alignment and suitable refusal, rather than treating a single accuracy score as sufficient. Continuous benchmark refresh and reviewer proficiency testing would be needed because models can adapt to fixed tests. A useful monitoring cue is whether reports publish reviewer agreement, adjudication delay, and human-machine consistency. The path weakens if evidence outputs become unchecked explanations, leading benchmarks remain centered on multiple-choice answers, or automated scoring resolves grounding cheaply enough that no specialist review layer is needed.
The maybe path turns evidence-grounded question answering into a form of mutation testing borrowed from software engineering. An evaluator changes or removes the claimed evidence and checks whether the model changes its answer or confidence. If a decisive clue disappears but the model stays certain, the paired test may reveal shortcut use. In the first year, teams would adapt existing datasets by masking, replacing, or reordering evidence in videos and other visual inputs. Early studies would focus on evidence sensitivity and failures to refuse unsupported questions. The key threshold is replicated evidence that these paired tests measure grounding rather than merely detecting unnatural edits.
Application would initially center on development tools and release checks. Teams could test whether a system remains confident after a supporting frame, object, or page region disappears. Human-reviewed changes would be important because some edits may remove irrelevant details or create unrealistic scenes. By the second year, realistic generative editing could replace obvious masks, while shared mutation scores define the expected response when evidence is absent. Coverage-guided testing could select only the changes most likely to reveal new behavior, reducing repeated computation.
Around the third year, automated groups of models may search for the smallest visual change that breaks an answer or exposes unjustified confidence. Each confirmed failure could become a new test and a targeted training example, creating a cycle of testing, correction, and retesting. If the results remain reproducible and affordable, continuous visual testing could become a routine release gate for selected specialized systems. A strong monitoring cue would be the appearance of semantically validated mutation scores across several data types. The path weakens if edited scenes are often impossible, if remaining context still supports the original answer, or if reliable static grounding tests make repeated counterfactual runs unnecessary.
1-Year / 3-Year Research-Application Infographic
References
- Grounded Question-Answering in Long Egocentric Videos - Authors: Shangzhe Di and Weidi Xie / <See Details on Fugu-MT> / License: CC-BY-4.0
- CG-Bench: Clue-grounded Question Answering Benchmark for Long Video Understanding - Authors: Guo Chen, Yicheng Liu, Yifei Huang, Yuping He, Baoqi Pei, Jilan Xu, Yali Wang, Tong Lu, Limin Wang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- HierDoc: Hierarchical Page-to-Region Evidence Routing for Long-Document Visual Question Answering - Authors: Rongjian Gu, Wengang Zhou, Junyu Xiong, Yonghui Wang, Bing Yin, Bei Wang, Houqiang Li / <See Details on Fugu-MT> / License: CC BY 4.0
- EgoAfford: Task-Oriented Affordance Grounding via Egocentric Referring Segmentation - Authors: Xinyuan Guan, Feifan Chen, Xinyu Zhan, Fu-Cheng Zhang, Cewu Lu, Lixin Yang / <See Details on Fugu-MT> / License: CC BY 4.0
- The First EgoCross Challenge at EgoVis 2026: Cross-Domain Egocentric Video Question Answering - Authors: Yuqian Fu, Tianwen Qian, Yanjun Li, Yu Li, Kunyu Peng, Xu Zheng, Yongqin Xian, Alessio Tonioni, Yanwei Fu, Xiaoling Wang, Danda Paudel, Federico Tombari, Luc Van Gool, Leyi Wu, Yifan Zhao, Jinjie Zhang, Yinchuan Li, Yingcong Chen, Zixu Li, Zhiwei Chen, Zhiheng Fu, Wenbo Wang, Yupeng Hu, Weili Guan, Liqiang Nie, Takuya Murakawa, Toru Tamaki, Yi Wen, Zhenglin Du, Zhengyang Li, Lingling Li, Licheng Jiao, Wenping Ma / <See Details on Fugu-MT> / License: CC BY 4.0