Summary
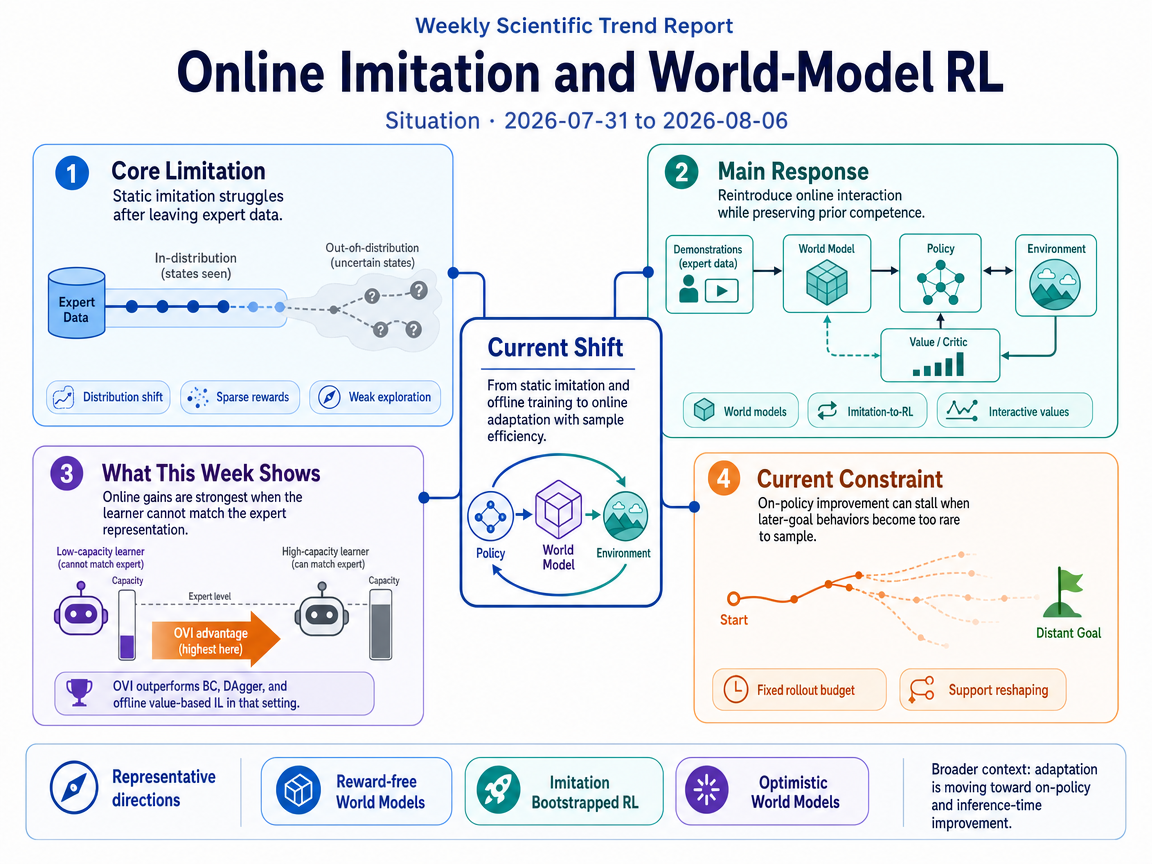
Representative papers converge on a shared limitation of static imitation and standard model-based control: policies struggle with distribution shift, sparse rewards, and weak exploration once they leave the expert data regime. This week's evidence highlights progress toward online adaptation through world models, imitation-to-RL bootstrapping, and value-based interactive imitation learning.
Situation
The representative introductions describe a field moving beyond pure behavioral cloning and offline training. Strong offline imitation methods can exploit large demonstration datasets, but they remain vulnerable to out-of-distribution states, bias accumulation, and failure under small perturbations. The cited response is to reintroduce online interaction while keeping sample efficiency high: Reward-free World Models argues that latent world models can support online imitation without explicit reward modeling, while Imitation Bootstrapped Reinforcement Learning uses a separately trained imitation policy to guide both action selection and Q-value bootstrapping during RL, preserving demonstration-derived competence while improving exploration and recovery from distribution shift.
A second representative thread is that model-based RL still needs better exploration in sparse-reward settings. Optimistic World Models frames this as a limitation of standard world-model training and proposes optimism directly in the learned dynamics rather than relying only on actor entropy. As current-week context, Continual Learning in Transition (arXiv:2608.06216v1) surveys a related pressure in LLM and agent systems: capability development is shifting from static, off-policy parameter updates toward on-policy, inference-time, and harness-level adaptation, reinforcing the broader trend toward systems that continue improving after deployment.
Infographic (English)
Progress
When Does On-Policy Interaction Help? Representational Tradeoffs in Value-Based Imitation Learning <See Details on Fugu-MT>
Introduces OVI, a value-based interactive imitation learning method that is statistically efficient when the learner can represent the expert value function. Compared with the prior view that online interaction broadly helps with distribution shift, it specifies that gains are largest when the learner is less expressive than the expert, outperforming BC, DAgger, and offline value-based IL.
Verifier-Induced Support Reshaping in On-Policy Optimization <See Details on Fugu-MT>
Analyzes how verifier-based on-policy optimization reshapes the reachable support of rewarded trajectories under fixed rollout budgets. Newly shows that continued on-policy improvement can stall when later-goal behaviors become too rare to sample or reinforce, identifying a concrete failure mode for online adaptation.
Outlook
Outlook Summary
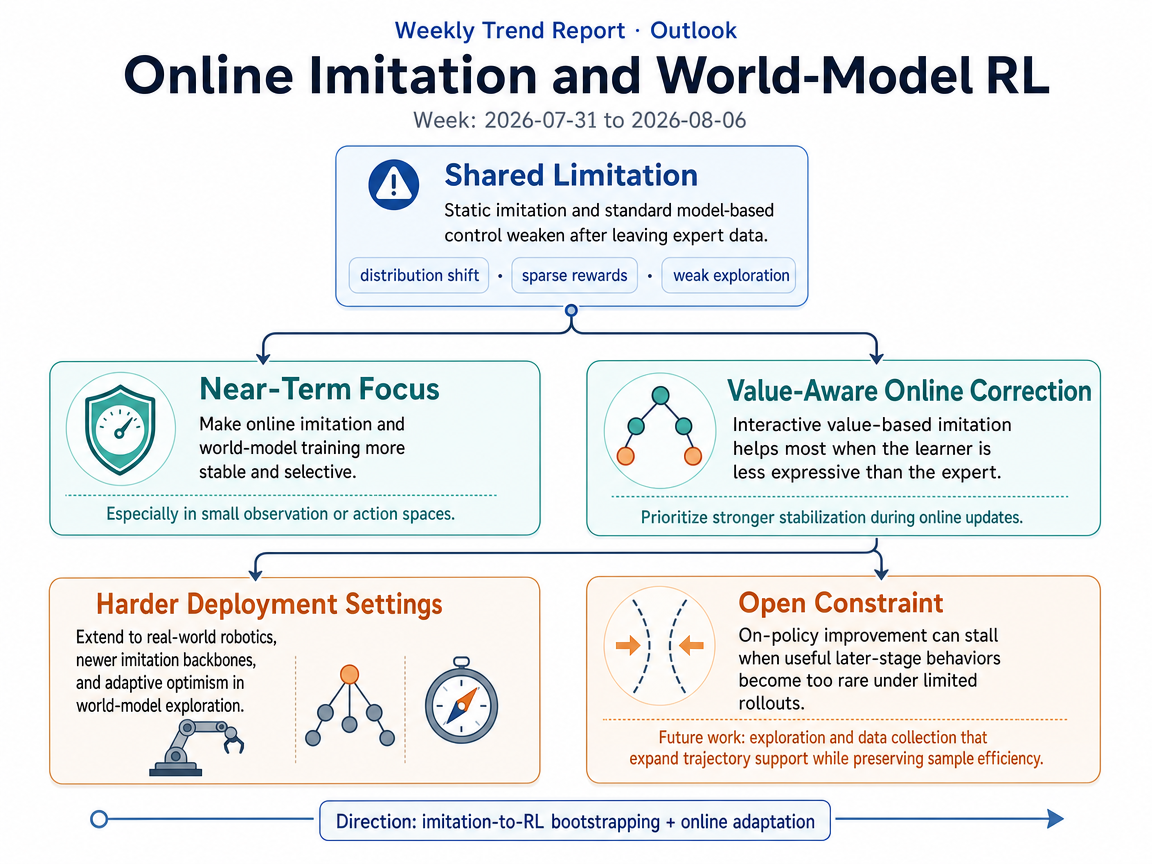
Near-term work will likely make online imitation and world-model training more stable and selective, especially in small observation or action spaces where discriminators can destabilize learning. Value-based interaction appears most useful when the learner is less expressive than the expert. Research will also move toward physical robots, newer imitation methods, and world models with adaptive exploration bias. A key constraint is that limited rollouts can make useful later-stage behavior too rare, so data collection must preserve trajectory coverage without sacrificing sample efficiency.
Infographic (English)
Three-Year Movement
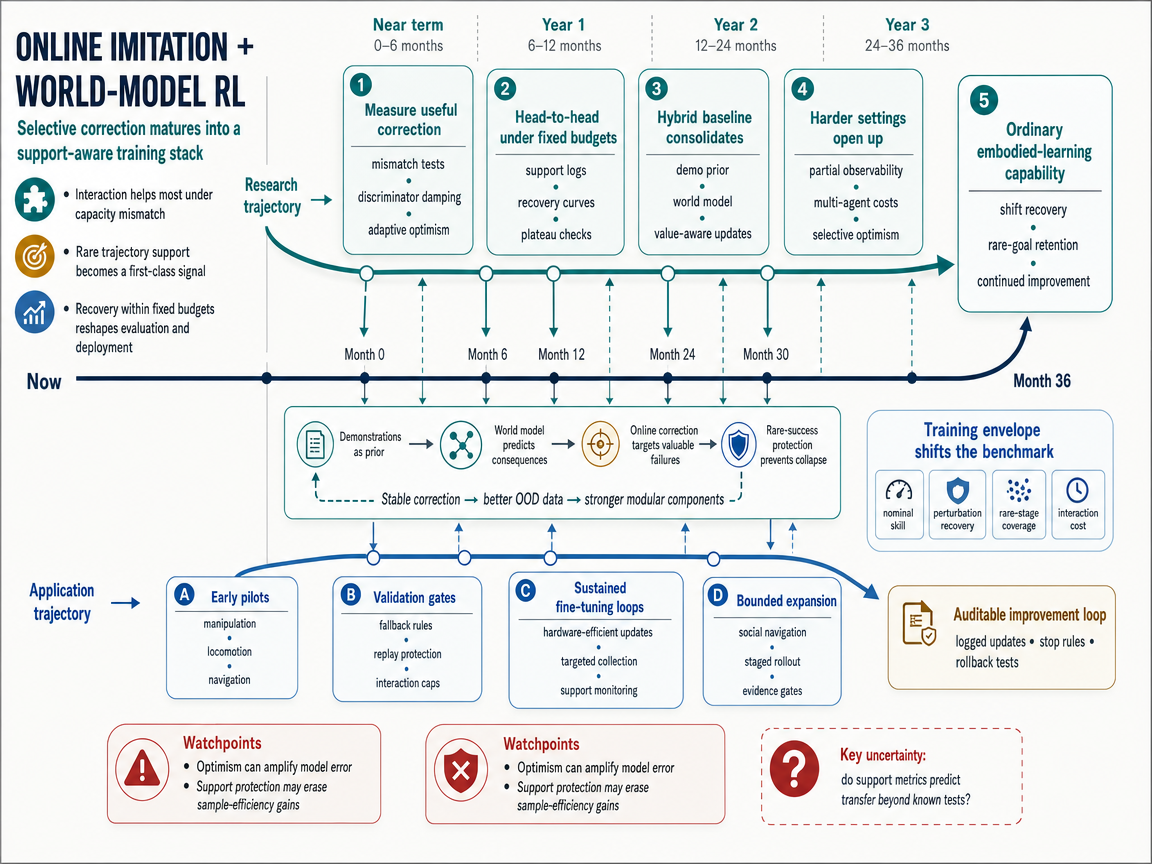
Over three years, the standard path moves toward a common training recipe for selective online correction in embodied systems. Near-term studies will build on the finding that interaction helps most when the learner cannot fully represent expert behavior. The central mechanism combines demonstrations as an initial guide, a learned world model that predicts consequences, and online interaction reserved for valuable corrections.
In the first year, researchers will test how this combination behaves under limited demonstrations and rollout budgets. They will address discriminator instability in small observation or action spaces and examine adaptive optimism, which temporarily encourages a world model to explore outcomes hidden by sparse rewards. Studies will also measure trajectory support, meaning whether the learner continues to visit rare states needed for later task stages. A useful monitoring cue will be repeatable evidence that replay or targeted curricula prevent learning plateaus without sharply increasing interaction requirements.
In the second year, successful components should consolidate into a shared baseline for robot learning. Demonstration pretraining will provide the initial behavior, while world-model planning and value-aware correction will guide later adaptation. Teams will compare which components remain necessary as demonstration quality, controller capacity, and rollout budgets change. Physical-robot experiments should then use sustained fine-tuning loops in which safer corrections generate useful new data, and that data improves later corrections.
By the third year, this recipe could extend to partially observed or multi-agent tasks such as social navigation. Evaluation should measure recovery after distribution shifts, preservation of rare skills, and continued improvement after deployment. If results hold across several physical systems, selective correction could become routine embodied-learning infrastructure by Months 30–36. This path would weaken if optimism creates persistent model errors, support protection consumes too much data, or physical pilots repeatedly fail to reproduce benchmark gains.
The contender path expects evaluation practice to change alongside online imitation methods. Its mechanism resembles flight-envelope testing: a system is judged not only on a normal task, but also on whether it retains key behavior and recovers after controlled disturbances. This is a staged-testing analogy rather than a claim that learned robots can receive aircraft-style certification.
In the first year, researchers will make this training envelope measurable under matched demonstration and interaction budgets. Comparisons will track later-stage visitation, rare successes, and recovery after online updates. Results will be separated by the capability gap between learner and expert because value-aware interaction appears especially useful for weaker learners. Researchers will also test whether internal support measures capture task-relevant behavior rather than rewarding aimless novelty. The main monitoring cue will be the appearance of benchmark suites that require fixed-budget recovery curves or support-retention results alongside average performance.
In the second year, widely used suites could standardize disturbance classes, budget accounting, and learner–expert mismatch categories. Better logging should reveal when online updates quietly remove access to rare but necessary trajectory stages. Algorithms could then redirect rollouts toward endangered stages, replay rare experiences, or reduce exploration when coverage contracts. Robot laboratories may place these checks inside automated validation pipelines, with failed checks pausing updates or restoring a demonstration-derived controller.
By the third year, leading evaluations should compare nominal competence, disturbance recovery, and interaction cost without collapsing them into one score. Held-out shifts and hardware trials will test whether support measures predict real transfer rather than overfitting to familiar disturbances. In selected manipulation and navigation settings, strong systems may be expected to show bounded online improvement before their operating conditions expand. The scenario weakens if support measures predict recovery no better than final task performance, if embodied experiments do not reproduce support loss, or if richer tests leave method rankings unchanged.
The maybe path links online correction to an assurance process modeled loosely on post-deployment incident monitoring. Demonstrations serve as narrow initial trials, unexpected distribution shifts become reportable incidents, and a predefined correction plan controls how a system may recover. The analogy supports auditable learning, but it does not treat an adaptive robot as a static product.
In the first year, researchers will define reliability tests for learner–expert mismatch and trajectory coverage under fixed rollout budgets. They will also address discriminator instability in low-dimensional tasks and test whether adaptive optimism can be limited and logged. The intended result is a bounded-correction package with permitted update rules, recovery criteria, and rollback tests. Early application work will emphasize monitoring and controlled pilots rather than unrestricted adaptation. A useful monitoring cue will be a standards workshop or buyer template that explicitly requests evidence of recovery from shifts using the new coverage measures.
In the second year, successful tests could become reference conformance kits connecting correction software to assurance workflows. Organizations may define update envelopes that limit when a policy can change, how much data it may collect, and when it must revert. Shared incident reports could reveal recurring forms of real-world distribution shift and guide improvements to world models. The scenario crosses an important threshold if an assessment body or major buyer accepts logged online correction as positive safety evidence.
By the third year, incident evidence, correction methods, and shared test tools could form a reinforcing cycle. Modular systems would make the imitation component, world model, and update process separately inspectable. Deployment could then expand from fenced industrial sites to hospital corridors or controlled pedestrian areas, with evaluation centered on recovery and safe rollback. The main caveat is that each update may be treated as a major system modification requiring full reassessment. This path would also weaken if coverage measures fail to reproduce, public pilots remain unstable, or no shared incident-reporting structure emerges.
1-Year / 3-Year Research-Application Infographic
References
- Imitation Bootstrapped Reinforcement Learning - Authors: Hengyuan Hu, Suvir Mirchandani, Dorsa Sadigh / <See Details on Fugu-MT> / License: CC-BY-4.0
- Reward-free World Models for Online Imitation Learning - Authors: Shangzhe Li, Zhiao Huang, Hao Su, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Optimistic World Models: Efficient Exploration in Model-Based Deep Reinforcement Learning - Authors: Akshay Mete, Shahid Aamir Sheikh, Tzu-Hsiang Lin, Dileep Kalathil, P. R. Kumar, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Continual Learning in Transition - Authors: Zhiyan Hou, Dan Zhang, Tao Feng, Liyuan Wang, Wei Li, Xiangzhao Hao, Hongyan An, Junfeng Fang, Haokai Ma, Zhaohui Xu, Haiyun Guo, Jinqiao Wang, Tat-Seng Chua / <See Details on Fugu-MT> / License: CC BY 4.0