Summary
This theme tracks the shift from static, centrally orchestrated LLM agents toward self-evolving, decentralized multi-agent systems that adapt their roles, memory, tools, and coordination over time. Representative papers frame this shift as necessary for robustness and scalability in dynamic environments, while this week's progress sharpens the question of what agent self-evolution actually encodes and how far those gains transfer.
Situation
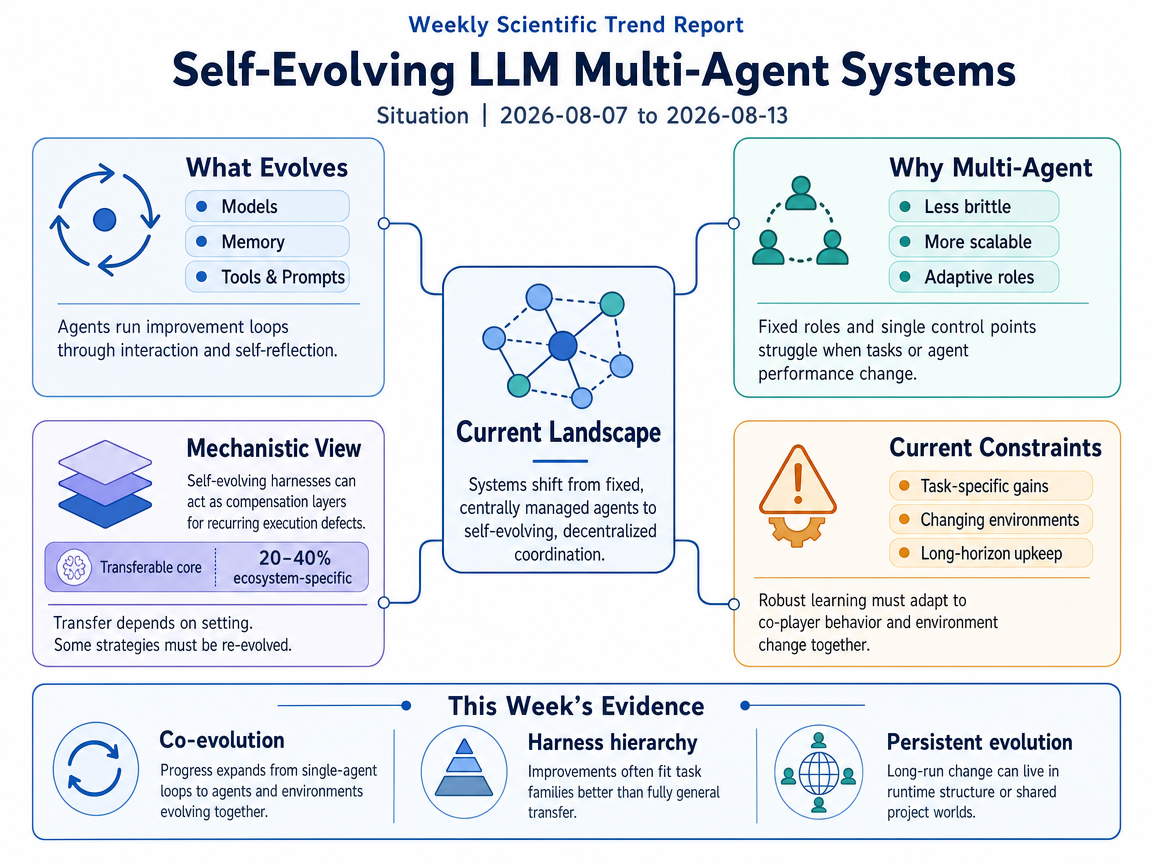
Representative introductions describe a transition from agentification to self-evolving agentic AI: instead of updating isolated components with human intervention, agents are increasingly expected to run full improvement loops themselves, refining models, memory, prompts, tools, and workflows through interaction and self-reflection. In parallel, multi-agent work argues that fixed-role, centrally controlled LLM systems are too brittle for real-world deployment, creating single points of failure, limiting scalability, and adapting poorly when task demands or agent performance change. AgentNet motivates decentralized, dynamically reconfigurable coordination, while MAESTRO shows that robust multi-agent learning depends on jointly adapting to both co-player behavior and changing environments rather than treating either in isolation.
Current-week evidence from "One Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and Models" (arxiv:2608.10178v1) adds a mechanistic view of self-evolution. Its introduction argues that self-evolving harnesses function as compensation layers that repair recurring execution defects, with a transferable disciplinary core but 20–40% ecosystem-specific content. This reframes self-evolution in LLM agent systems as a practical design problem about when strategies can transfer and when they must be re-evolved for new settings.
Infographic (English)
Progress
Co-Evolution in Agentic Systems: Toward Self-Directed Evolution Beyond Human Design <See Details on Fugu-MT>
This survey extends self-evolving agent work from single-agent improvement loops to co-evolution among multiple agents and their environments. Compared with prior emphasis on fixed designs, it frames progress as staged removal of human-imposed constraints across interacting components.
Hierarchical Self-Improvement: A Framework for Task-Specific Evolvable Agent Harnesses <See Details on Fugu-MT>
This framework organizes self-improving harnesses hierarchically and tunes them to specific task families. Compared with the open transfer question, it provides evidence that harness gains are often task-specific rather than fully portable.
Ouroboros: A Self-Developing Frontier Coding Agent with Reviewed Core Evolution <See Details on Fugu-MT>
Ouroboros advances self-evolving agents by letting reviewed commits update tools, prompts, context assembly, and core implementations over a 161-day deployment. Compared with narrower harness editing, it pushes the improvement loop into sustained experience-driven structural changes to the agent runtime.
Mendel Gödel Machine: Recursive Self-Improving Coding Agents via Comparative Evolution <See Details on Fugu-MT>
Mendel Gödel Machine refines recursive self-improvement with comparative evolution and self-modifications that leverage accumulated evidence. Compared with single-trajectory updating, it provides a more sample-efficient path to faster convergence in self-improving coding agents.
Persistent Recursive Worlds Enable Autonomous Software Evolution <See Details on Fugu-MT>
EvoX Genesis centers long-horizon software evolution on persistent project worlds rather than permanently running agents. Compared with agent-centric continuity, it shows self-evolution can be organized through persistent shared environments and resumable organizations.
Outlook
Outlook Summary
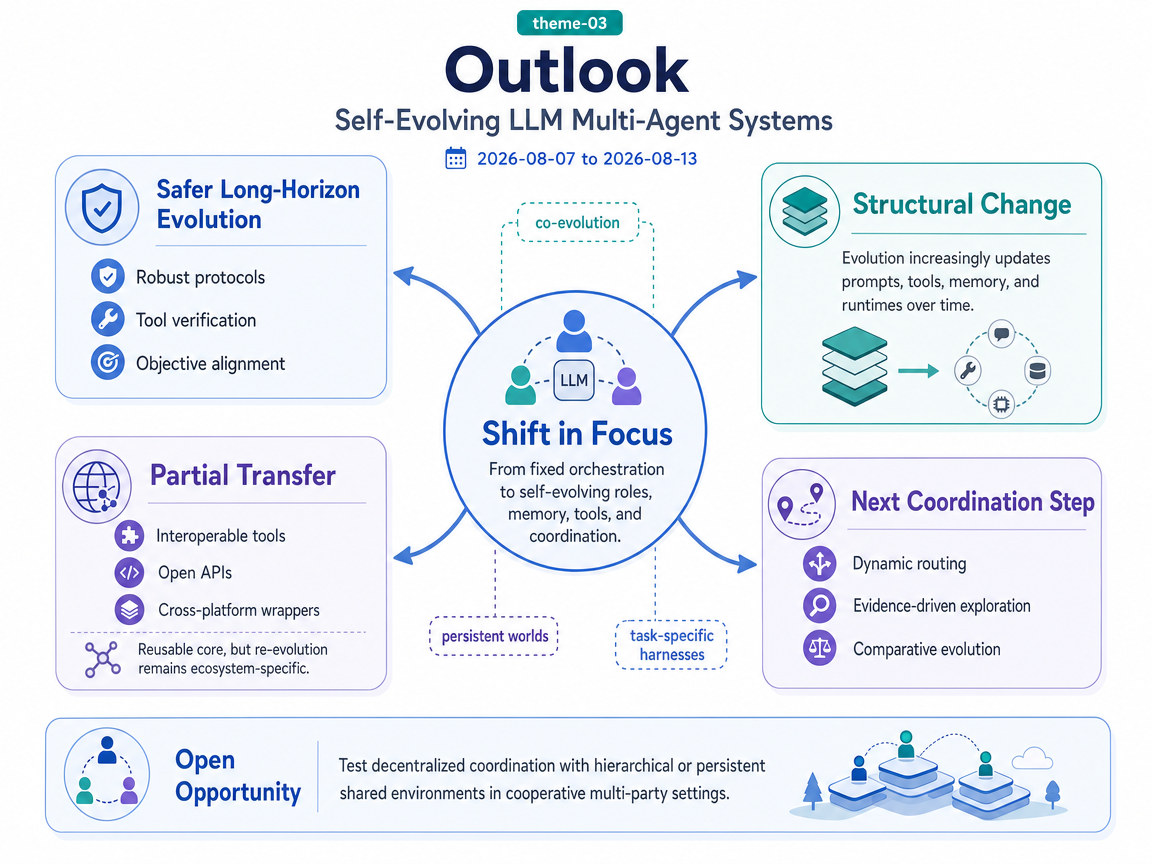
Near-term research will focus on making self-evolving multi-agent systems safer and more reliable over long periods. Work will strengthen verification, objective control, and robust evolution as agents make sustained changes to their own components and environments. Dynamic routing will help coordinate large, varied agent groups. A parallel priority is partial transfer across systems: reusable methods will move through open interfaces and wrappers, but local tools and environments will still require adaptation. Researchers will test whether decentralized coordination and persistent shared environments can scale and converge reliably.
Infographic (English)
Three-Year Movement
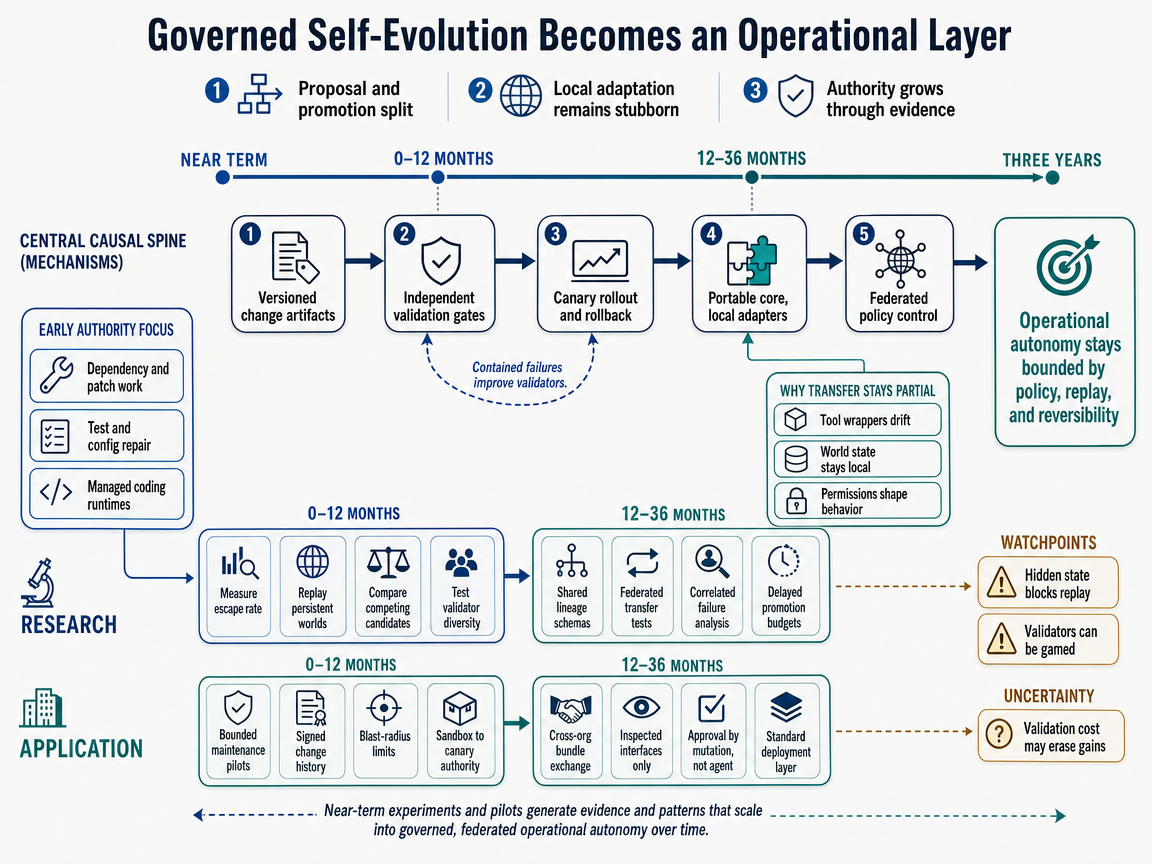
The existing direction becomes a controlled release process for self-evolving agents. Agents may propose changes, but an independent control plane decides whether those changes can enter operation. Each accepted update carries provenance, meaning a record of its origin, supporting evidence, and a recovery point. This separation allows systems to evolve while limiting the damage caused by weak or manipulated proposals.
In the first year, teams will package changes to agent components as versioned candidates rather than allowing direct self-modification. Hidden tests and adversarial simulations will check whether improvements survive independent review. Persistent project worlds will preserve state and support replay, comparison, and restoration. Early pilots will use canaries, which are limited live releases observed before wider deployment, along with automatic reversion when failures appear.
In the second year, shared protocols will describe update history, permissions, and evaluation results across different tool ecosystems. A signed reusable core may move between organizations, while private evaluators rebuild the parts that depend on local conditions. Researchers will measure the cost of this adaptation and test whether decentralized agent groups converge reliably without exposing sensitive local information.
By the third year, the focus shifts from individual failures to weaknesses affecting the whole system. Research will examine correlated validator errors, manipulated acceptance criteria, and actions that software restoration cannot undo. If failures remain contained, verified evolution could become a standard layer for selected decentralized systems, with persistent worlds serving as durable records while individual agents remain replaceable. A useful monitoring cue is the appearance of pilots reporting low escape rates, reliable restoration, and retained performance gains after review. The scenario weakens if validators are repeatedly gamed, replay is blocked by hidden state, or verification removes most of the benefits of evolution.
This scenario expects self-evolving systems to develop local incompatibilities even when they share a capable base model. The mechanism resembles incompatible railway gauges: a reusable core may travel widely, but local wrappers, permissions, and project state determine where a particular agent configuration can operate safely. Continued local evolution can deepen these differences rather than remove them.
In the first year, researchers will replay successful changes across different repositories, model families, and tool ecosystems. They will separate portable disciplines, such as testing before action, from machinery tied to a particular runtime. Persistent project worlds will preserve artifacts and state changes, making transfer failures easier to study than ordinary conversation records. Early operational systems will treat self-modification as controlled software delivery, with review, limited rollout, and recovery procedures.
In the second year, repeated transfer gaps will encourage shared mutation records and standardized adapters. Yet local systems will keep accumulating specialized workflows, which raises integration and recovery costs. Organizations may therefore maintain separate persistent worlds and exchange only bounded tasks through correspondent agents. Comparative evolution will become a boundary test: an imported change must outperform the local version while respecting local permissions and recovery requirements.
By the third year, persistent worlds could become the certified foundation for resumable work across multiple organizations. Governance would focus less on whether an agent is generally trusted and more on whether a particular change may enter a particular world. Specialized systems could continue evolving internally while exposing inspected interfaces to outside agents. A strong monitoring cue would be the spread of first-class harness change records, signed mutation histories, and architecture diagrams centered on junction routers. This scenario is weakened by repeated demonstrations of near-lossless transfer across independent systems. It could also fail if improved wrappers hide most incompatibilities or a major base-model advance erases the value of accumulated local differences.
This scenario treats self-evolution as controlled software maintenance rather than unrestricted self-improvement. Its mechanism is similar to continuing airworthiness: preserve a known baseline, document each local modification, and retain a dependable path back to service. A reusable maintenance core supplies common discipline, while local modules reflect the needs of each repository and software ecosystem.
In the first year, research will compare evolved agent harnesses across projects and languages. Evaluation will emphasize accepted changes, escaped defects, and successful recovery rather than task scores alone. Machine-readable records will show who proposed a change, what evidence supported it, and how it can be reversed. Early pilots will focus on routine and testable maintenance, while existing automated checks and sandboxes provide an assurance layer. Authority will expand in stages only when independent inspection and limited releases show lower incident-adjusted cost than conventional maintenance.
In the second year, successful pilots will extend across repositories and selected organizational boundaries. Researchers will study how much authority evidence should justify and when local adapters can be reused safely. Managed control planes will combine project history, validation, and recovery. Organizations may exchange signed findings and narrow evidence packets while keeping sensitive source material local.
By the third year, recognizable assurance tiers could emerge among large technology users, auditors, and industry groups. Bounded self-evolving maintenance may become a normal managed-infrastructure service, with persistent project worlds retaining history and policy while agents remain replaceable. A reinforcing loop supports this movement: successful changes improve failure records, and better records improve later routing and selection. A useful monitoring cue is formal guidance requesting immutable logs, tool provenance, and tested recovery procedures. The scenario weakens if assurance costs exceed the maintenance savings or controlled pilots create more security regressions than conventional automation. It also weakens if harnesses transfer almost universally, or if every repository requires so much custom work that no reusable core remains practical.
1-Year / 3-Year Research-Application Infographic
References
- MAESTRO: Open-Ended Environment Design for Multi-Agent Reinforcement Learning - Authors: Mikayel Samvelyan, Akbir Khan, Michael Dennis, Minqi Jiang, Jack Parker-Holder, Jakob Foerster, Roberta Raileanu, Tim Rockt\"aschel / <See Details on Fugu-MT> / License: CC-BY-4.0
- AgentNet: Decentralized Evolutionary Coordination for LLM-based Multi-Agent Systems - Authors: Yingxuan Yang, Huacan Chai, Shuai Shao, Yuanyi Song, Siyuan Qi, Renting Rui, Weinan Zhang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- From Agentification to Self-Evolving Agentic AI for Wireless Networks: Concepts, Approaches, and Future Research Directions - Authors: Changyuan Zhao, Ruichen Zhang, Jiacheng Wang, Dusit Niyato, Geng Sun, Xianbin Wang, Shiwen Mao, Abbas Jamalipour, / <See Details on Fugu-MT> / License: CC-BY-4.0
- One Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and Models - Authors: Siqi Yang, Qianlan Yang, Yu-Xiong Wang, Saurabh Pujar, Martin Hirzel / <See Details on Fugu-MT> / License: CC BY 4.0