Summary
This week's reinforcement learning work focuses on making RL systems more general, computationally efficient, and stable under demanding training regimes. Progress spans LLM-generated self-play environments, sim-to-real adversarial policy transfer, and refined diagnosis of deep Q-learning instabilities, complementing representative work on unified MCTS benchmarks, GPU-accelerated game infrastructure, and high update-ratio optimization.
Situation
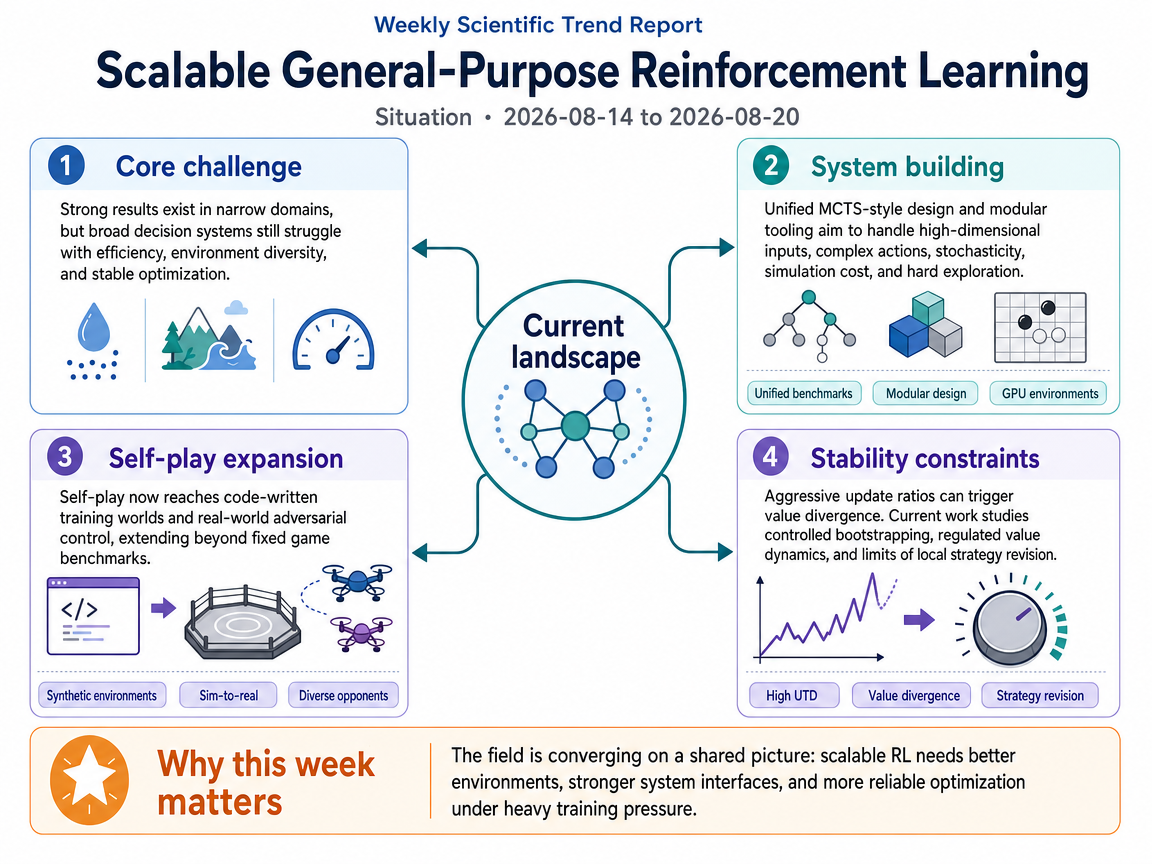
Representative introductions frame a common problem: strong RL results exist in individual domains, but broadly deployable decision systems still struggle with data efficiency, environment diversity, and brittle optimization. LightZero argues that general decision intelligence needs unified MCTS/MuZero-style algorithms and modular system design to cope with high-dimensional observations, complex action spaces, stochasticity, simulation cost, and hard exploration. Ludax complements this by emphasizing that progress in games and learning depends on diverse yet computationally efficient environments, motivating a GPU-accelerated board-game DSL for rapid RL experimentation.
A second pressure point is training stability when sample efficiency is pushed aggressively. "Dissecting Deep RL with High Update Ratios" argues that increasing updates per environment step exposes optimization-driven value divergence—not just simple early-data overfitting—making stable high-UTD off-policy RL a central systems issue. As current-week evidence, "What is Missing from AI Post-Training AI: An Empirical Analysis" (2608.19072v1) extends the broader agent-learning discussion by distinguishing execution-level iteration from strategy-level revision, finding that agents can optimize locally while failing to reconsider overall strategy—an adjacent concern for RL research seeking more adaptive learning loops.
Infographic (English)
Progress
PureTD: Reinforcement Learning for Backgammon Money Games with No Evaluation-time Search <See Details on Fugu-MT>
PureTD: Reinforcement Learning for Backgammon Money Games with No Evaluation-time Search: 評価時間検索なしの設定で,手三郎のTDGammonをバックギャモンマネーゲームとして再検討する。 チェッカープレイと立方体アクションは、手書きのロジックが最小限で、専門家の機能を持たないセルフプレイ強化学習(RL)によって、ゼロから学習される。 It connects to Reinforcement Learning / Reinforcement Learning through the paper's concrete task, method, evidence, or application setting.
SPADE: Self-Play in Adaptive Synthetic Executable Environments <See Details on Fugu-MT>
SPADE introduces a self-play RL framework where an LLM writes executable Gym-style training environments as code, broadening RL environment infrastructure beyond fixed benchmarks. Rather than relying on hand-built or static environments, it adds document-grounded synthetic training worlds with accumulated environment memory.
AgilePE: Autonomous UAV Pursuit-Evasion via Self-Play Reinforcement Learning <See Details on Fugu-MT>
AgilePE extends self-play RL to autonomous UAV pursuit-evasion, combining agile low-level control, adversarial policy optimization via prioritized fictitious self-play, and sim-to-real deployment. It demonstrates that diverse-opponent self-play tactics can transfer zero-shot from simulation to real two-agent aerial interaction, moving beyond game-only self-play evidence.
Understanding and Stabilizing Deep Q-Learning via Controlled Bootstrapping and Regulated Value Dynamics <See Details on Fugu-MT>
This work systematically analyzes deep Q-learning instabilities, identifying reward-bootstrapping traps and characteristic parameter-spike dynamics. Beyond earlier broad diagnoses of value divergence, it proposes controlled bootstrapping and regulated value dynamics, reporting improved stability on Atari-100K and Procgen.
Outlook
Outlook Summary
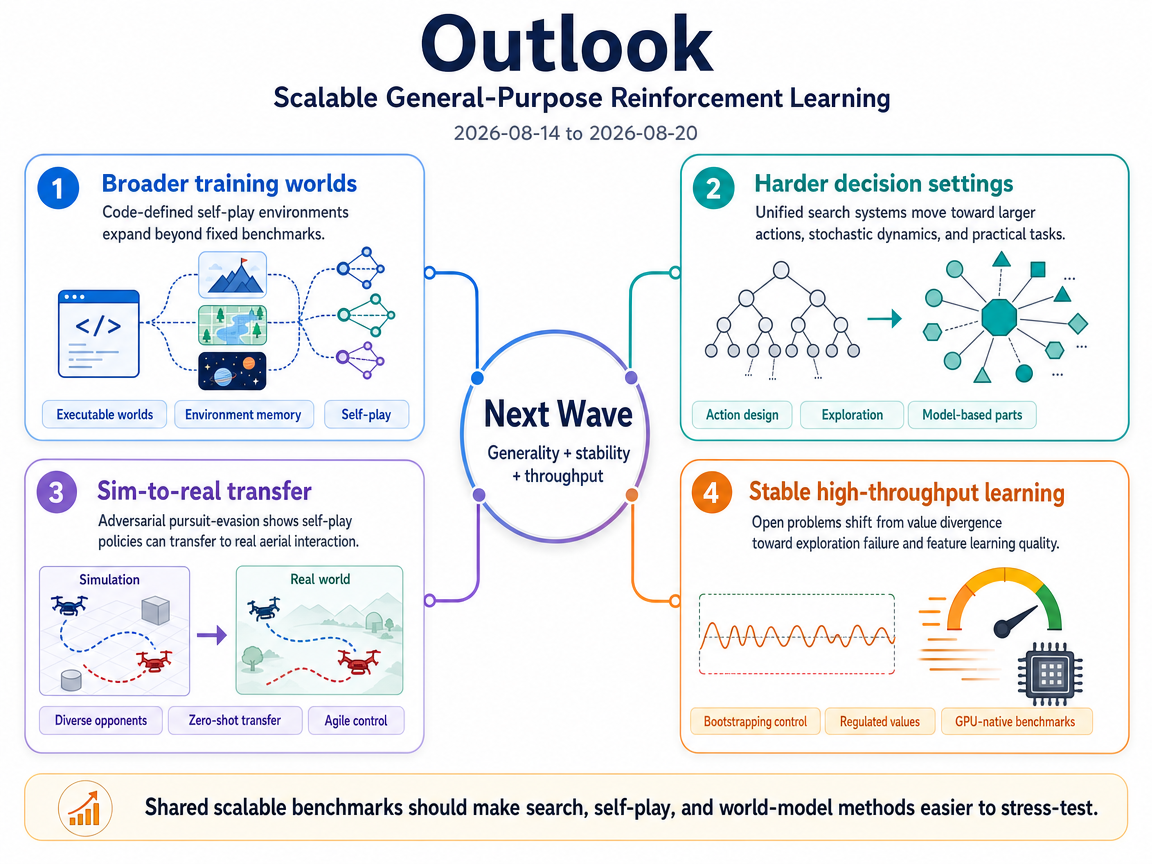
General-purpose reinforcement learning is moving toward unified search and model-based systems that can handle larger or hybrid action spaces, greater randomness, and more practical tasks. Programmable self-play worlds and simulation-to-reality experiments are widening the range of training settings. However, progress now depends as much on stability and throughput as on algorithmic reach. High update-to-data training still faces value divergence, weak exploration, and poor feature learning. GPU-native environment tools and shared scalable benchmarks should help researchers expose these failures earlier while testing search, self-play, and learned-world-model methods under comparable conditions.
Infographic (English)
Three-Year Movement
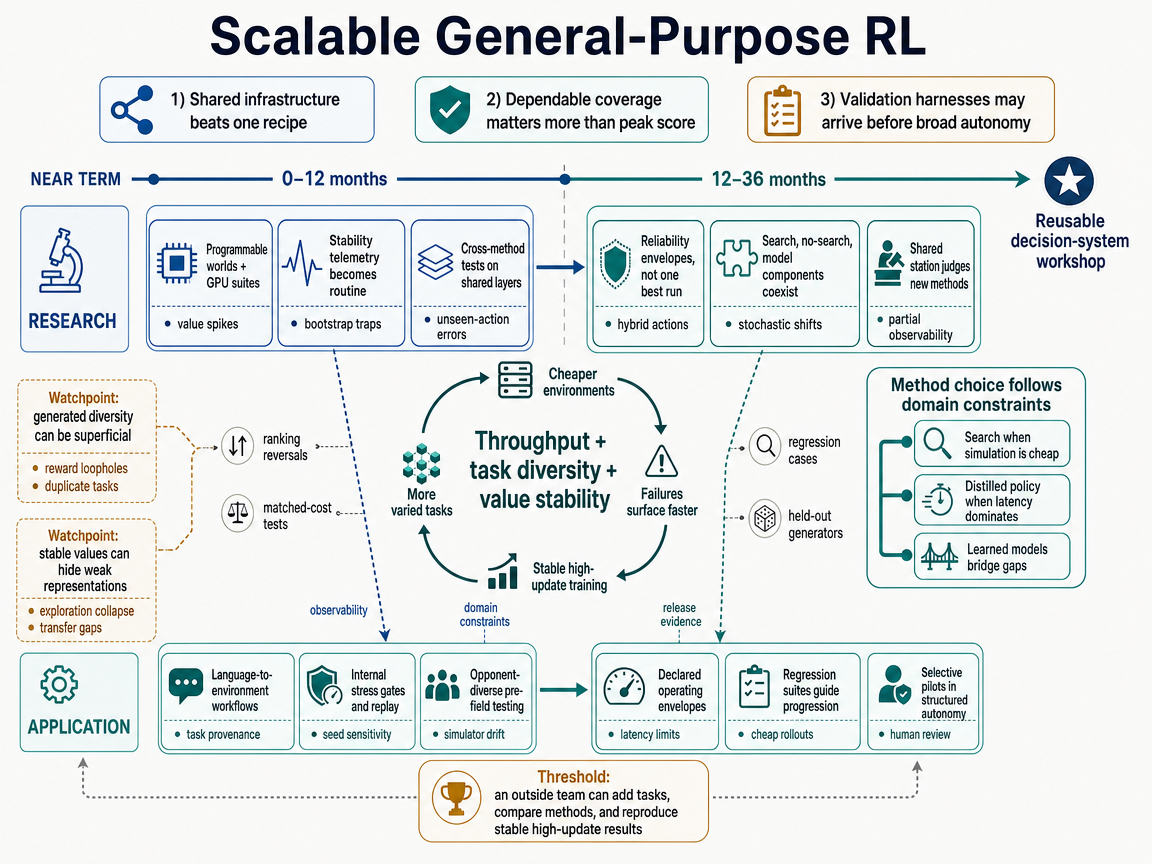
The standard path leads toward a broad reinforcement-learning workshop rather than a single dominant algorithm. Its mechanism is a feedback loop between cheaper environments, better diagnostics, and more stable learning. Faster experiments expose overestimation and exploration collapse earlier, while improved controls make it practical to test a wider range of environments. Recent systems support this direction by making executable worlds programmable, preserving search-free alternatives, and extending self-play toward physical control.
During the first year, researchers should connect generated tasks and GPU-native simulators to existing search or self-play systems. Reports will increasingly show internal failure signals alongside task scores. These signals may include extreme value estimates, errors on unfamiliar actions, and unstable bootstrapping, where a learner repeatedly relies on its own inaccurate predictions. Feature constraints and regulated value updates should then become standard benchmark options. A key threshold will be whether an outside team can add a task family, compare several method types, and run stable high-update training without months of custom engineering.
In the second year, shared environment layers should support harder action spaces, random dynamics, and explicit exploration tests. Search will remain attractive when simulation is cheap, while search-free policies will matter when runtime planning is too slow. Applied teams should also adopt environment compilers and value-trace inspection as routine tools, although human review will remain necessary to catch loopholes in generated tasks.
By the third year, attention should shift from isolated policy designs to complete decision-system workshops. These systems would combine environment construction, accelerated simulation, several training approaches, and stability monitoring through modular interfaces. A useful monitoring cue is independent reproduction of physical transfer under unfamiliar opponents or changed dynamics. If that occurs, structured pilots in aerial and mobile robotics could expand modestly. The path would weaken if generated tasks remain easy to exploit, stability controls require extensive retuning, or physical performance collapses outside the original test conditions. Task quantity can create only superficial diversity, and stable value curves can still hide weak internal representations.
The contender path changes how reinforcement-learning systems are compared. Instead of emphasizing the highest score on one fixed benchmark, researchers would measure a reliability envelope: the range of tasks and operating conditions in which a system remains dependable. The mechanism is similar to capacity testing, because a method receives credit for performance that survives changes in seeds, opponents, and computing limits. Faster environments and better telemetry make this broader testing affordable enough to influence system design.
During the first year, benchmark groups should assemble stress-evaluation tracks from executable task generation, accelerated simulation, and diagnostics for unstable learning. Reports will separate peak performance from typical and worst-case behavior. They should also disclose the runtime cost of evaluation-time search. An important trigger would be a reproducible ranking reversal in which a lower-scoring method stays reliable under task variations while the apparent leader fails. If that happens, benchmark maintainers may introduce coverage-adjusted scores with visible submeasures. The threshold is crossed when a reliability envelope becomes an expected part of a serious result rather than an optional supplement.
In the second year, multiple laboratories should test which stresses actually predict transfer to selected robotics and control trials. Generated tests and fixed canonical tests would remain separate so that novelty does not obscure validity. Physical failures could then inform new scenarios, creating a feedback loop in which broader testing increases demand for better environment tools, and those tools lower the cost of further testing. Independent reruns and clear task provenance would be important monitoring cues.
By the third year, systems should be built for declared operating regions rather than unrestricted generality. Search could remain useful where simulation is affordable, while stable policies or learned models could take larger roles under tight latency. Shared observability tools would reveal when an opponent, environment, or failure pattern moves outside the tested region. If reliability scores consistently predict selected real outcomes, validated scenario suites could become continuous development gates before additional physical trials. This path would weaken if generated tasks are superficial, ranking reversals cannot be reproduced, or stress scores fail to predict held-out behavior. Reliability profiles must remain domain-specific because designed tasks can be exploited and may not represent conditions after deployment.
The maybe path treats the first broadly useful reinforcement-learning platform as a testing harness rather than a broadly autonomous agent. Its mechanism resembles software fuzzing. Generated environments and opponents provide unusual stress inputs, while reproducible behavioral failures act like crashes that engineers can investigate. Stability telemetry then helps distinguish planning errors from failures caused by learning dynamics.
During the first year, research groups should connect constrained environment generation, batched simulation, and deterministic replay in continuous validation pipelines. They will need more than executable code because generated tasks may have impossible dynamics or misleading rewards. Automated validation and human review should therefore become part of the pipeline. Stronger systems would reduce a failure to a simple reproducible case, classify it, and preserve it in a versioned regression suite. Held-out cases must remain separate from retraining tasks. The first major threshold is evidence that the harness finds consequential failures that fixed benchmarks miss and that an independent team can reproduce those failures more cheaply than manual testing.
In the second year, successful pilots should converge on portable environment formats and standard policy interfaces. Independent evaluators could rerun scenario packs across different simulators to determine whether a failure is general or merely an engine artifact. Research should also separate poor planning from weak representations and unstable value updates. A strong monitoring cue would be repeated correlation between synthetic failures and problems later observed in constrained physical tests.
By the third year, a common assurance layer could test search-based planners, learned world models, and search-free policies under the same scenario controls. Rotating held-out suites and recorded task provenance would make it harder for developers to optimize only for known tests. Broader testing would reveal more failures, which would motivate better templates and observability, making the resulting evidence more credible. Passing the harness would support progression to further trials but would not prove safety. The scenario would weaken if generated environments are often invalid, interfaces remain fragmented, or synthetic failures have little connection to physical outcomes. The fuzzing analogy also has limits because reinforcement-learning policies can change during testing, and behavioral coverage lacks the completeness measures available for conventional code.
1-Year / 3-Year Research-Application Infographic
References
- LightZero: A Unified Benchmark for Monte Carlo Tree Search in General Sequential Decision Scenarios - Authors: Yazhe Niu, Yuan Pu, Zhenjie Yang, Xueyan Li, Tong Zhou, Jiyuan Ren, Shuai Hu, Hongsheng Li, Yu Liu / <See Details on Fugu-MT> / License: CC-BY-4.0
- Dissecting Deep RL with High Update Ratios: Combatting Value Overestimation and Divergence - Authors: Marcel Hussing, Claas Voelcker, Igor Gilitschenski, Amir-massoud Farahmand, Eric Eaton / <See Details on Fugu-MT> / License: CC-BY-4.0
- Ludax: A GPU-Accelerated Domain Specific Language for Board Games - Authors: Graham Todd, Alexander G. Padula, Dennis J. N. J. Soemers, Julian Togelius, / <See Details on Fugu-MT> / License: CC-BY-4.0
- What is Missing from AI Post-Training AI: An Empirical Analysis - Authors: Joy Jia Yin Lim, Xin Huang, Hao Peng, Yaxi Lu, Xin Cong, Zhong Zhang, Maosong Sun, Yankai Lin / <See Details on Fugu-MT> / License: CC BY 4.0