Summary
This week's theme centers on evaluating and improving embodied manipulation in contact-rich settings where vision-only supervision and narrowly collected robot data are insufficient. Representative papers highlight three complementary needs: benchmarks for affordance generalization, human demonstration interfaces that capture tactile signals, and scalable physics-based pipelines that expand training data across embodiments and conditions.
Situation
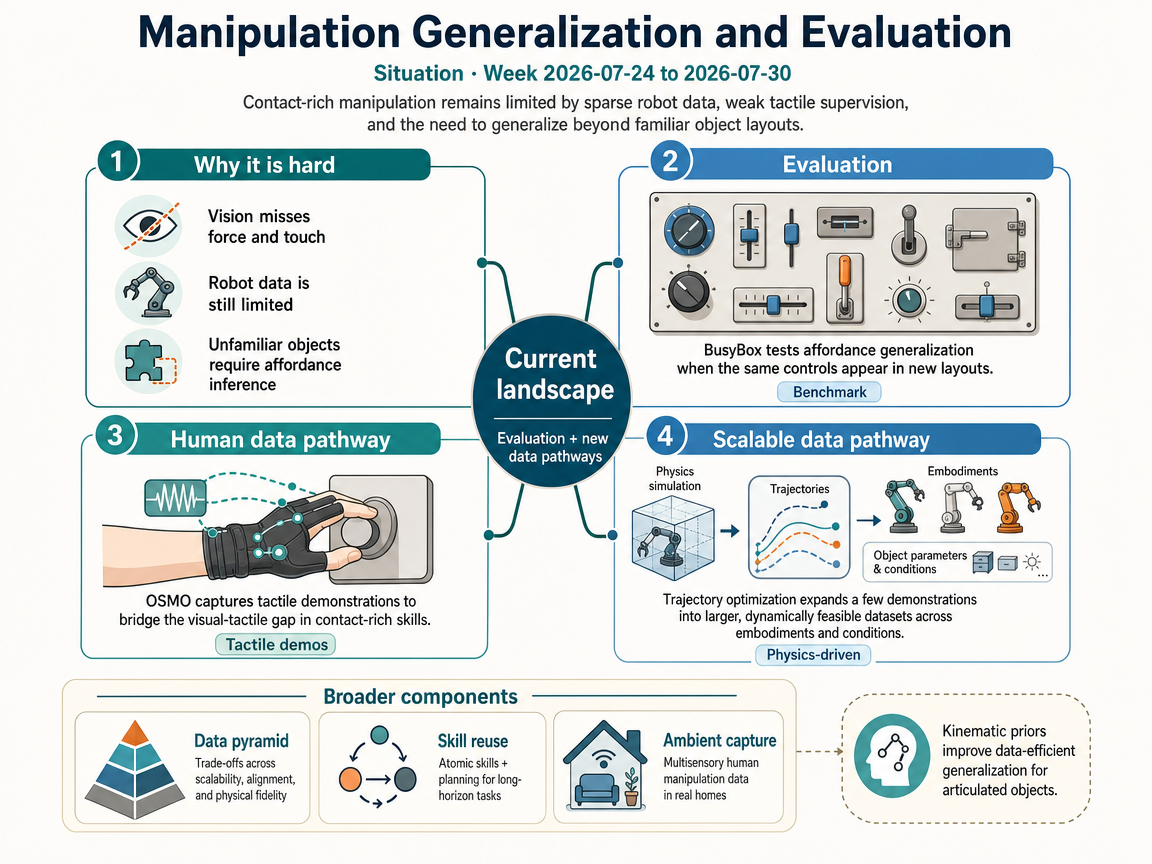
Representative introductions frame contact-rich manipulation as a core bottleneck for generalist robot policies. Existing robot datasets remain limited relative to the data regimes behind foundation models, while internet or egocentric video often lacks the action and tactile signals needed for reliable transfer. Manipulation in human environments also demands more than in-distribution task execution: robots must infer affordances of unfamiliar objects and configurations, and must handle force-sensitive interactions that vision alone cannot fully observe.
Against that backdrop, current work pairs evaluation with new data pathways. BusyBox proposes a modular physical benchmark for testing affordance generalization when the same underlying controls appear in rearranged layouts; OSMO argues that human tactile demonstrations can bridge the visual-tactile gap for contact-rich skills; and physics-driven trajectory optimization turns a small set of demonstrations into larger, dynamically feasible datasets that vary embodiment and physical parameters. The broader embodied-data discussion is consistent with this direction, highlighting growing interest in combining heterogeneous data sources while trading off scalability, robot alignment, and physical fidelity.
Infographic (English)
Progress
Data Pyramid for Embodied Manipulation <See Details on Fugu-MT>
Organizes the embodied manipulation data ecosystem as a five-layer pyramid, systematizing the trade-offs among scalability, robot alignment, and physical fidelity. Compared with ad-hoc combinations of a few data sources, it provides an explicit category-level framework for selecting and integrating heterogeneous supervision.
Decompose and Reorganize: Planning with Primitives and Visuomotor Policies Learned from Demonstrations <See Details on Fugu-MT>
Decomposes human demonstrations into atomic skills and reorganizes them via task-and-motion planning for long-horizon manipulation. Rather than requiring end-to-end policies over entire task sequences, it adds a structured reuse mechanism that generalizes to unseen setups and physical constraints.
ACE-Data-0: Human-Centric Ambient Capture as Embodied Data Engine <See Details on Fugu-MT>
Introduces an ambient capture engine that records synchronized multisensory human manipulation data in real home environments. Beyond narrowly collected robot demos or video-only sources, it captures egocentric and exocentric video, full-body and hand motion, object geometry, and 6-DoF trajectories.
KAI: A Kinematic-Aware Interface for Data-Efficient Articulated Object Manipulation <See Details on Fugu-MT>
Proposes a kinematic-aware interface that encodes articulation structure as an intermediate representation for policy learning on articulated objects. Compared with methods that rely mainly on robot demonstrations, it achieves data-efficient generalization by injecting geometric and kinematic priors directly.
Outlook
Outlook Summary
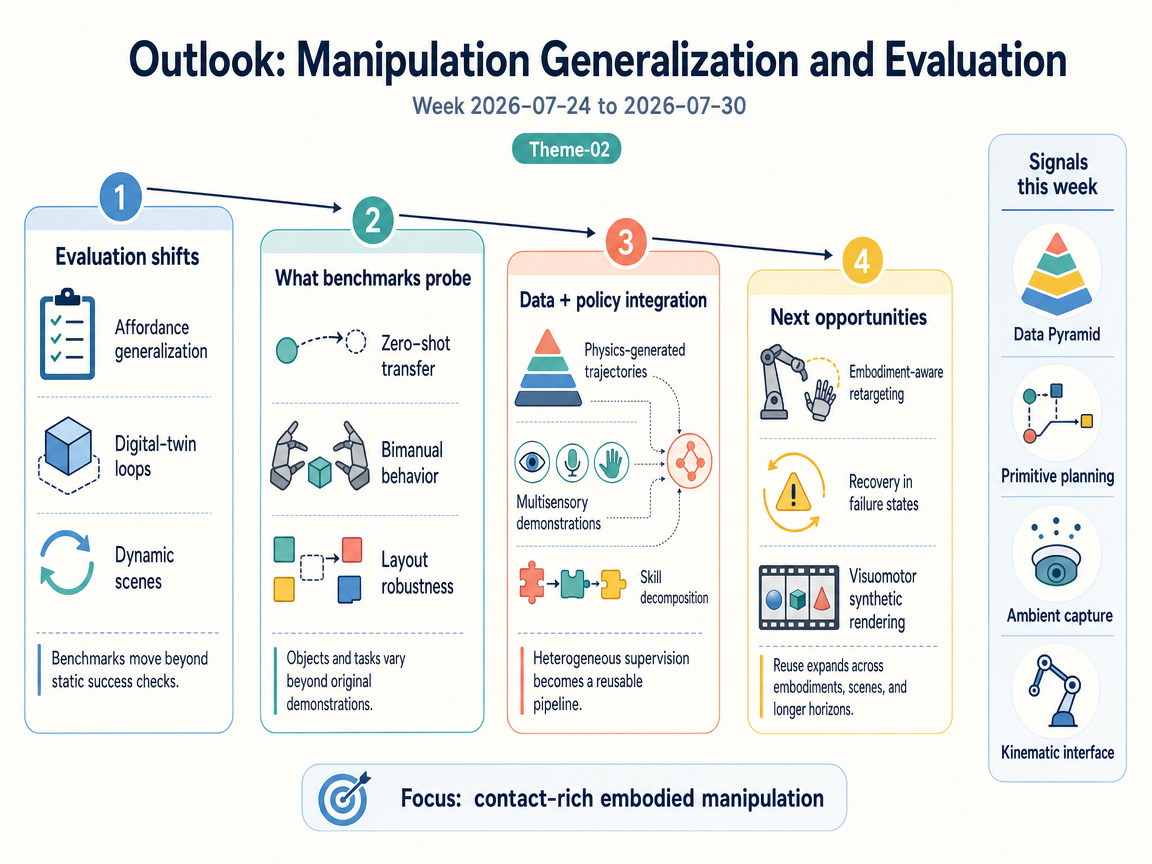
Manipulation research is likely to move from static success checks toward systematic tests of transfer under rearranged, dynamic, and unfamiliar conditions. Benchmarks will increasingly examine zero-shot transfer, two-handed behavior, and recovery beyond original demonstrations. Training will combine physics-generated trajectories, multisensory human demonstrations, and reusable skill decomposition. Progress will also depend on embodiment-aware retargeting, synthetic visual data, denser tactile sensing, and planning methods that recover from previously unseen failures.
Infographic (English)
Three-Year Movement
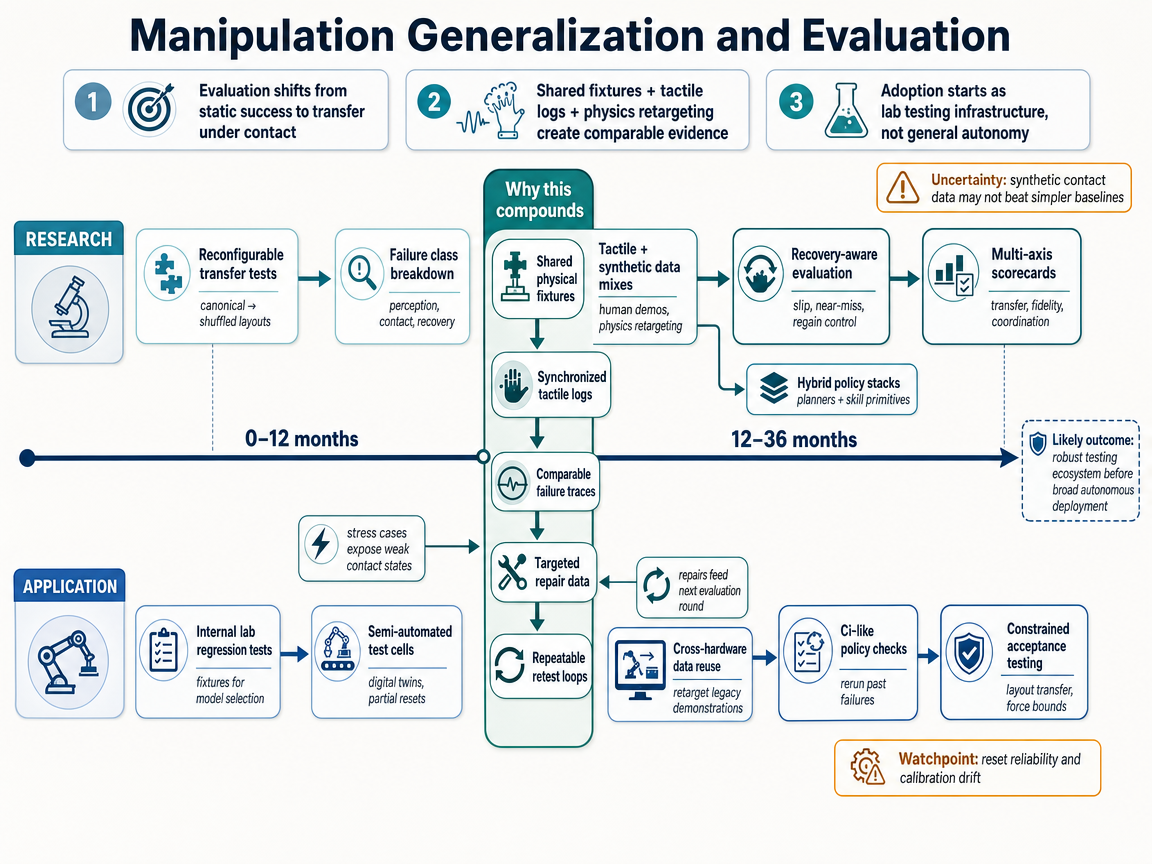
The expected path begins with a shift from familiar tabletop demonstrations to comparable tests under changed layouts and contact conditions. Its mechanism combines reconfigurable fixtures, sensor-rich demonstrations, and physics-generated trajectories so that researchers can measure which data mixtures transfer. During the first year, groups will reproduce shuffled-layout tests and compare performance on familiar and rearranged configurations. Some will build digital twins, meaning simulated copies of physical fixtures, and connect them to semi-automated reset systems. A key monitoring cue will be whether transfer and contact results become routine evaluation tables rather than optional demonstrations.
In the second year, evaluation should expand to mild scene changes, contact stability, and recovery after near-miss failures. Denser tactile sensing and motion tracking may expose slipping or fingertip occlusion before these problems cause complete failure. Embodiment-aware retargeting should also become more common, allowing demonstrations to be adapted to robots with different joints or body structures. Mature benchmark modules could then support repeated internal tests, while older demonstrations are reused across newer hands and arms.
By the third year, this stack could become stable research infrastructure rather than a collection of isolated projects. Policies will increasingly work with planners, reusable skill primitives, and descriptions of articulated objects, helping robots recombine learned actions under new physical constraints. Evaluation scorecards should cover affordance transfer, contact fidelity, and recovery instead of reducing performance to one success rate. Prototype teams in constrained settings could use digital twins and physical fixtures to check every policy update against layout changes and known failures. The feedback loop is that comparable results reveal effective training mixtures, which encourages shared fixtures and produces still more comparable evidence. This path should be downgraded if results remain limited to familiar layouts, independent reproductions do not appear, or mixed tactile and synthetic data fail to improve strong baselines. Even with better testing, force-control failures and missing physical capabilities may remain unrecoverable, so this infrastructure would not imply unsupervised general-purpose operation.
This scenario treats manipulation evaluation like software fuzzing, where inputs are varied deliberately to expose failures. In robotics, those inputs are layouts and contact conditions, while digital twins and automated resets form the test harness. Tactile sensing helps diagnose pressure or slipping that cameras may miss, and physics-based generation creates repair examples from a small demonstration set. During the first year, teams will focus on reliable fixtures, synchronized logs, and reset procedures. They will then search for difficult physical configurations and feed the resulting failures into planning or trajectory-generation systems. The strongest early monitoring cue will be evidence that failure-directed data improves recovery on unseen configurations more efficiently than random variation.
In the second year, the central loop should become operational: break the policy, diagnose the failure, generate a repair, and retest it. Dense contact measurements may identify loss of grip or excessive force before a visible crash occurs. A simulator or planner can then search for a safe escape path and add it to the next training batch. Advanced teams may apply this process to bounded tasks such as wiping, articulated controls, or selected two-handed operations. Human supervision will still be needed when hardware is damaged or the simulated contact model is inaccurate.
By the third year, researchers will test whether the same failure cases transfer across benchmarks and robot bodies. Shared task descriptions and failure records could let teams reproduce a stress case on different hands or two-arm systems. Practical test cells may resemble continuous software testing, with every policy revision checked automatically against a library of earlier failures. Managed arrays of cells could run overnight if reset reliability and mechanical upkeep become manageable. Confirmation would include open reset systems operating unattended and repair data that transfers across layouts or embodiments. The scenario weakens if ordinary randomization performs equally well, tactile wear makes triggers unreliable, or cells remain limited to easily reset tasks. Physical tests also consume time and can damage equipment, so the approach will persist only when repaired failures justify the cost of maintaining the cells.
This scenario develops manipulation benchmarks into recurring proficiency tests across laboratories. An undisclosed physical configuration acts as a blind test, while standard resets and synchronized logs make results more comparable. The mechanism links hidden tests to targeted remediation: each failure is classified, repaired with suitable data or planning, and tested again on a held-out configuration. During the first year, groups will measure differences between familiar and shuffled layouts and separate policy errors from fixture or calibration noise. Digital twins, reference policies, and calibration objects should support that diagnosis. The decisive monitoring cue will be several sites obtaining stable rankings or recognizable failure profiles with limited technician effort.
If that threshold is reached, the second year should bring small inter-laboratory testing rounds. Rotated layouts and shared calibration materials will help determine whether a poor result comes from the policy, robot, or reset process. A growing failure corpus can then show whether tactile demonstrations, synthetic trajectories, or explicit recovery planning best address each failure type. Recurring tests would generate structured traces, those traces would guide repairs, and repaired systems would face harder hidden configurations. Shared facilities may begin using this evidence in regular project reviews or equipment trials.
By the third year, tests should expand to two-handed coordination, changing physical conditions, and recovery from induced failures. Long-term records could reveal policy regressions, calibration drift, or hardware wear that one-time demonstrations would miss. Facilities may issue bounded qualification reports describing robustness and past regression results, while equipment providers improve telemetry and reset interfaces. Progress would be supported by automated resets and shared failure definitions, provided raw contact and recovery records remain available. The path should be downgraded if cross-site results stay unstable, resets remain expert-intensive, or repaired systems still fail on hidden configurations. Passing a compact test also cannot establish broad competence or safety, because robot tasks are open-ended and adaptive systems may memorize leaked configurations.
1-Year / 3-Year Research-Application Infographic
References
- Physics-Driven Data Generation for Contact-Rich Manipulation via Trajectory Optimization - Authors: Lujie Yang, H. J. Terry Suh, Tong Zhao, Bernhard Paus Graesdal, Tarik Kelestemur, Jiuguang Wang, Tao Pang, Russ Tedrake, / <See Details on Fugu-MT> / License: CC-BY-4.0
- OSMO: Open-Source Tactile Glove for Human-to-Robot Skill Transfer - Authors: Jessica Yin, Haozhi Qi, Youngsun Wi, Sayantan Kundu, Mike Lambeta, William Yang, Changhao Wang, Tingfan Wu, Jitendra Malik, Tess Hellebrekers, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Benchmarking Affordance Generalization with BusyBox - Authors: Dean Fortier, Timothy Adamson, Tess Hellebrekers, Teresa LaScala, Kofi Ennin, Michael Murray, Andrey Kolobov, Galen Mullins, / <See Details on Fugu-MT> / License: CC-BY-4.0