Summary
This theme centers on how foundation models are being evaluated and improved for scientific and multimodal use, with emphasis on pretraining strategy, data realism, and efficient cross-modal design. Representative papers argue that strong performance depends less on generic scaling alone and more on domain-aware continued pretraining, better benchmark construction, and architectures matched to real workflow constraints.
Situation
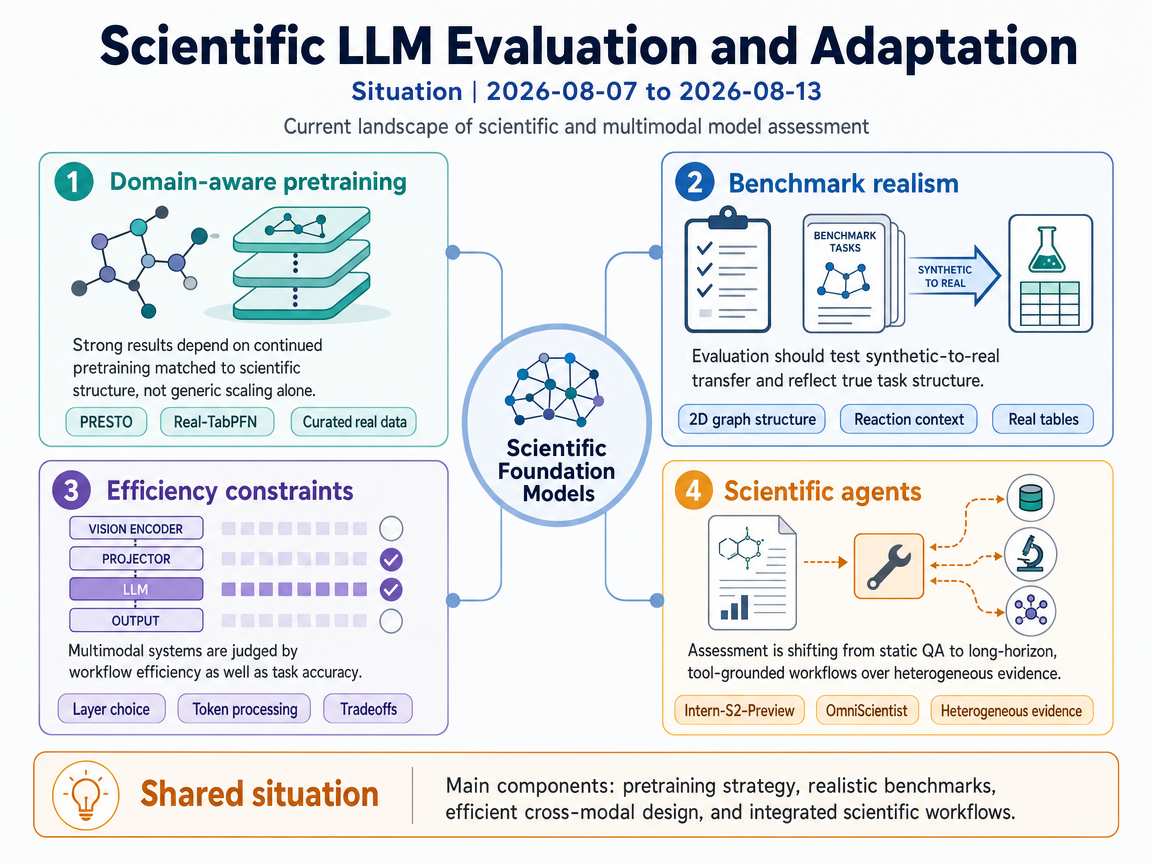
The representative papers frame model evaluation as a question of whether foundation models are actually prepared for specialized scientific and multimodal settings. PRESTO shows that in synthetic chemistry, prior molecule-text systems often miss crucial 2D graph structure, multi-graph reaction context, and careful pretraining design, motivating cleaner benchmarks and progressive domain pretraining. Real-TabPFN similarly argues that even a model trained on massive synthetic tabular data can still benefit from continued pretraining on curated real-world tables, highlighting the importance of testing synthetic-to-real transfer rather than assuming broad priors are sufficient.
A second shared direction is evaluating models under practical efficiency and workflow requirements, not only headline task accuracy. Platonic Grounding for Efficient Multimodal Language Models asks which layers are truly necessary for multimodal token processing and presents efficiency-performance tradeoffs for vision-language models. As current-week evidence, Intern-S2-Preview: Scientific Agentic Foundation Model pushes the evaluation target beyond static scientific question answering toward long-horizon, tool-grounded problem solving over heterogeneous evidence, reinforcing a shift toward assessing whether LLMs can operate as scientific agents rather than only answer isolated prompts.
Infographic (English)
Progress
Intern-S2-Preview: Scientific Agentic Foundation Model <See Details on Fugu-MT>
Introduces a multimodal scientific foundation model trained on rendered scientific documents and interleaved image-text data, targeting understanding, reasoning, generation, and long-horizon agentic tasks. Shifts evaluation from static scientific QA toward sustained, tool-grounded scientific workflows with explicit support for multi-task reinforcement learning and on-policy distillation.
OmniScientist: An Omni-Modal Omni-Discipline AI Scientist <See Details on Fugu-MT>
Presents an end-to-end omni-modal AI scientist with coordinated agents for ideation, experimentation, and writing, evaluated on 36 real cases across five disciplines and nine evidence types. Broadens the evaluation scope from single-modality or single-benchmark testing to integrated scientific workflows over heterogeneous raw evidence.
Outlook
Outlook Summary
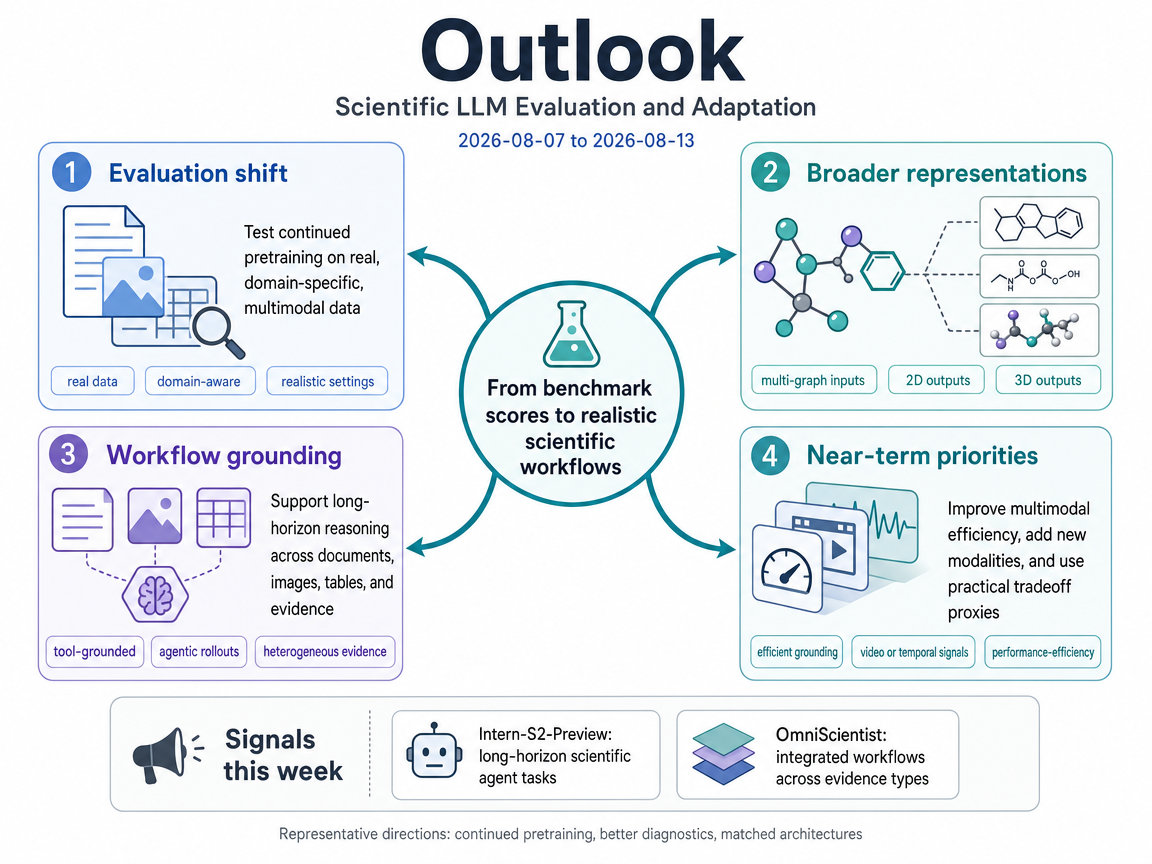
Evaluation is moving beyond static benchmark scores toward realistic tests of continued pretraining on curated domain data and multimodal evidence. Near-term work will broaden dataset coverage, improve scientific representations, and detect leakage or distribution shift. Models will also need efficient, tool-grounded reasoning across documents, images, and tables during long workflows, with practical ways to balance performance against resource use.
Infographic (English)
Three-Year Movement
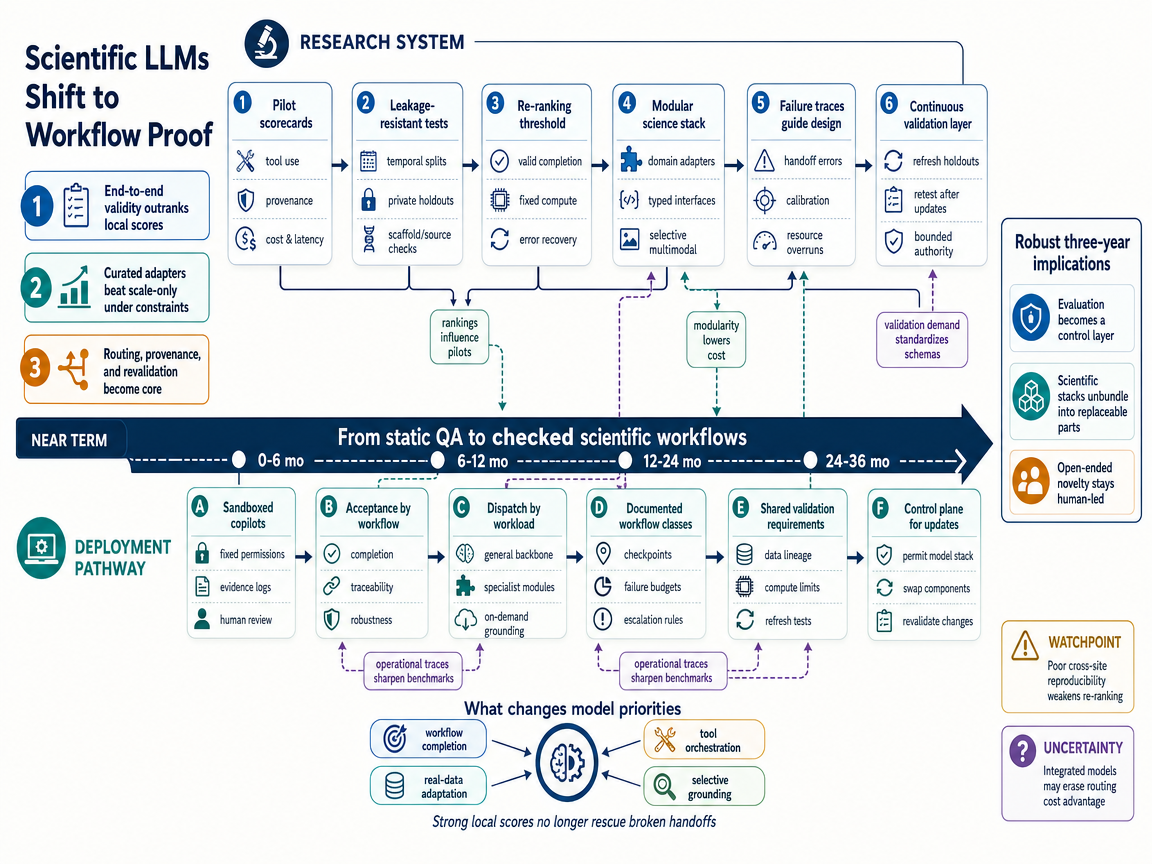
The outlook shifts attention from generic scale and static questions toward reliable completion of realistic scientific workflows. Models must use domain data, scientific structure, and multimodal evidence while working through many connected steps. The mechanism resembles an on-time, complete delivery score: success requires a correct result, valid evidence, and acceptable resource use, rather than a high score on one isolated task.
During the first year, teams will create scorecards for bounded workflows such as reaction planning, tabular prediction, and evidence synthesis. These tests will track completion, traceability, and recovery from failed tool calls. Hidden evaluations separated by source or time will help reveal leakage and distribution shift. Teams will also compare curated real-data adaptation with synthetic-only training and test whether efficient multimodal processing remains effective during sustained work. The key threshold will be a repeatable ranking change in which an adapted or efficient system completes more valid workflows than a larger generic model under the same constraints.
In the second year, credible results should redirect engineering toward domain adapters, explicit scientific representations, and dependable tool orchestration. Shared evaluation practices may standardize provenance records, controlled tool environments, and resource accounting. Failure traces can then show whether a breakdown came from weak evidence, a tool handoff, or an unfamiliar data distribution. By the third year, evaluation could become a continuous control layer that reruns tests whenever a model, dataset, or external tool changes. Systems that pass refreshed validation may gain wider authority within clearly bounded tasks, while specialists retain control over uncertain cases.
A strong monitoring cue would be leaderboards with complete provenance and consistent gains on private or time-separated tests. The path would be weakened by poor replication across sites, rapid contamination of hidden tests, or static-score leaders continuing to dominate controlled workflows. The delivery analogy also has a limit: it can test dependable completion of checkable tasks, but it cannot determine the novelty or long-term truth of an open scientific idea.
The outlook favors targeted adaptation, realistic data, and efficient multimodal grounding over generic scale-first development. Long scientific workflows make hidden costs and accumulated errors visible because models must coordinate evidence and external tools across many steps. The scenario uses an electricity-grid mechanism: a general reasoning backbone handles common work, while an orchestrator activates specialized modules only when needed.
In the first year, researchers will build workflow-level “meters” for accuracy, resource use, and provenance. Leakage-resistant tests will separate general reasoning from specialized work such as molecular analysis, structured prediction, or image interpretation. Early modular systems will route each step either to the backbone or to a suitable specialist. Their decisive threshold is grid parity, meaning that a routed pipeline completes the same workflow at lower total cost without losing reliability or traceability. Supervised pilots will remain bounded, and most modules will exchange typed inputs and structured outputs rather than sharing one internal representation.
If these systems reach parity, the second year will focus on interoperability and operational reliability. Common formats for tool outputs, confidence estimates, and provenance records will make modules easier to replace. Routing methods will select the least costly component that still meets defined quality and latency limits. By the third year, this can produce a reinforcing loop: better evaluation increases demand for dispatchable specialists, which supports better curated datasets and stronger modules. Managed control systems could then coordinate literature review, experiment preparation, and report generation while retaining human approval at consequential steps. Smaller modular systems may also operate on constrained hardware when local processing is required.
Repeated parity results and independent certification pilots would be important monitoring cues. The scenario would weaken if integrated multimodal models consistently match routed systems on accuracy, cost, and auditability. It would also be undermined if routing overhead makes workflows fragile or if gains from curated real data fail to generalize. The grid analogy remains limited because model representations are not interchangeable like electrical power, so competing interfaces and custom adapters may persist.
The outlook suggests that scientific trust may shift from evaluating a model alone to evaluating the full workflow around it. The scenario borrows from laboratory accreditation: models act as instruments, blind benchmarks act as proficiency tests, and execution logs provide a chain of custody. This mechanism makes traceable evidence and controlled operation as important as the final answer.
During the first year, researchers will strengthen scaffold-aware splits, contamination checks, and uncertainty calibration. Scientific teams will add provenance wrappers that record data versions, intermediate outputs, and human overrides. Chemistry and tabular systems can serve as early test beds, while efficient multimodal designs clarify when visual or structural evidence must be processed. A major reproducibility failure caused by leakage could accelerate adoption. A stronger positive signal would be several institutions publishing blind proficiency tests and a machine-readable format for workflow records.
The scenario needs a threshold event in the second year. A respected journal, research sponsor, or scientific institution must make provenance or proficiency results a real decision gate rather than optional supporting material. If that happens, evaluators will examine whether evidence supports conclusions, uncertainty is calibrated, and results survive component replacement. This creates a feedback loop because verified components become easier to replace, increasing demand for specialized tools that can pass defined tests.
By the third year, shared proficiency suites could cover several scientific fields and be refreshed regularly to reduce memorization. Governance systems could automatically revalidate workflows whenever a model, dataset, or tool changes. Some high-consequence research programs may then require a validated workflow before accepting AI-assisted results. Models would function as replaceable instruments within a larger control system, with each component approved for specific operating conditions.
The main monitoring cue is whether workflow records begin to affect publication and deployment decisions. The path would weaken if provenance remains an optional dashboard or if institutions adopt incompatible formats. It would also lose force if one general system reliably handles varied scientific evidence and long reasoning at low cost. Accreditation cannot guarantee exact correctness because these models are stochastic, but it could establish calibrated uncertainty, traceable evidence, and known failure limits.
1-Year / 3-Year Research-Application Infographic
References
- PRESTO: Progressive Pretraining Enhances Synthetic Chemistry Outcomes - Authors: He Cao, Yanjun Shao, Zhiyuan Liu, Zijing Liu, Xiangru Tang, Yuan Yao, Yu Li, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Platonic Grounding for Efficient Multimodal Language Models - Authors: Moulik Choraria, Xinbo Wu, Akhil Bhimaraju, Nitesh Sekhar, Yue Wu, Xu Zhang, Prateek Singhal, Lav R. Varshney, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Real-TabPFN: Improving Tabular Foundation Models via Continued Pre-training With Real-World Data - Authors: Anurag Garg, Muhammad Ali, Noah Hollmann, Lennart Purucker, Samuel Müller, Frank Hutter, / <See Details on Fugu-MT> / License: CC-BY-SA-4.0
- Distilling Physical Priors into Streaming World Models - Authors: Liangliang Zhao, Junying Wang, Danni Yang, Yifan Chang, Bin Fu, Yu Qiao, Bowen Zhou, Yihao Liu / <See Details on Fugu-MT> / License: CC BY 4.0
- Intern-S2-Preview: Scientific Agentic Foundation Model - Authors: Lei Bai, Jiaqi Cao, Chiyu Chen, Guanzhou Chen, Kai Chen, Guangran Cheng, Erfei Cui, Xuanlang Dai, Shengyuan Ding, Shangheng Du, Yanhui Duan, Yue Fan, Youqing Fang, Quan Gan, Yuanyuan Gao, Jiaye Ge, Lixin Gu, Yuzhe Gu, Qipeng Guo, Junjun He, Xin Hong, Ming Hu, Zhouqi Hua, Haian Huang, Junhao Huang, Zixian Huang, Minxi Jin, Lingkai Kong, Alexander Lam, Zehao Li, Zonglin Li, Tianhao Liang, Dahua Lin, Junyao Lin, Tianyang Lin, Zhouhan Lin, Jiangning Liu, Jin Liu, Kuikun Liu, Wenran Liu, Yifei Liu, Yuhong Liu, Yuhong Liu, Zhoumianze Liu, Ziyan Liu, Ziyu Liu, Haijun Lv, Han Lv, Chengqi Lyu, Le Ma, Ningsheng Ma, Zerun Ma, Haoyang Peng, Runyu Peng, Jifei Shan, Zixin Shang, Kou Shi, Xiang Shi, Qisheng Su, Xuerui Su, Hao Sun, Xiao Sun, Yanan Sun, Yu Sun, Huanze Tang, Yinghao Tang, Wenhui Tian, Zhongbo Tian, Bingli Wang, Haomin Wang, Jiarui Wang, Jingzhi Wang, Rui Wang, Xiquan Wang, Yi Wang, Zhecan Wang, Ziyi Wang, Zun Wang, Rubin Wei, Lianyi Wu, Wen Wu, Yue Wu, Yuhan Wu, Zhenyu Wu, Zijian Wu, Shuhao Xing, Jun Xu, Xingle Xu, Xuenan Xu, Xiangchao Yan, Ziang Yan, Bowen Yang, Danni Yang, Lin Yang, Zhiqi Yang, Qian Yao, Haochen Ye, Peng Ye, Jinhui Yin, Jiashuo Yu, Dingbo Yuan, Fei Yuan, Yuhang Zang, Bo Zhang, Chao Zhang, Chen Zhang, Hongjie Zhang, Junming Zhang, Wenlong Zhang, Wenwei Zhang, Yiming Zhang, Zhuo Zhang, Ziyang Zhang, Haiteng Zhao, Penghao Zhao, Yibo Zhao, Zhonghan Zhao, Zhihang Zhong, Bowen Zhou, Peiheng Zhou, Xin Zhou, Xinyu Zhou, Yunhua Zhou, Dongsheng Zhu, Yicheng Zou / <See Details on Fugu-MT> / License: CC BY 4.0