Summary
This week's theme centers on moving model evaluation beyond narrow offline metrics toward executable, task-grounded benchmarks for embodied world models and multimodal GUI agents. Representative papers argue that current evaluations miss functional utility, efficiency, and cross-application behavior, consistently revealing gaps between perceptual quality and reliable task performance.
Situation
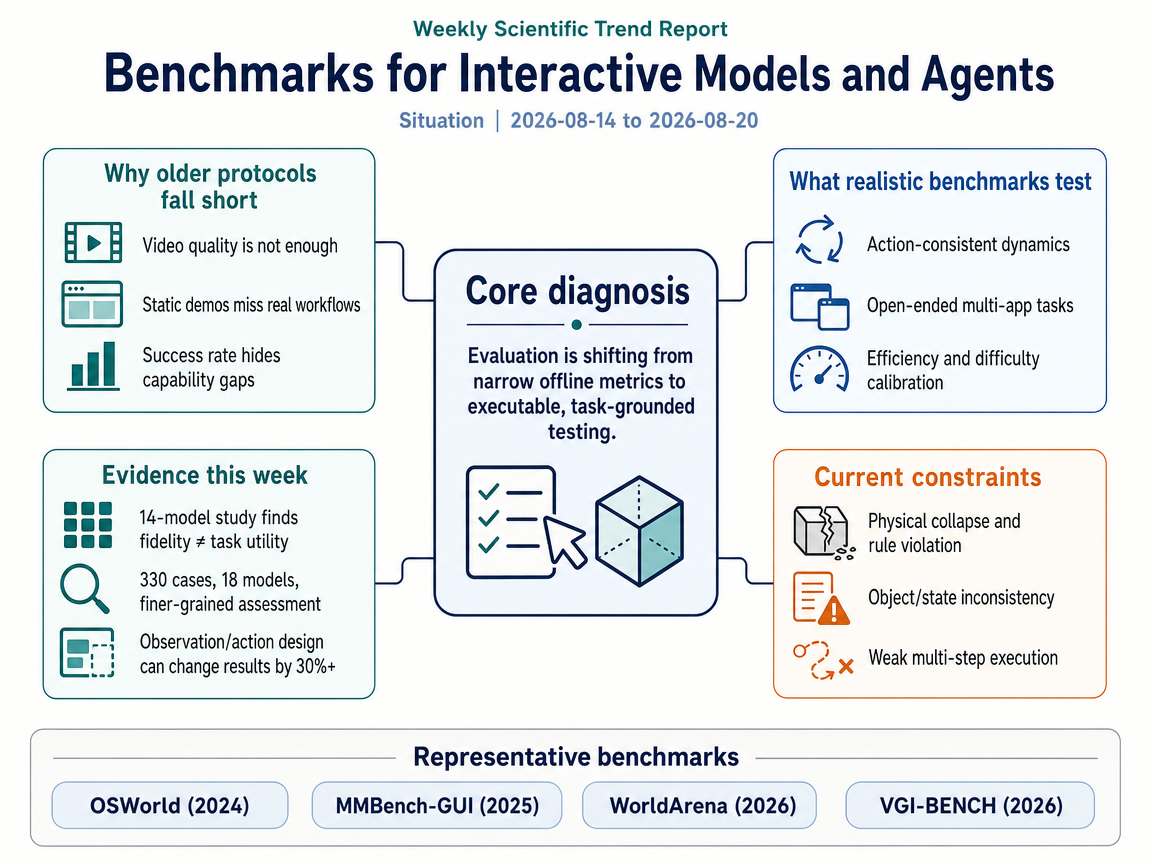
The representative benchmark papers converge on a common diagnosis: prevailing evaluation protocols are too narrow for the systems now being built. WorldArena argues that embodied world models cannot be judged by video quality alone, because practical use depends on action-consistent dynamics, policy evaluation, planning support, and synthetic-data utility; its evaluation of 14 models explicitly highlights a gap between visual fidelity and embodied task performance. In parallel, OSWorld motivates execution-based testing in real computer environments, noting that static demonstration datasets and restricted domains fail to capture open-ended multi-application workflows, while MMBench-GUI extends this critique by stressing hierarchical capability coverage, multi-platform realism, and efficiency in addition to raw success rate.
The current-week evidence reinforces this shift toward capability-specific, validity-aware evaluation. VGI-BENCH (2608.19583v1) argues that benchmarks should test process-sensitive visual rollout reasoning rather than only final outputs or abstract-input tasks, and reports that even strong models show substantial failures such as physical collapse, rule violation, and object/state inconsistency. Across the theme, the field is redefining evaluation around realistic environments, executable tasks, calibrated difficulty, and metrics that better reflect whether models can support downstream action and reasoning.
Infographic (English)
Progress
HarnessEval-W: Agentifying the Evaluation of Visual Worlds <See Details on Fugu-MT>
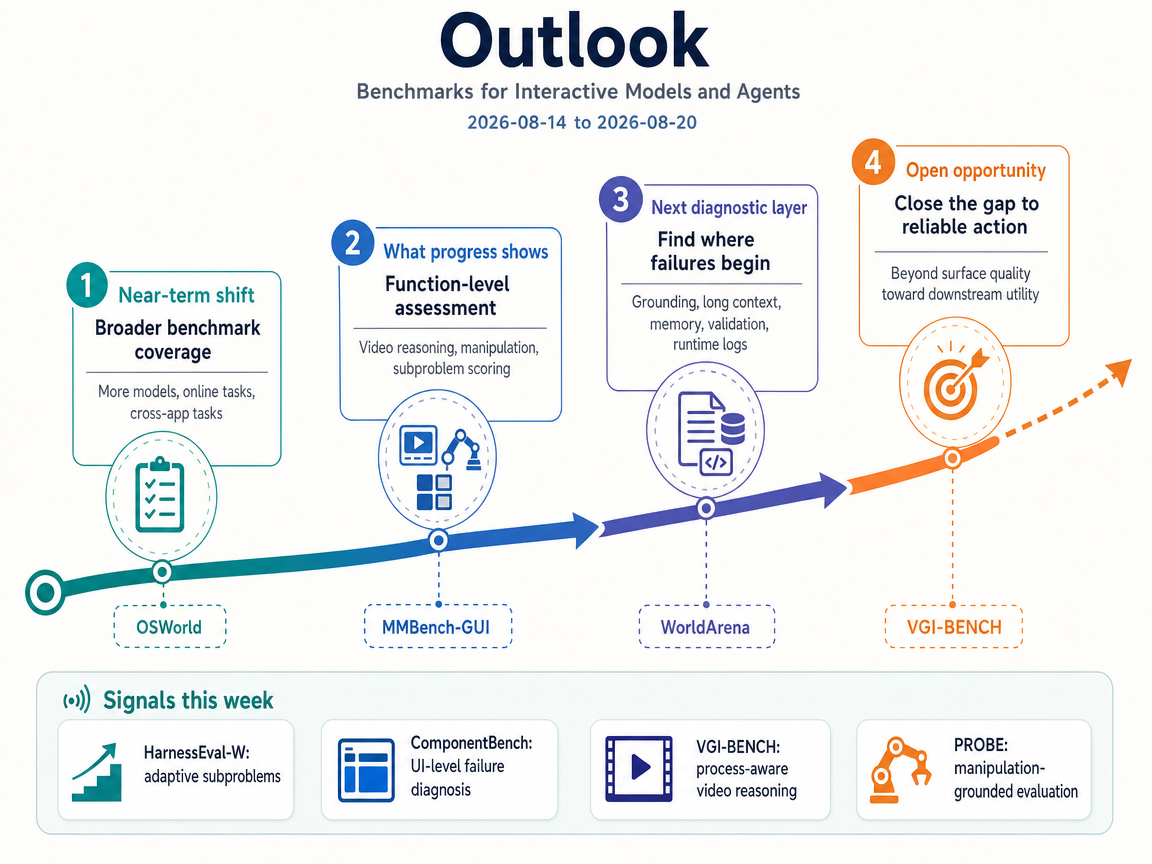
HarnessEval-W introduces an agentic evaluation pipeline for world models that decomposes benchmark questions into measurable subproblems. Instead of applying fixed rubrics, it enables adaptive, fine-grained assessment across 330 cases and 18 models.
ComponentBench: Diagnosing Component-Level Failures in Computer-Use Agents <See Details on Fugu-MT>
ComponentBench diagnoses computer-use agent failures at the level of individual UI components on modern web interfaces. It shows that changing only observation and action spaces can shift task success by over 30% for the same model, exposing evaluation sensitivity missed by aggregate metrics.
VGI-BENCH: Probing Visual Intelligence in Video Generation Models <See Details on Fugu-MT>
VGI-BENCH probes visual intelligence in video generation models through process-sensitive reasoning tasks with photorealistic inputs. It reveals that current models can partially solve grounded reasoning tasks but remain unreliable, with common failures in physical consistency and multi-step execution.
PROBE: Manipulation-Grounded Visual Question Answering with VLM Agents <See Details on Fugu-MT>
PROBE extends VLM agent evaluation to manipulation-grounded visual question answering requiring physical interaction. Compared with static or 2D-only evaluations, it provides a framework for benchmarking and fine-tuning on tasks tied to embodied manipulation.
Outlook
Outlook Summary
Evaluation is moving toward broader, more realistic tasks that measure whether AI systems are useful in practice, not merely whether their outputs look convincing. New benchmarks increasingly test executable processes, interaction with interfaces, and success on meaningful subproblems. They are also becoming more diagnostic. Step-level checks and richer runtime records can separate failures in grounding from failures in reasoning or action, helping researchers improve systems rather than relying only on larger leaderboards.
Infographic (English)
Three-Year Movement
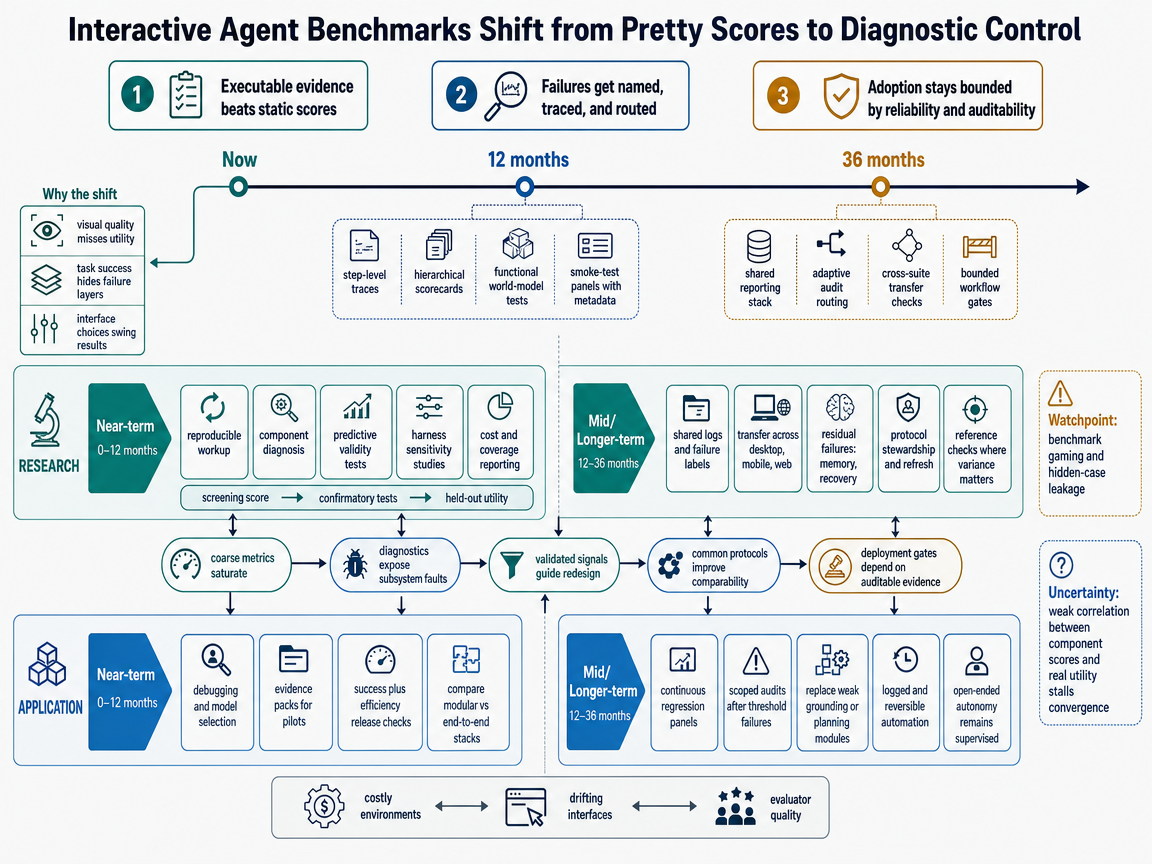
The main movement is from static scores toward executable evaluation that can identify why an interactive system fails. The mechanism resembles a clinical workup: an overall success score acts as an initial screen, while targeted tests confirm whether the problem lies in grounding, planning, or execution. In the first year, researchers add step-level traces, component scorecards, and controlled interface comparisons. Functional tests also examine whether generated environments actually support useful planning or training rather than simply looking realistic.
By the second year, these diagnostics begin to matter only if they predict performance on held-out tasks. Shared logging formats and failure labels then spread across computer-use and embodied test environments. Teams can test whether an improvement transfers between settings or merely exploits one local protocol. Reusable environments and diagnostic dashboards also become part of routine development, making it easier to justify replacing a weak component instead of discarding an entire system.
By the third year, better diagnosis exposes more difficult weaknesses involving long-term state, recovery, and unintended effects. Around Month 36, a loosely unified reporting system is likely to cover the main stages from perception through action, while also recording robustness and efficiency. It need not depend on one dominant benchmark; its value comes from making evidence comparable across system designs and bounded automation trials. A useful monitoring cue is whether independent teams increasingly reuse execution environments, publish hierarchical scores, and document design changes prompted by diagnostic results. Hard open-ended tasks will probably remain below human reliability, so practical deployment stays supervised and reversible. This movement would weaken if component scores failed to predict held-out usefulness, or if maintenance costs pushed researchers back toward static demonstrations.
The contender path also moves toward realistic and diagnostic evaluation, but its main mechanism is resource scarcity. Full executable tests require maintained environments, detailed logs, and substantial review, so they may be too costly to run for every model update. In the first year, teams respond by building small sentinel panels, meaning compact test sets chosen to reveal important regressions. These panels separate broad capabilities into focused checks and record protocol details such as environment versions and action interfaces.
The key first-year threshold is predictive validity. A small panel must reliably forecast failure in a larger evaluation or realistic workflow. If it does, an automated evaluator can use the failed case to select deeper tests rather than rerunning every expensive task. By the second year, maintained evaluation systems begin routing failures automatically to the relevant checks. Shared operators may also provide reusable virtual machines, device pools, or browser sandboxes, making continuous testing more practical across organizations.
By the third year, incidents and near misses from bounded automation pilots refresh the sentinel panels. This creates a feedback loop in which failures produce better records, those records reveal weak components, and the resulting tests guide system changes. Around Month 36, stewardship groups could maintain rotating public cases, hidden holdouts, and clear escalation procedures. Broad leaderboards would continue, but high-value evidence would increasingly come from maintained test infrastructure that explains where a system failed and when its coverage was last updated. A monitoring cue is growing use of coverage labels, evaluation-cost reports, and threshold-triggered audits. The main caveat is that developers can tune systems directly to visible sentinel cases, so rotation and independent maintenance remain necessary. The path would weaken if reduced panels failed to predict broad performance, or if full executable evaluations became cheap and stable enough to remove the resource constraint.
The conditional path treats benchmark reliability as a measurement-validity problem. Results can shift when researchers change observation formats, action interfaces, or environment versions, even if the tested system stays the same. In the first year, several groups conduct ring trials, meaning they run frozen systems through different versions of the same evaluation setup. They measure score variation and ranking reversals while adding replay tools and version controls. A prominent reversal among leading systems could cross the threshold that makes raw scores difficult to defend without calibration.
By the second year, major benchmarks may publish certified configurations with reference systems, expected score ranges, and required runtime records. Reference systems act like calibration instruments because their normal behavior helps reveal whether the test setup has drifted. Evaluation also becomes more component-focused, allowing researchers to identify a weak subsystem and test it again after replacement. Generated environments would likewise need functional evidence before they are accepted as useful for planning or data generation. The mechanism is a reinforcing loop: demand for credible scores supports calibration infrastructure, while cheaper replication encourages wider adoption of controlled protocols.
By the third year, this regime faces pressure from changing software and systems that learn to exploit fixed tests. Around Month 36, credible certification would therefore require rotating references, hidden challenge sets, and active drift monitoring. If maintenance is timely and transparent, reproducible evaluation could become part of continuous validation across major interactive settings. Exploratory leaderboards would remain, but consequential capability claims would rely more on replicated functional and efficiency evidence. A monitoring cue is the appearance of independent ring-trial studies, locked protocol versions, and routine uncertainty reporting. The main caveat is that frozen references can become stale or be targeted directly. This path would weaken if setup-related variance proved small, normalized scores failed to predict practical usefulness, or research venues showed little interest in replicated evidence.
1-Year / 3-Year Research-Application Infographic
References
- OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments - Authors: Tianbao Xie, Danyang Zhang, Jixuan Chen, Xiaochuan Li, Siheng Zhao, Ruisheng Cao, Toh Jing Hua, Zhoujun Cheng, Dongchan Shin, Fangyu Lei, Yitao Liu, Yiheng Xu, Shuyan Zhou, Silvio Savarese, Caiming Xiong, Victor Zhong, Tao Yu, / <See Details on Fugu-MT> / License: CC-BY-4.0
- MMBench-GUI: Hierarchical Multi-Platform Evaluation Framework for GUI Agents - Authors: Xuehui Wang, Zhenyu Wu, JingJing Xie, Zichen Ding, Bowen Yang, Zehao Li, Zhaoyang Liu, Qingyun Li, Xuan Dong, Zhe Chen, Weiyun Wang, Xiangyu Zhao, Jixuan Chen, Haodong Duan, Tianbao Xie, Chenyu Yang, Shiqian Su, Yue Yu, Yuan Huang, Yiqian Liu, Xiao Zhang, Yanting Zhang, Xiangyu Yue, Weijie Su, Xizhou Zhu, Wei Shen, Jifeng Dai, Wenhai Wang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- WorldArena: A Unified Benchmark for Evaluating Perception and Functional Utility of Embodied World Models - Authors: Yu Shang, Zhuohang Li, Yiding Ma, Weikang Su, Xin Jin, Ziyou Wang, Xin Zhang, Yinzhou Tang, Chen Gao, Wei Wu, Xihui Liu, Dhruv Shah, Zhaoxiang Zhang, Zhibo Chen, Jun Zhu, Yonghong Tian, Tat-Seng Chua, Wenwu Zhu, Yong Li, / <See Details on Fugu-MT> / License: CC-BY-4.0
- VGI-BENCH: Probing Visual Intelligence in Video Generation Models - Authors: Xuan He, Cong Wei, Yuhao Cheng, Linrui Ma, Yuxuan Zhang, Zuojun Li, Yuhao Wen, Zeyi Liu, Yuren Hao, Songcheng Cai, Keming Wu, Penghui Du, Kai Zou, Rui Yang, Chenkai Sun, Ke Yang, Ping Nie, Kelsey R Allen, Chenglong Wang, Michel Galley, Jianfeng Gao, ChengXiang Zhai / <See Details on Fugu-MT> / License: CC BY 4.0