Summary
This theme concerns making visual generation and reconstruction explicitly grounded in geometry, camera parameters, and scene structure. Representative papers highlight recurring gaps: human reposing methods overfit to small paired datasets, single-image reconstruction ignores object-ground-camera relations, and diffusion-based editors lack precise viewpoint control despite strong visual realism.
Situation
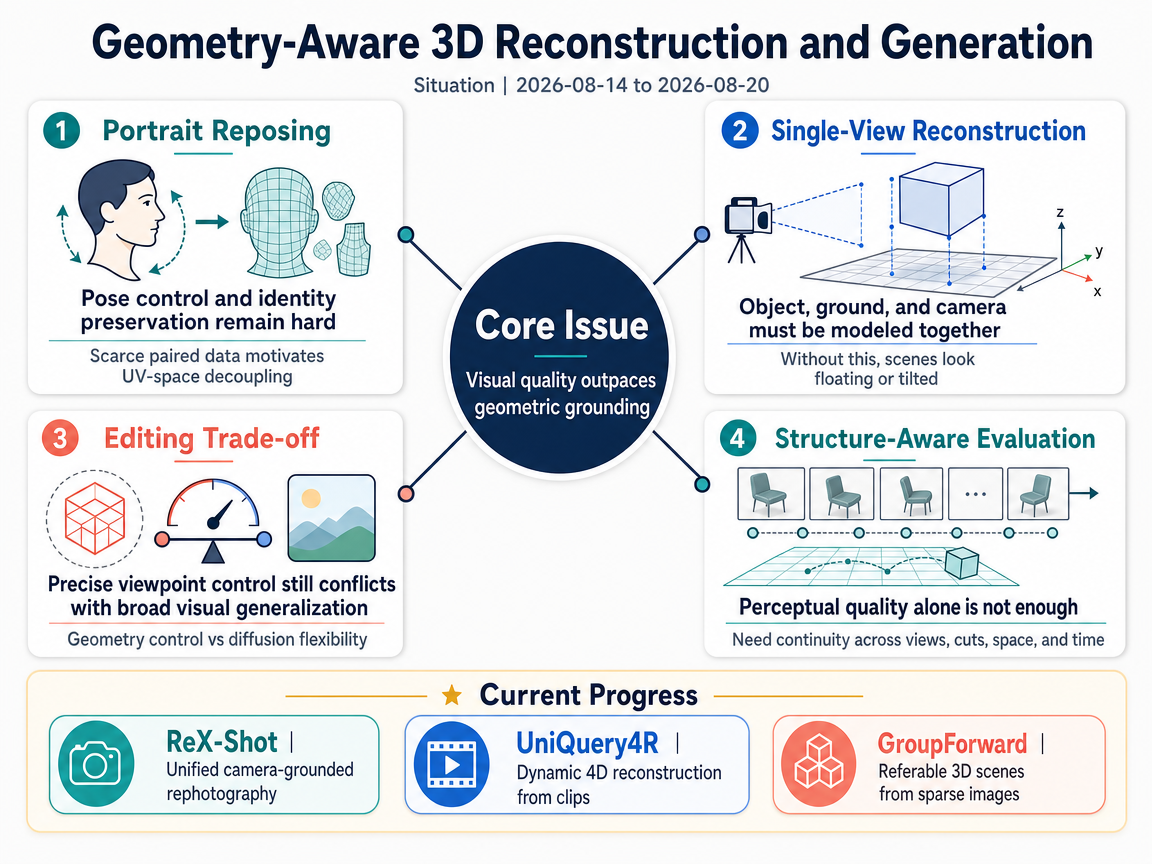
The representative papers frame the central problem as insufficient geometric grounding in visually strong generation pipelines. Pro-Pose shows that single-image portrait synthesis is constrained by scarce paired identity data and by methods that cannot jointly control pose while preserving identity, motivating canonical UV-space training and donor-based UV reposing to decouple pose from texture. Floating No More demonstrates that single-view reconstruction methods often produce objects that appear floating or tilted because they do not explicitly model the object-ground relationship together with camera parameters. Ctrl&Shift highlights a broader trade-off between the precision of geometry-based control and the generalization of diffusion-based editing for object manipulation.
Current-week evidence also points to evaluation becoming more structure-aware. PersonaShot (2608.16717v1) argues that existing benchmarks miss cross-shot physical continuity, fine-grained affective dynamics, and cinematic grammar, showing that perceptual quality alone is insufficient when models must preserve coherent human state across views and cuts. Together, these papers suggest that better geometry-aware representations and controls require equally targeted evaluation of spatial and temporal consistency.
Infographic (English)
Progress
ReX-Shot: Single-Image Rephotography via Geometry- and Camera-Grounded Generation <See Details on Fugu-MT>
ReX-Shot introduces a unified framework for single-image rephotography with joint control of viewpoint, focal length, and parameterized photographic effects. Prior methods treated these camera and photographic factors separately; ReX-Shot unifies them in one geometry-grounded generation pipeline.
UniQuery4R: Unified 4D Scene Reconstruction from a Single Query <See Details on Fugu-MT>
UniQuery4R extends reconstruction from static scenes to dynamic 4D by jointly estimating correspondence, geometry, object motion, and camera motion from multi-frame clips. Compared with earlier work focused on single-frame pose or object-ground relations, it addresses continuous scene dynamics with flexible query-conditioned decoding.
GroupForward: Building Referable 3D Scenes via Instance-Grouped Feed-Forward Gaussian Splatting <See Details on Fugu-MT>
GroupForward reconstructs geometry, appearance, instance structure, and semantics from sparse, unposed, uncalibrated images via instance-grouped Gaussian splatting. Beyond prior work on single portraits or isolated objects, it produces instance-grouped 3D scene graphs that support referential reasoning over the reconstructed scene.
Outlook
Outlook Summary
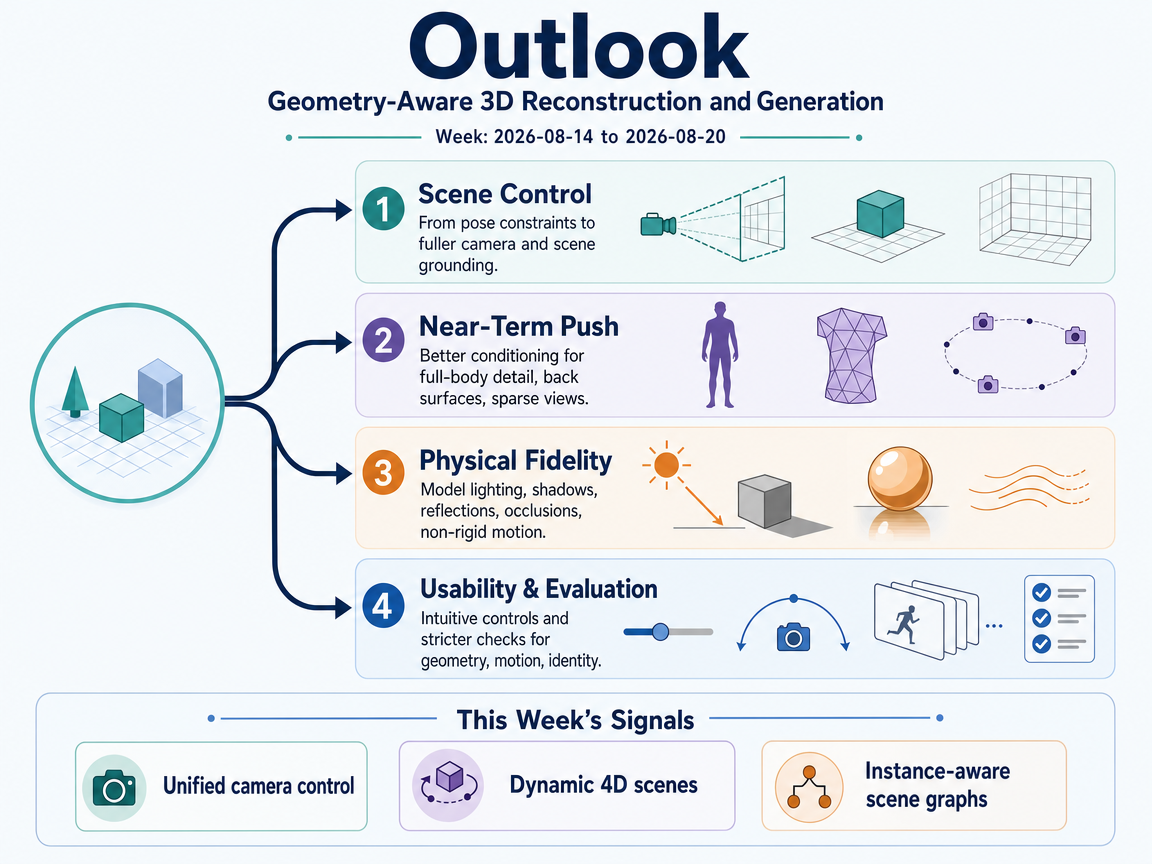
Geometry-aware generation is likely to move from narrow pose and object-ground constraints toward fuller control of scenes, cameras, and dynamic motion. Near-term research will address weak points such as full-body skin detail, complex hidden surfaces, sparse views, and large viewpoint changes. Systems should also model physical effects and non-rigid motion more faithfully while presenting intuitive controls. Evaluation will increasingly test whether geometry, identity, and motion remain coherent across edits, viewpoints, and longer sequences.
Infographic (English)
Three-Year Movement
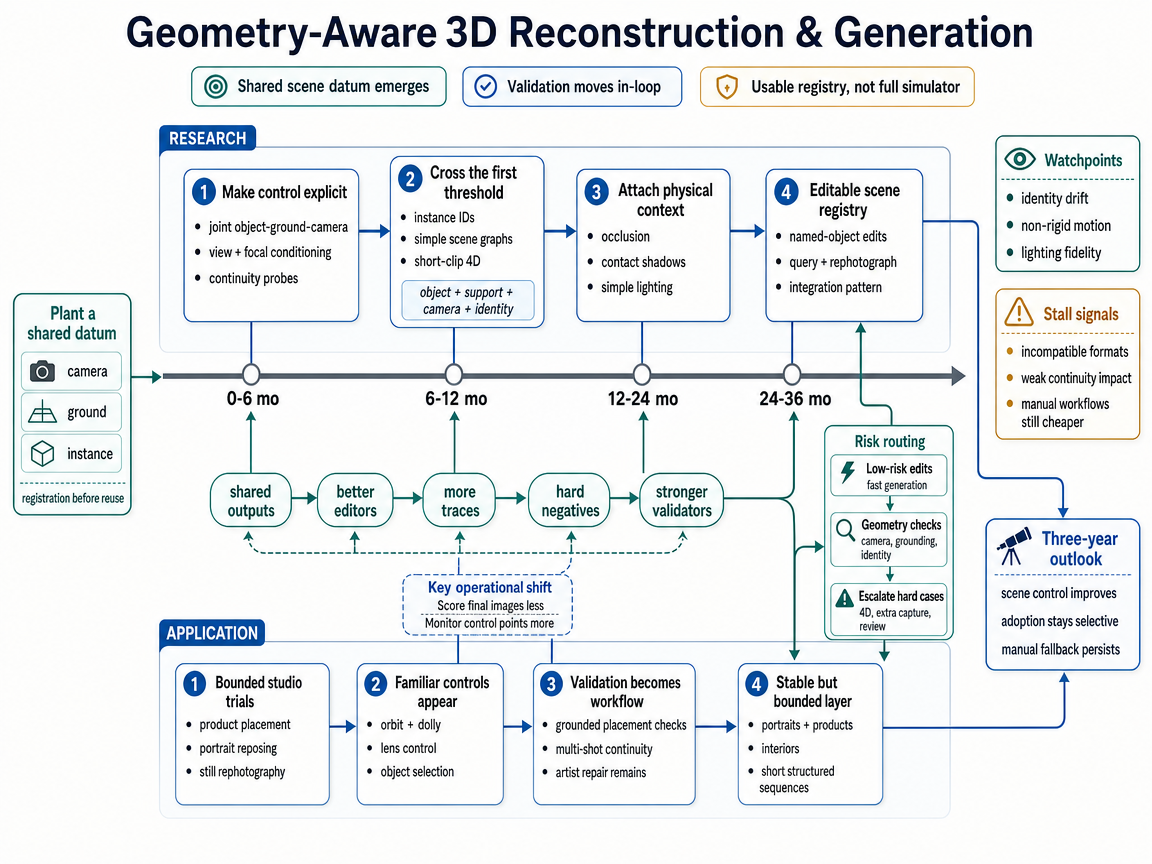
Over the next year, research is likely to combine camera estimation, object grounding, and instance identity within the same generation or reconstruction pipeline. The mechanism resembles a shared mapping datum: camera, support surface, geometry, and motion provide a common reference to which later observations can be registered. A key first-year threshold is whether leading systems routinely return an object together with its camera parameters, support relation, and persistent identity instead of treating each image independently.
If that threshold is crossed, the second year should make camera-conditioned generation and short-duration 4D reconstruction more common as research baselines. Here, 4D means estimating three-dimensional shape as it changes over time. Outputs should increasingly include named scene instances and simple relationships, allowing software to distinguish an object from its surroundings and preserve that distinction during edits. Editing tools may hide internal pose representations behind familiar controls such as camera orbit, focal length, and object selection. Physical consistency should also improve as contact shadows, occlusion, and basic lighting changes become tied to the same scene reference. These advances would support more dependable portrait editing, product visualization, and structured spatial content, although difficult cases would still need manual correction.
By the third year, instance-grouped reconstruction could function as an editable scene registry in which users modify or rephotograph named objects rather than selecting pixel regions. Controlled short sequences would become an integration layer linking geometry, motion, and camera estimation, while remaining strongest inside known scene and motion limits. A useful monitoring cue is whether continuity benchmarks begin influencing system comparisons and whether tools preserve identity across related viewpoints without repeated setup. The outlook should weaken if major systems retain incompatible scene representations or users continue to find manual workflows faster. Even with a shared reference, non-rigid people may be reconstructed poorly, creative goals may conflict with geometric accuracy, and lighting may remain inconsistent. The likely result after three years is therefore a useful but incomplete scene-control layer rather than a general physical simulator.
During the first year, rising demand for geometry-aware editing may exceed the supply of paired data, 4D processing, and expert review. The contender mechanism responds through Quality of Service routing, similar to sending easy and difficult requests along different processing paths. Camera state, grounding information, and uncertainty scores would describe the risk of a request before the system chooses how to handle it. Low-risk edits could use fast generation, while large viewpoint changes or identity-sensitive work would be routed to explicit reconstruction, extra capture, or human review. The first-year threshold is practical: checking geometry risk must cost less than correcting failed outputs or inspecting every result manually.
If that threshold is met, second-year validators could become middleware between generation systems and production tools. A validator is a component that checks whether an output satisfies required structural conditions before it moves forward. Research would test whether confidence scores remain reliable for sparse or uncontrolled inputs, then broaden checks from shape to physical and temporal consistency. Instance-aware scene graphs could supply reusable information about objects and their relationships, helping the router select an appropriate module for each edit. In applications, users might receive a warning to reduce a camera move, provide another reference, or accept slower processing when failure is likely. Validation records would travel with assets and support controlled camera edits, object placement, and short sequence changes.
By the third year, failed checks and escalated jobs could form hard-negative datasets containing realistic examples of identity drift, unstable grounding, or inconsistent motion. Those datasets would improve validators, while better validators would make routing more trustworthy and reduce unnecessary use of expensive processing. One monitoring cue is the appearance of shared failure datasets and metadata conventions that reliably predict problems in real workflows. The scenario weakens if validator scores do not match actual failures, expert review remains necessary for most cases, or unified models solve the same problems cheaply without routing. Because visual quality is partly subjective and no single organization can impose one geometry schema, adoption may remain fragmented. The three-year outcome would therefore be a layered workflow architecture used where reliability matters, alongside faster best-effort generation for early experimentation.
In the first year, research would begin treating structural failures as hazards that should be detected at the pipeline stage where correction is still inexpensive. This follows the HACCP mechanism, which controls problems at defined checkpoints rather than relying only on inspection of a finished result. Researchers would connect failures such as floating objects, identity drift, and invalid camera changes to specific intermediate states. Evaluation tools would then act as probes inside generation workflows instead of producing only final benchmark scores. The first important threshold is whether at least two checks become fast enough for interactive use and reliable enough to influence whether an output is accepted.
If that threshold is crossed, the second year would bring stronger demand for common structured intermediates. An instance scene graph, meaning a machine-readable record of objects and their relationships, could expose camera state, support surfaces, and edit history for direct inspection. Application teams could attach validation logs to generated assets and place continuity gates within multi-shot or dynamic workflows. These gates would check whether identity, object position, and motion remain coherent over time. Human approval would remain important for unusual compositions because structural validity does not determine whether an image is meaningful or aesthetically suitable.
By the third year, the control-point approach could extend to physical effects and non-rigid motion while connecting reconstruction, generation, and rendering under a shared control layer. Failed outputs would be returned to the stage most able to correct them, while logged failures would provide data for improving later detectors. Some platforms might require recorded evidence that named geometry and continuity checks were passed, creating demand for independent conformance testing. A clear monitoring cue would be creative tools that block structurally invalid renders and record the corrective action taken. The scenario would weaken if tools continue to inspect only final outputs, shared checks impose excessive processing costs, or end-to-end models make intermediate controls unnecessary. Proprietary and incompatible schemas could also prevent checks from moving between systems. After three years, this would remain a conditional architecture for reliable spatial workflows, not a universal solution, because geometric consistency can be measured more easily than visual intent.
1-Year / 3-Year Research-Application Infographic
References
- Floating No More: Object-Ground Reconstruction from a Single Image - Authors: Yunze Man, Yichen Sheng, Jianming Zhang, Liang-Yan Gui, Yu-Xiong Wang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Ctrl&Shift: High-Quality Geometry-Aware Object Manipulation in Visual Generation - Authors: Penghui Ruan, Bojia Zi, Xianbiao Qi, Youze Huang, Rong Xiao, Pichao Wang, Jiannong Cao, Yuhui Shi, / <See Details on Fugu-MT> / License: CC-BY-4.0
- PersonaShot: Benchmarking Person-Centric Narrative Continuity in Multi-Shot Video Generation - Authors: Yuji Wang, Yuheng Chen, Teng Hu, Ran Yi, Yijia Hong, Han Feng, Weijian Cao, Chengjie Wang, Lizhuang Ma, Jiangning Zhang / <See Details on Fugu-MT> / License: CC BY 4.0