Summary
This theme focuses on evaluating whether language models and multimodal systems can genuinely reason across visual, linguistic, and spatial representations rather than rely on superficial benchmark signals. The representative papers argue for tougher and more interpretable evaluations, from visuo-linguistic multi-task suites to drawing-based spatial tests and settings where models generate intermediate visual thoughts.
Situation
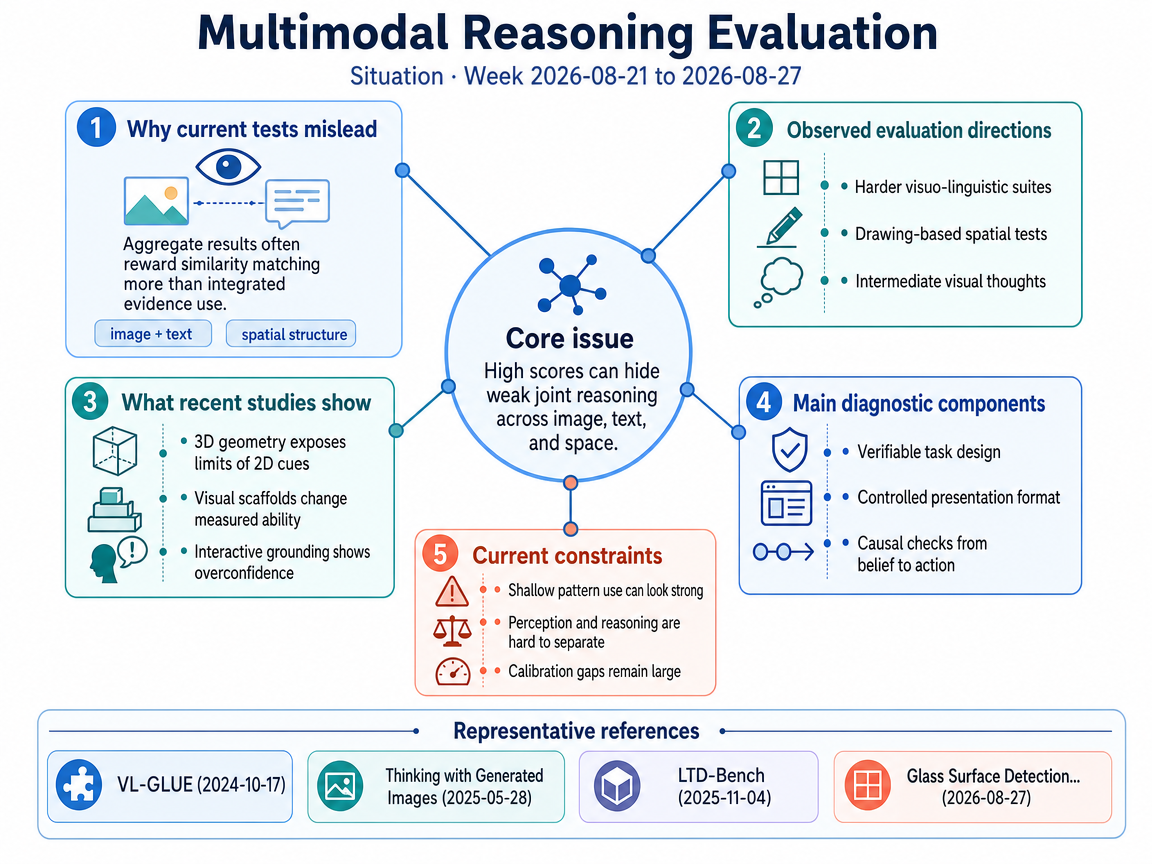
Current evaluation often overstates capability because strong aggregate scores do not reveal whether models can actually integrate text with visual structure or reason about space. VL-GLUE frames this as a gap in true visuo-linguistic inference, arguing that many systems over-rely on image-text similarity rather than joint reasoning over image+text evidence. LTD-Bench makes a similar point for spatial understanding, proposing drawing as a more directly observable test of whether language models can map between language and physical structure. In parallel, "Thinking with Generated Images" argues that text-only chain-of-thought captures only part of problem solving, and that assessment should also cover models that create and use intermediate visual thoughts during reasoning.
Current-week evidence points in a compatible direction. "Glass Surface Detection Grounded in 3D Visual Geometry" (2608.26752v1) argues that 2D appearance-based cues are insufficient for difficult perception problems and motivates explicit reasoning over 3D geometry. While not itself an LLM benchmark paper, it reinforces the underlying evaluation pressure: systems need tests that distinguish shallow pattern use from genuinely grounded multimodal and spatial reasoning.
Infographic (English)
Progress
VBVR-Pro: A Scalable and Verifiable Suite for Native Visual Reasoning <See Details on Fugu-MT>
VBVR-Pro provides a scalable, verifiable testbed for native visual reasoning with 300 procedurally generated task spaces. Unlike earlier broad benchmarks, it makes reasoning generation controllable and surfaces recurring VLM-as-a-judge failure modes.
Is Visual Prompting All You Need? Studying VLM Spatial Reasoning under Progressive Visual Scaffolds <See Details on Fugu-MT>
This study shows that lightweight visual scaffolds can substantially change measured VLM spatial-reasoning performance and failure modes. It demonstrates that benchmark presentation format itself can determine whether a test measures basic perception, downstream reasoning, or a mixture of both.
When Seeing Is Not Enough: Benchmarking Interactive Visual Grounding in LVLMs <See Details on Fugu-MT>
This work introduces controlled evaluation for interactive visual grounding in LVLMs across multiple visual contexts and interaction protocols. It reveals large gaps to human baselines and overconfident calibration, going beyond raw accuracy shortfalls.
CARD: Diagnosing Belief to Action Routing Failures in Vision Language Models <See Details on Fugu-MT>
CARD diagnoses whether mental-state representations in VLMs are actually routed into downstream action predictions. Compared with outcome-only benchmarks, it adds a causal diagnostic by steering one belief axis and measuring cross-axis responses.
Outlook
Outlook Summary
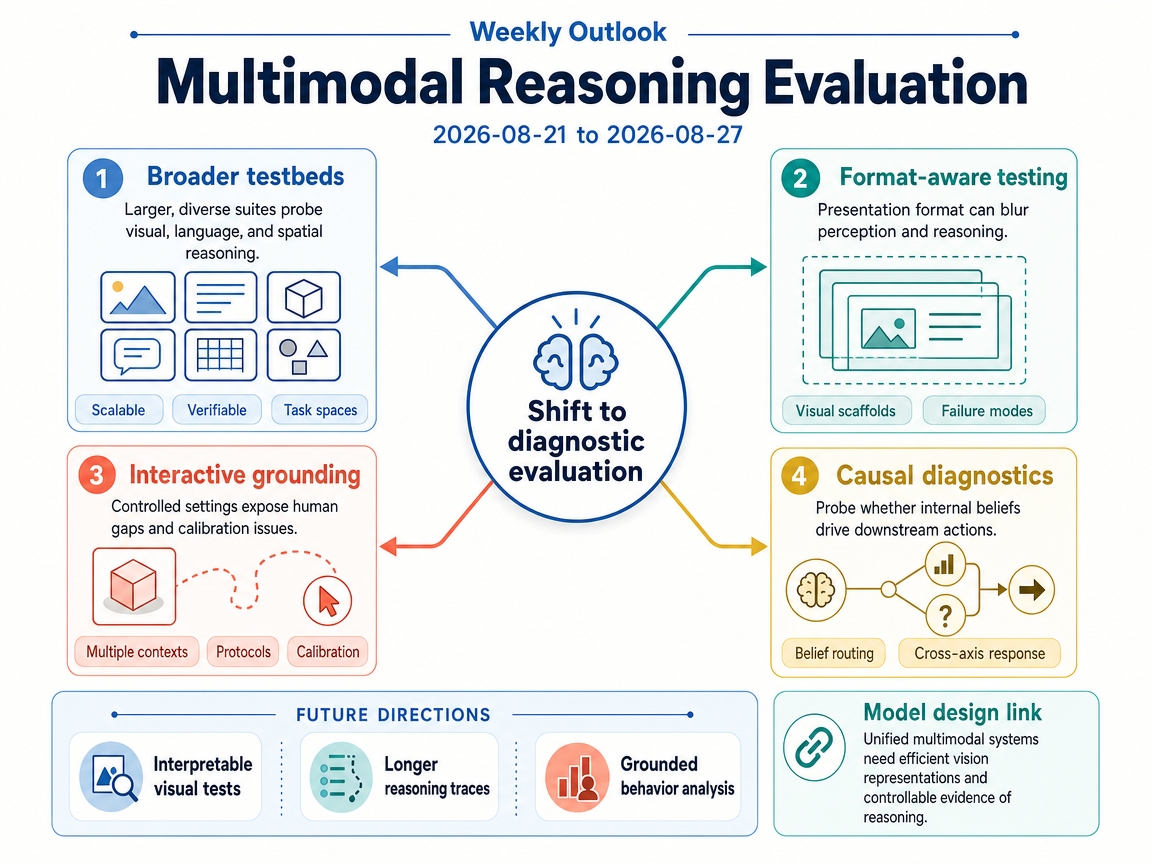
Multimodal evaluation is likely to move from broad scores toward tests that diagnose visual grounding, spatial inference, and reasoning with intermediate visual states. Larger, more varied, and automatically verifiable benchmarks will help separate perception failures from reasoning failures and reveal when task format distorts results. Evaluation will also become more closely tied to unified multimodal model design. Progress in efficient visual representations and longer reasoning traces will be judged not only by accuracy, but also by inspectable evidence, calibration, and systematic analysis of where grounded reasoning breaks down.
Infographic (English)
Three-Year Movement
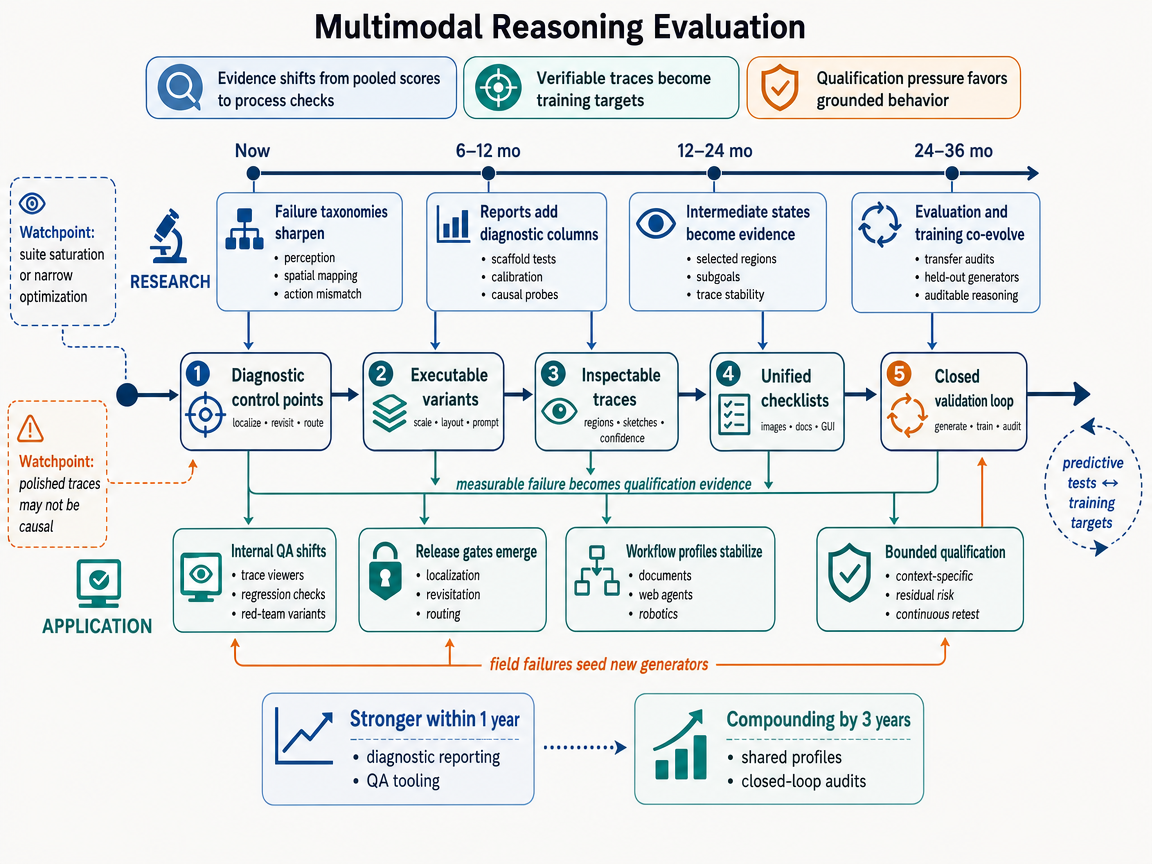
The shift begins with evaluation that exposes where multimodal reasoning fails rather than reporting only an average score. Existing benchmarks have revealed weaknesses in joint image-text inference, spatial mapping, and visual abstraction. This week’s procedural tasks and interactive probes make those weaknesses easier to observe and verify. The mechanism is observability: once a hidden failure is measured at a named step, researchers can train against it and application teams can use it in release decisions.
In the first year, researchers will combine procedural generation with tests of drawings, visual scaffolds, and action routing. Model reports should start separating perception errors from format effects and reasoning mistakes. Teams developing robots, interface agents, or document tools will add these diagnostics to internal comparisons. Some will restrict a model that achieves high average accuracy but repeatedly selects the wrong region or acts on a mistaken visual belief. This creates a feedback loop in which measurable failures influence training priorities and qualification rules.
In the second year, separate tests are likely to consolidate into broader checklists that cover static content, interactive environments, and short video. Unified multimodal models may expose sketches or selected regions as intermediate visual states, while evaluation tools check whether those states are stable and useful. A strong monitoring cue will be routine scaffold ablations, region-visit logs, and documented release decisions based on grounding evidence. By the third year, evaluation and training could form a closed validation loop in which generated challenges improve models and then audit whether improvements transfer to new settings. Models with similar final accuracy would be distinguished by calibration, localization, and whether their actions follow the available evidence. This path would weaken if procedural suites are quickly saturated, diagnostic gains do not transfer, or teams continue to rely mainly on pooled scores.
This scenario develops diagnostic multimodal evaluation into a form of property-based testing borrowed from software engineering. Researchers define a relation that should remain true, such as one object staying above another, and automatically generate many valid variations. A model update is then checked across those variations rather than judged by one fixed benchmark. The mechanism is repeated conformance testing, although multimodal models remain harder to specify because their outputs are variable and some tasks have no single complete answer.
In the first year, research groups will build executable libraries that vary presentation, viewpoint, and visual access while preserving a declared property. These tests will inspect final answers alongside grounded evidence such as coordinates or region-revisit records. Teams will rerun the checks after changes to a model, prompt, or tool configuration. The operational threshold is crossed when such a test finds a meaningful regression that an aggregate score missed and directly changes a release decision.
During the second year, successful results should encourage shared descriptions of visual properties, interaction state, and test coverage. Independent groups will examine whether the same checks predict errors across different models and environments. Practical adopters may introduce versioned qualification profiles for bounded workflows, while held-out generators reduce the risk of optimizing only for familiar cases. A key monitoring cue will be a reproducible reversal in which ordinary benchmark rankings disagree with rankings based on preserved properties.
By the third year, operational failures could be converted into generator rules that create related but nonidentical cases. These cases would expand regression coverage and guide improvements in grounding, revisitation, and calibrated action. Continuous assurance services could then test updates before visually grounded systems are used, with models qualified for declared contexts rather than treated as universal reasoners. The path would weaken if generated variations contain misleading artifacts, model rankings never change, or no shared specification format gains support across several research groups.
The starting point is concern that strong headline scores can hide weak spatial reasoning, visual abstraction, or joint image-text inference. Procedural tasks make answers easier to verify, while scaffold experiments show that presentation format can alter measured performance.Interactive and causal tests add a further question: does a model’s apparent visual belief actually guide its action? The proposed mechanism is continuous stress testing, which repeatedly changes task conditions and inspects grounded behavior instead of trusting one historical score.
In the first year, researchers will rescore systems under controlled changes to prompts, rendering, and access to image regions. Drawings and interaction traces should make failures easier to inspect without treating a fluent explanation as proof of reasoning. Generated intermediate images will receive particular scrutiny because a convincing picture may not reflect genuine spatial competence. Application teams working with interface agents, technical diagrams, or robots may add these traces to internal quality checks. The scenario’s threshold would be crossed if several evaluators treat missing or unreliable trace evidence as a qualification failure.
In the second year, a small evaluation packet could stabilize around scaffold tests, fresh procedural tasks, and interactive grounding checks. Training and evaluation would then reuse regenerated task families, creating a feedback loop between requested evidence and model improvement. Developers would improve visual grounding and selective revisitation, while evaluators refresh generators and test whether intermediate traces truly affect actions. A strong monitoring cue would be consistent changes in model rankings when presentation varies, especially when causal tests still expose weak action routing.
By the third year, behavioral evidence could carry greater weight in qualification for higher-consequence visual workflows. Research reports and release checklists would compare accuracy with trace faithfulness and calibration. Systems offering standardized, revisitable evidence could form a more inspectable tier, while opaque systems remain limited to lower-consequence assistance. This remains less likely than the standard path because trace requirements may stay optional and task-success scores may remain dominant. The scenario would lose support if scaffold effects disappear, procedural suites saturate quickly, or causal diagnostics fail to predict downstream errors.
1-Year / 3-Year Research-Application Infographic
References
- VL-GLUE: A Suite of Fundamental yet Challenging Visuo-Linguistic Reasoning Tasks - Authors: Shailaja Keyur Sampat, Mutsumi Nakamura, Shankar Kailas, Kartik Aggarwal, Mandy Zhou, Yezhou Yang, Chitta Baral, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Thinking with Generated Images - Authors: Ethan Chern, Zhulin Hu, Steffi Chern, Siqi Kou, Jiadi Su, Yan Ma, Zhijie Deng, Pengfei Liu, / <See Details on Fugu-MT> / License: CC-BY-SA-4.0
- LTD-Bench: Evaluating Large Language Models by Letting Them Draw - Authors: Liuhao Lin, Ke Li, Zihan Xu, Yuchen Shi, Yulei Qin, Yan Zhang, Xing Sun, Rongrong Ji, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Glass Surface Detection Grounded in 3D Visual Geometry - Authors: Yiwei Lu, Ke Xu, Tao Yan, Xiaojun Chang, Radu Timofte, Rynson W. H. Lau / <See Details on Fugu-MT> / License: CC BY 4.0