Summary
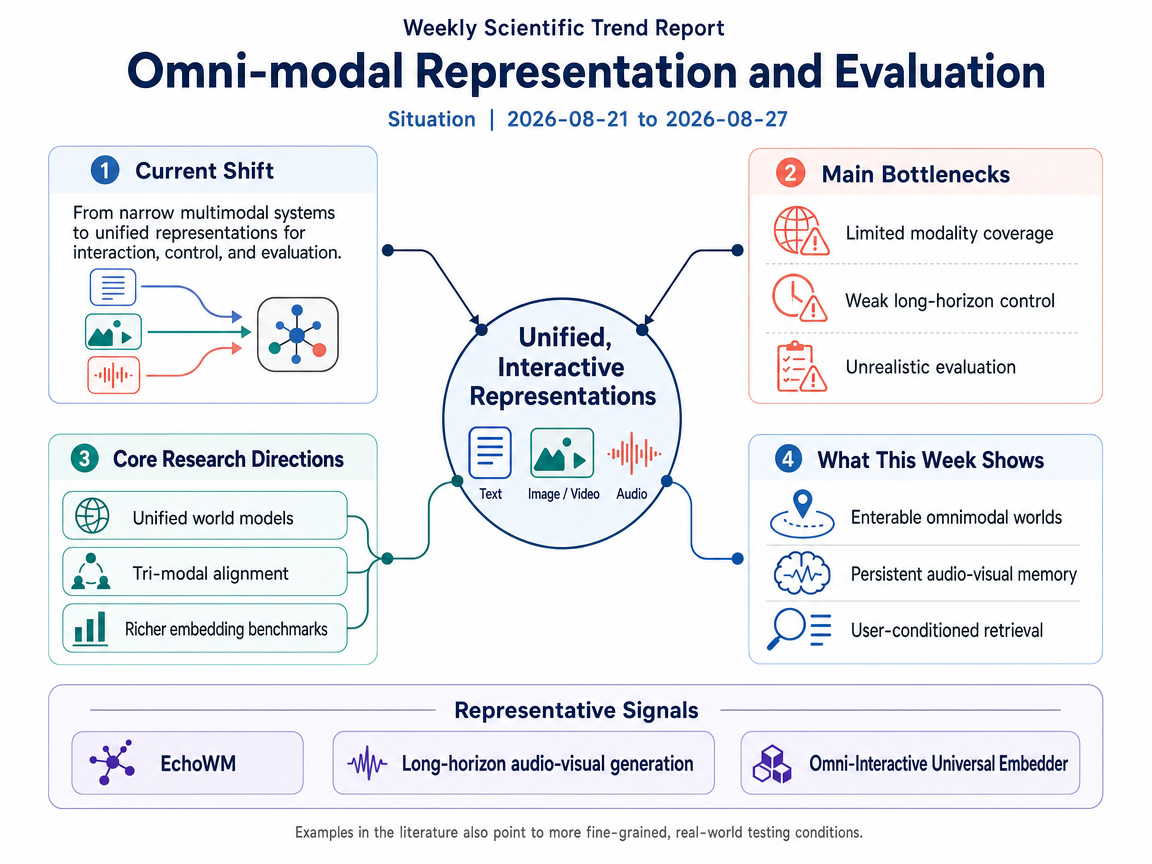
This theme centers on models that unify multiple modalities while making their representations more controllable and more meaningfully testable. Representative papers frame the main bottlenecks as limited modality coverage, weak long-horizon or fine-grained control, and evaluation setups that do not reflect real interactive use, prompting work on unified world models, tri-modal alignment, and richer embedding benchmarks.
Situation
Representative introductions describe a transition from narrow multimodal systems toward more unified representations that support interaction, control, and evaluation. OmniNWM argues that driving world models are still constrained by short RGB-centric state modeling, sparse action encodings, and weak reward integration, and pushes toward a single framework that jointly models multi-modal state, action, and intrinsic reward. Nexus-O makes a parallel case on the perception side: tri-modal language-vision-audio systems remain limited by scarce high-quality datasets, expensive alignment, and insufficient robustness evaluation, so progress depends not just on adding modalities but on aligning them efficiently and testing them in realistic settings.
The same pressure is visible in current-week embedding work. Omni-Interactive Universal Embedder (arxiv:2608.27044v1) argues that text-only interaction is too coarse for many retrieval and representation tasks, and proposes omni-interactions across text, visual, and audio prompts together with a new benchmark, OmniCHOIR, for user-conditioned multimodal retrieval. Taken together with application-oriented evidence such as SynthScribe, the situation suggests a field moving from static multimodal encoding toward representations that are interactive, user-conditioned, and evaluated under more fine-grained real-world conditions.
Infographic (English)
Progress
EchoWM: Open and Enterable Omnimodal World Models <See Details on Fugu-MT>
EchoWM extends unified world modeling to enterable omnimodal media by jointly generating 720p video, ambient sound, music, and speech under continuous navigation. This broadens the theme from RGB- or tri-modal setups to a single interactive model that couples scene evolution with richer audio channels.
Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds <See Details on Fugu-MT>
JoyAI-Echo-1.5 introduces cross-shot memory and a world-model variant that injects calibrated 6-DoF navigation trajectories for long-horizon audio-visual generation. Compared with short-context multimodal generation, it adds persistent identity coherence and explicit interactive camera control over extended sequences.
Omni-Interactive Universal Embedder <See Details on Fugu-MT>
OmniUE learns a unified embedding space across text, video, and audio and supports user-conditioned querying via text, visual regions, and audio spans. It moves beyond text-only retrieval interfaces by making multimodal representations directly interactive and benchmarkable through the new OmniCHOIR evaluation suite.
Outlook
Outlook Summary
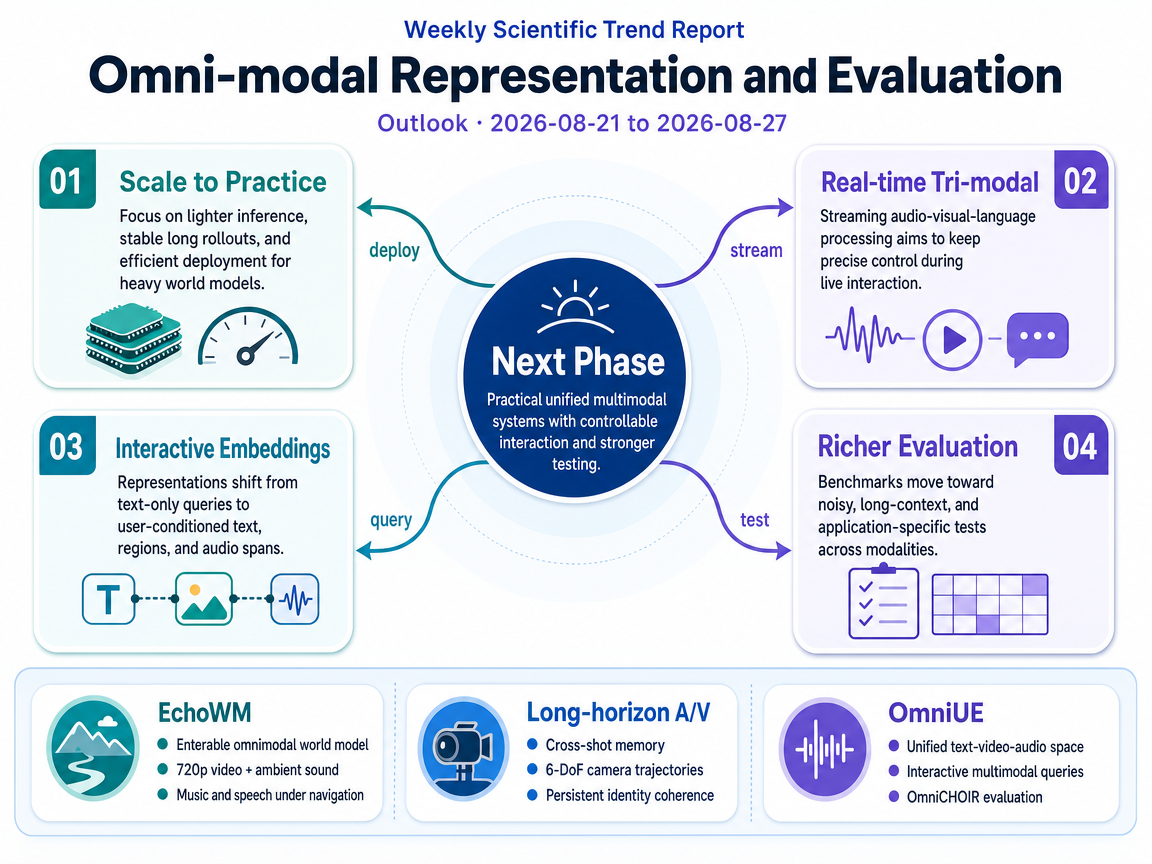
Unified multimodal models are likely to become more practical rather than simply support more input types. Recent work on long-horizon generation, audio-visual interaction, and navigation-controlled worlds points to lighter inference, more stable rollouts, and real-time processing with precise control. Representations are also shifting beyond static text toward embeddings shaped by user-selected visual or audio content. Evaluation will therefore need realistic tests across modalities, especially in noisy, long-context, and specialized settings.
Infographic (English)
Three-Year Movement
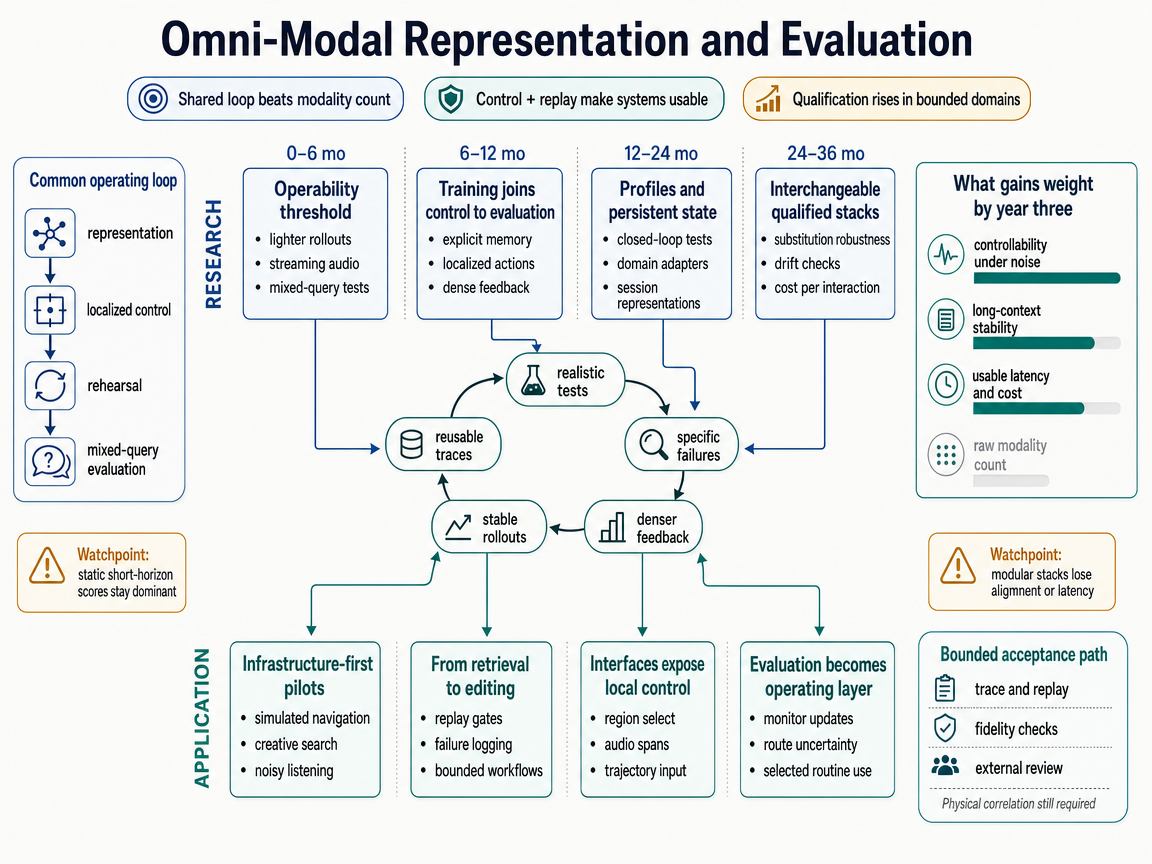
The standard path leads to unified multimodal systems that connect perception, interaction, generation, and evaluation in one operating loop. The first year establishes the practical base by reducing inference costs, adding streaming audio, and making mixed-query tests routine. Researchers also work on memory and identity consistency so that generated worlds remain stable over longer sessions. Simulators and creative tools begin using localized controls, such as selected regions or trajectories, rather than relying only on broad text prompts.
In the second year, closed-loop evaluation becomes more common. This means that a model acts, observes the result, and adjusts its next action within the same test. User-conditioned embeddings, which represent a user’s selected examples or content, persist across a session instead of being rebuilt for every request. Specialized adapters appear where general models fail to represent technical vocabulary or important relationships. Providers also package tests for interruption recovery, navigation response, and long-term consistency.
By the third year, successful systems support sustained rehearsal in navigation, detailed control in creative or industrial tools, and task-specific testing in interactive environments. Comparisons focus less on the number of supported modalities and more on reliable control under noise, stable behavior over long contexts, and computational cost per useful interaction. The main mechanism is a reinforcing evaluation loop: realistic tests reveal control failures, those failures improve feedback, and better feedback stabilizes longer rollouts. Stable rollouts then produce more representative traces that can strengthen later training and evaluation. A useful monitoring cue is whether mixed-query interfaces and long-session tests become normal parts of professional tools and benchmark services. This path weakens if short static tests remain dominant, real-time audio performs poorly in noisy settings, or repeated long rollouts remain too expensive.
The contender path produces a federated multimodal stack rather than one model that must perform every function internally. Its mechanism comes from telecommunications-style interoperability: shared interface contracts, replay tests, and conformance checks allow components to be replaced without rebuilding the entire system. During the first year, researchers translate exposed controls into timestamped interaction records. These records capture inputs, model state, and feedback while preserving the order and timing of events. Benchmarks then test synchronization, control adherence, and recovery instead of demanding identical output from every replay.
By the second year, benchmark maintainers and tooling providers formalize a small set of interaction profiles. A profile states what a system must accept, what behavior it must expose, and how it should recover from failure. Test packs combine synthetic stress cases with protected real-world traces, while human review checks whether automated scores reflect useful behavior. Application teams gain reusable tools for capturing interactions, replaying failures, and observing synchronized streams. Specialized requirements can be added without forcing every organization to use the same model architecture.
In the third year, compatible systems generate more reusable traces, which improve failure categories and regression tests. Better tests make compatibility more valuable when components are updated or replaced. Shared control, logging, and evaluation interfaces then connect specialized representations and generators behind a common layer. Research increasingly studies adaptive routing, continuous checks after updates, and failures caused by disagreement across modalities. A strong monitoring cue is the reuse of one trace-and-replay format across several independent benchmarks or application testbeds. The path is challenged if modular systems continue to suffer major latency or alignment losses, or if common schemas split into incompatible versions. Conformance can verify observable timing and behavior, but it cannot guarantee equivalent meaning or open-world safety, so end-to-end tests and human review remain necessary.
The maybe path applies a qualification model similar to high-fidelity simulator approval. A generated environment would be accepted for bounded testing only after it demonstrates control accuracy, robustness, and a reliable relationship with physical observations. In the first year, researchers turn model-specific scores into reproducible fidelity protocols. These protocols measure how closely generated structure matches expected occupancy, how accurately trajectories follow controls, and how long a rollout stays within stated error limits. Adversarial tests also search for scenes that appear plausible but follow incorrect physical rules.
In the second year, progress depends on a public body or large procurer accepting evidence from a qualified stack for a narrow operating domain. Evaluation then separates world dynamics, perception, and control response so that each layer can be examined independently. Public reference scenarios and independent correlation studies become important because generated tests need agreed comparisons with physical behavior. Traceable records identify the model version, scenario source, and observed failure. Physical tests still remain part of the process, especially for unusual or safety-relevant cases.
By the third year, bounded qualification could create a reinforcing cycle. Qualified virtual tests reduce repetitive physical work, allowing larger conformance test batteries and more stable models. Better performance can then widen the range of scenarios accepted for virtual testing. Tiered schemes may separate routine regression checks from evidence requiring higher assurance, while related methods extend to warehouse robots or inspection drones. A decisive monitoring cue is the appearance of limited acceptance programs supported by versioned reference banks and independent test laboratories. This path weakens if authorities accept only replay systems or conventional physics engines, or if model scores fail to predict physical closed-loop behavior. High inference costs could also prevent the repeated test runs needed for credible qualification.
1-Year / 3-Year Research-Application Infographic
References
- SynthScribe: Deep Multimodal Tools for Synthesizer Sound Retrieval and Exploration - Authors: Stephen Brade, Bryan Wang, Mauricio Sousa, Gregory Lee Newsome, Sageev Oore, Tovi Grossman / <See Details on Fugu-MT> / License: CC-BY-4.0
- Nexus-O: An Omni-Perceptive And -Interactive Model for Language, Audio, And Vision - Authors: Che Liu, Yingji Zhang, Dong Zhang, Weijie Zhang, Chenggong Gong, Haohan Li, Yu Lu, Shilin Zhou, Yue Lu, Ziliang Gan, Ziao Wang, Junwei Liao, Haipang Wu, Ji Liu, André Freitas, Qifan Wang, Zenglin Xu, Rongjuncheng Zhang, Yong Dai, / <See Details on Fugu-MT> / License: CC-BY-4.0
- OmniNWM: Omniscient Driving Navigation World Models - Authors: Bohan Li, Zhuang Ma, Dalong Du, Baorui Peng, Zhujin Liang, Zhenqiang Liu, Chao Ma, Yueming Jin, Hao Zhao, Wenjun Zeng, Xin Jin, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds - Authors: Nan Duan, Haoyang Huang, Weiyang Jin, Haoran Li, Yaowei Li, Yuming Li, Yijun Liu, Xin Lu, Xiaoxiao Ma, Yanwen Ma, Yaofeng Su, Yilang Sun, Haoyu Wang, Zeyue Xue, Songchun Zhang, Junhao Zhuang / <See Details on Fugu-MT> / License: CC BY 4.0
- Omni-Interactive Universal Embedder - Authors: Wei-Yao Wang, Kazuya Tateishi, Shuyang Cui, Christian Simon, Takashi Shibuya, Shusuke Takahashi, Yuki Mitsufuji / <See Details on Fugu-MT> / License: CC BY 4.0