Summary
This theme centers on the shift from evaluating agents in fixed setups to scaling the environments, interaction loops, and runtime scaffolds that shape agent behavior. Representative papers argue that stronger agent performance depends not only on model reasoning, but also on richer task generation, more realistic interaction, better feedback, and task-appropriate harness design.
Situation
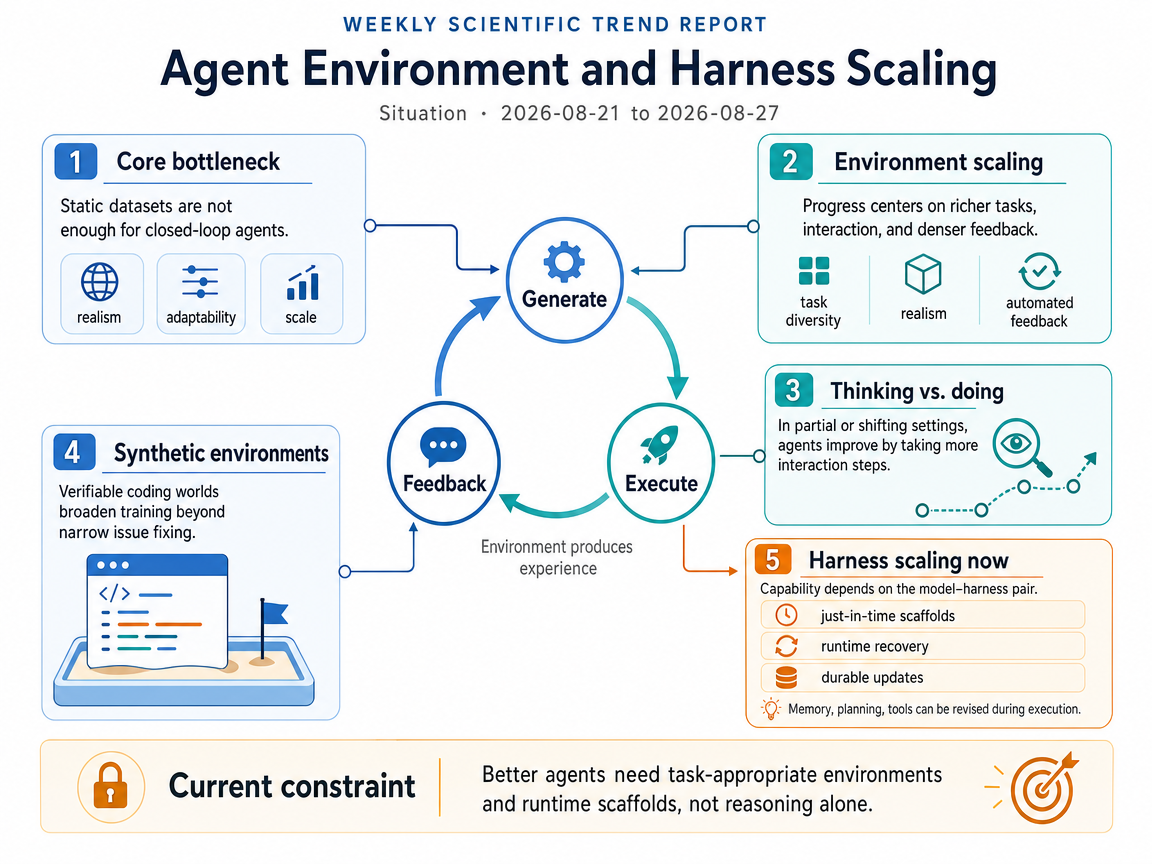
Representative introductions frame a common bottleneck: supervised training on static datasets does not provide enough realism, adaptability, or scale for agents that must act in closed-loop environments. The survey "Scaling Environments for LLM Agents in the Era of Learning from Interaction" treats the environment as an active producer of experience and organizes progress around the generation-execution-feedback loop, emphasizing task complexity and diversity, richer interactivity and realism, and denser, more automated feedback. In parallel, "Thinking vs. Doing: Agents that Reason by Scaling Test-Time Interaction" argues that in partially observable or non-stationary settings, agents need to gather information through additional interaction steps rather than only think longer before acting.
Secondary evidence extends this environment-centric view into software agents: "Training Versatile Coding Agents in Synthetic Environments" argues that fully synthetic, verifiable coding environments can broaden training beyond narrow issue-resolution tasks and reduce dependence on existing repositories. As current-week evidence, "JIT-Agent: Scaling Harness Intelligence via Just-in-Time Harness Evolution" (2608.25593v1) pushes the discussion from environment design to harness design, arguing that agent capability is a property of the model–harness pair and that task-specific memory, planning, action, and capability scaffolds may need to be generated and revised just in time rather than fixed ahead of deployment.
Infographic (English)
Progress
JIT-Agent: Scaling Harness Intelligence via Just-in-Time Harness Evolution <See Details on Fugu-MT>
JIT-Agent trains a harness-intelligence model that synthesizes task-adaptive agent harnesses at inference time via a three-stage pipeline of customization, repair, and evolutionary optimization. What is new is treating just-in-time harness generation itself as a learned capability rather than relying on a fixed, ahead-of-time scaffold.
Prime Agent: A Self-Improving RLM Harness <See Details on Fugu-MT>
Prime Agent provides an open-source harness that standardizes execution, recovery, verification, and resource accounting for long-horizon coding agents. What is new is demonstrating that a disciplined runtime harness can yield large performance gains while leaving strategy formation entirely to the model.
AutoSaddler: Automatic Harness Optimization with Durable Updates from Agent Execution Traces <See Details on Fugu-MT>
AutoSaddler formulates harness optimization as an offline learning problem, iteratively refining prompts, tools, and middleware from failure signals in agent execution traces. What is new is a principled loop of diagnosis, structured patching, and generalization-aware selection that produces durable harness updates across multiple benchmarks.
Verify Smarter, Evolve Further: Efficient Harness Evolution through Behavior-Aware Verification <See Details on Fugu-MT>
HarnessLens introduces a budget-aware verification framework that scores harness candidates more efficiently during automated harness evolution. What is new is behavior-aware verification that avoids exhaustively evaluating every candidate on a fixed task set.
TRACE: A Self-Evolving Skill Bank for Consistent, Limit-Aware LLM Agents <See Details on Fugu-MT>
TRACE iteratively improves a skill bank that stabilizes agent behavior without changing model weights, raising consistency substantially. What is new is using self-evolving behavioral knowledge as part of the runtime scaffold to convert high model potential into more consistent performance.
Outlook
Outlook Summary
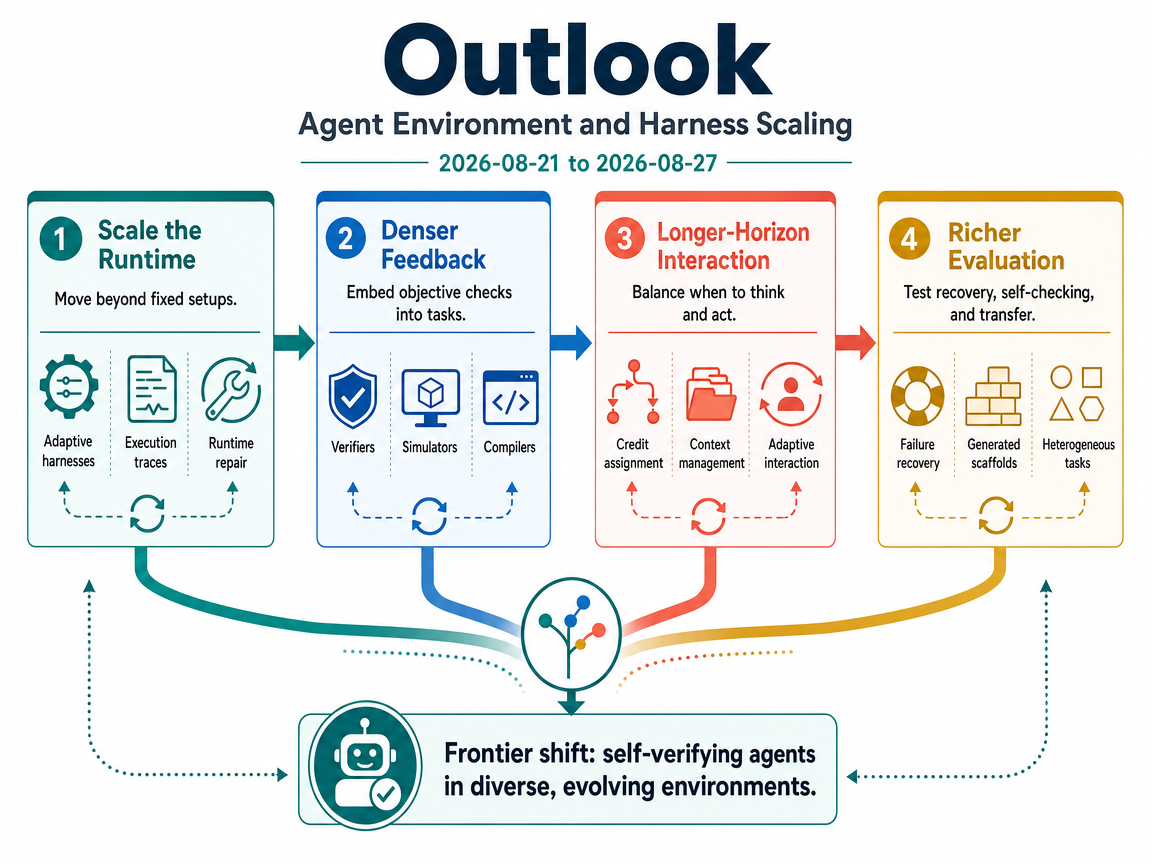
Near-term work will shift from fixed agent designs toward jointly scaling environments, feedback loops, interaction time, and runtime harnesses. Embedded tests, compilers, and simulators can provide dense, objective signals, while adaptive harnesses can be generated or repaired from execution traces. Evaluation will therefore examine the complete system, including whether an agent uses feedback, recovers from failure, and transfers across changing scaffolds. Longer-horizon research will also study when agents should think, act, or gather more information. The broader direction is toward self-checking agents trained and tested in diverse, verifiable coding, web, and multi-agent environments.
Infographic (English)
Three-Year Movement
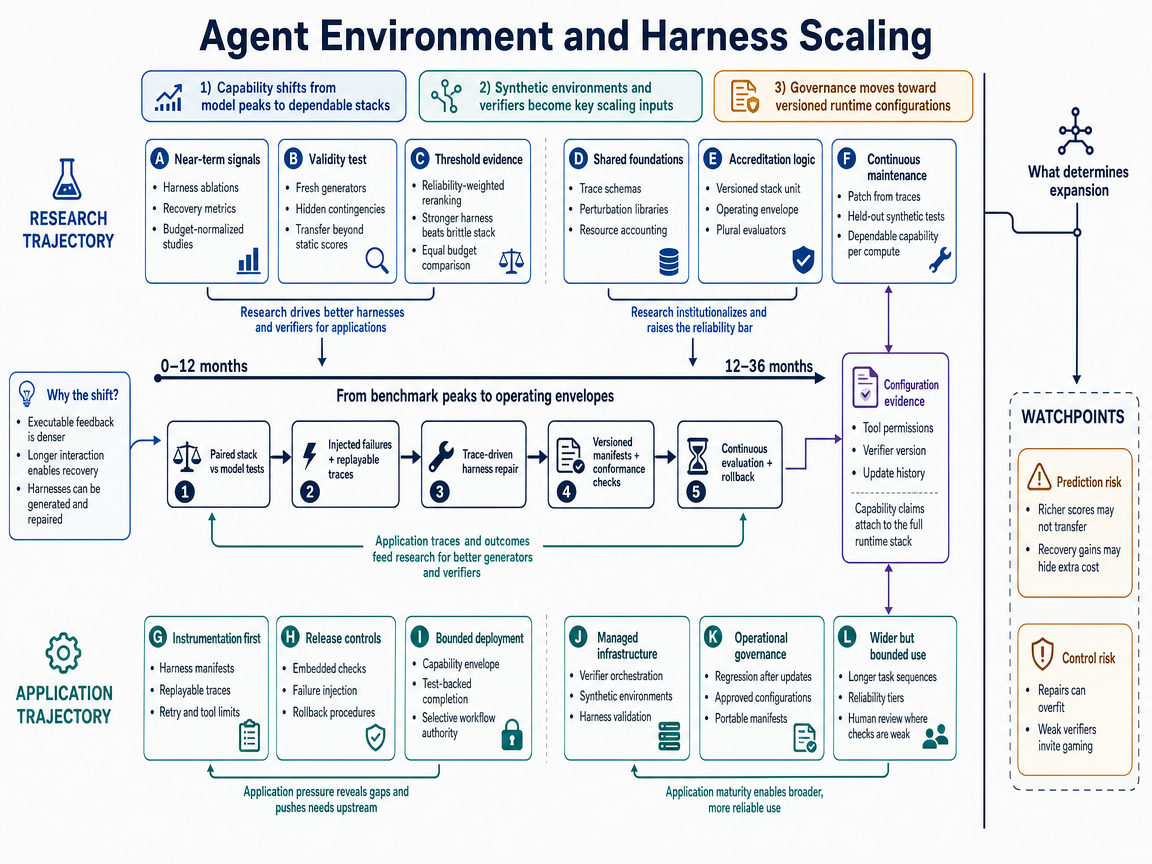
The main shift is from comparing model snapshots toward evaluating complete, versioned model-plus-harness systems. A harness is the surrounding runtime that controls tools, feedback, and recovery. Objective checks from tests, compilers, and simulators will help determine whether these systems deliver dependable results rather than occasional peak performance.
In the first year, coding and web evaluations will compare complete systems under equal limits on time, actions, and computation. Generated task variants will expose systems to stale observations, broken tools, or interrupted work. The important threshold will be a reproducible change in rankings, where a system with lower peak performance wins because it completes more fresh tasks reliably. Organizations will support this testing with replayable traces, explicit checks, and rollback procedures, then allow wider use only within a documented capability envelope.
In the second year, common technical foundations should emerge if these reliability scores predict practical outcomes. Shared trace formats, harness descriptions, and resource-accounting rules will make independent comparison easier. This creates a reinforcing mechanism: dependable systems receive more use, their traces reveal new failures, and those failures improve generators and recovery methods. Updates to tools or surrounding runtime components will increasingly trigger regression tests before release.
By the third year, evaluation and maintenance could become continuous. Automated control systems may propose harness repairs from traces, test them in unseen synthetic environments, and reverse them when reliability falls. A useful monitoring cue is whether organizations begin granting longer tasks and lower supervision to accredited versions of complete systems rather than to models alone. The path would weaken if richer scores fail to predict performance on fresh tasks, or if apparent recovery gains disappear after equalizing resource use. Even successful systems will still need multiple evaluators and regular audits because semantic tasks can be ambiguous or deliberately game weak checks.
This scenario treats environment generation and runtime adaptation as major sources of capability, not merely support for a model. Generated tasks provide varied experience, while executable checks close the feedback loop between action and correction. The harness can then be repaired from execution traces, allowing the whole system to improve without changing model weights.
During the first year, researchers will test synthetic environment pipelines beyond software development, especially in web and structured tool-use work. Evaluations will separate gains from the model, its environment, and the surrounding harness. Failed trajectories will be diagnosed and replayed after a prompt or tool policy is changed. Systems will also learn when to gather more information, backtrack, or stop rather than using the same interaction length for every task. Practical platforms will combine generated tasks, sandboxed execution, and trace capture, with each harness change versioned and checked for regressions.
The decisive early threshold is an independently reproduced result showing that a mid-size model with a strong adaptive harness can outperform a larger model with a weak one on unseen, long-horizon tasks. If that occurs, the second year will bring more routine trace-driven maintenance and fuller descriptions of complete systems. Useful behavior may also be retained in reusable scaffolds that survive model updates. The mechanism is cumulative: wider use produces more traces, those traces improve recovery and verification, and stronger systems can safely attempt broader tasks.
By the third year, reusable environment generators, sandboxed tools, and verifier components could form a common technical substrate. Smaller teams could assemble long-horizon systems without manually designing every task and check. A strong monitoring cue is whether complete model-plus-harness systems become the normal unit of evaluation and selection. The main caveat is verifier weakness: generated tasks can drift, leak answers, or reward unintended behavior. Failed transfer to unfamiliar settings, rapidly rising verification costs, or continuing difficulty separating harness gains from model gains would confine this approach to tasks with clear executable outcomes.
As harnesses become able to change from execution traces, capability will depend on a shifting runtime configuration rather than a stable model alone. This creates an accountability problem because users may not know which tools, checks, or recovery rules were active during a failure. The scenario therefore centers on making each deployed configuration identifiable and testable.
In the first year, researchers will develop methods that separate model behavior from the effects of prompts, tools, and verifiers. Machine-readable manifests, signed update histories, and execution replay will record what changed and help reproduce incidents. Synthetic coding and web environments will also become conformance tests, meaning repeatable tasks used to check whether an updated system still meets defined requirements. Organizations will begin requesting evidence about runtime controls and update logging, although practices will initially remain informal. A visible failure caused by a changed verifier or recovery rule could accelerate demand for clearer disclosure.
In the second year, the key threshold is adoption of compatible requirements by at least two influential buyers or evaluation bodies. Compatible manifests would make configurations comparable, allowing acceptance tests to assess versioned model-plus-harness systems. This creates a feedback mechanism in which comparable records support stronger testing, while test results clarify which runtime changes require renewed approval. Research will focus on affordable conformance suites and on deciding when an automatically modified harness must be checked again.
By the third year, high-consequence deployments could treat the certified configuration and its update history as the deployable unit. Automated gates would test proposed changes in synthetic environments before release, while trace-based checks would monitor changes made during operation. A harness bill of materials could support this process, but it would need to behave like an evolving record linked to behavioral evidence rather than a static component list. The clearest monitoring cue is convergence on compatible fields, mandatory version reporting, and independent conformance tests. The path would weaken if organizations prefer outcome-only testing, suppliers resist structural disclosure, or manifests become paperwork that does not predict actual behavior.
1-Year / 3-Year Research-Application Infographic
References
- Thinking vs. Doing: Agents that Reason by Scaling Test-Time Interaction - Authors: Junhong Shen, Hao Bai, Lunjun Zhang, Yifei Zhou, Amrith Setlur, Shengbang Tong, Diego Caples, Nan Jiang, Tong Zhang, Ameet Talwalkar, Aviral Kumar, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Scaling Environments for LLM Agents in the Era of Learning from Interaction: A Survey - Authors: Yuchen Huang, Sijia Li, Minghao Liu, Wei Liu, Shijue Huang, Zhiyuan Fan, Hou Pong Chan, Yi R. Fung, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Training Versatile Coding Agents in Synthetic Environments - Authors: Yiqi Zhu, Apurva Gandhi, Graham Neubig, / <See Details on Fugu-MT> / License: CC-BY-4.0
- AutoSaddler: Automatic Harness Optimization with Durable Updates from Agent Execution Traces - Authors: Sungho Park, Wonjoong Kim, Rongyuan Tan, Jue Zhang, Wook-Shin Han, Pengfei Gao, Chanyoung Park, Yongqiang Yao, Rao Fu, Elsie Nallipogu, Qingwei Lin, Saravan Rajmohan, Dongmei Zhang / <See Details on Fugu-MT> / License: CC BY 4.0
- JIT-Agent: Scaling Harness Intelligence via Just-in-Time Harness Evolution - Authors: Guibin Zhang, Leo Lu, Fangzhou Xie, Kang Zhu, Junhao Wang, Zhifei Xie, Zhaochen Yu, Zihang Liu, Zhongxiang Sun, Qiankun Li, Yue Liao, Heng Chang, Xiaobin Hu, Qibing Ren, Wangchunshu Zhou, Shuicheng Yan / <See Details on Fugu-MT> / License: CC BY 4.0