Summary
This theme centers on evaluating AI coding assistants and software-engineering agents beyond narrow benchmarks or final-output metrics. Representative papers emphasize real-world deployment evidence, process-level analysis of agent failures, and broader benchmarks covering tasks such as bug fixing, test generation, code review response, and style enforcement.
Situation
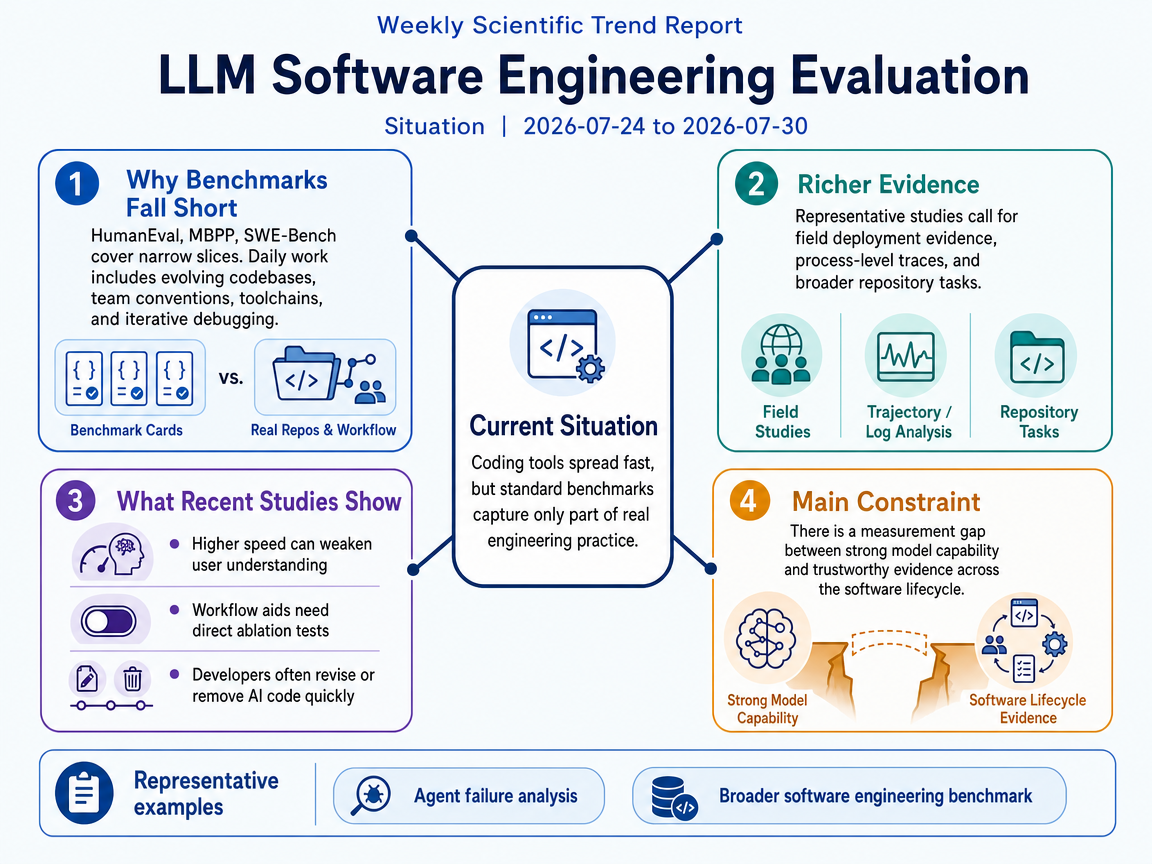
AI coding tools are spreading rapidly across software development, but standard evaluations like HumanEval, MBPP, and SWE-Bench capture only part of real engineering practice. Day-to-day development involves large evolving codebases, team conventions, toolchain integration, and iterative debugging, so benchmark success does not directly establish production utility.
Against this backdrop, the representative papers call for richer evaluation lenses: large-scale field studies of deployment in production organizations, analyses of agent trajectories and testing logs rather than only final patches, and benchmarks spanning a wider range of repository-level tasks. Together, they frame the current situation as a measurement gap between impressive model capabilities and trustworthy evidence about how LLM systems actually perform across the software development lifecycle.
Infographic (English)
Progress
(Im)Paired Programming: Coding Agents Improve Productivity but Harm Understanding <See Details on Fugu-MT>
A controlled user study evaluates coding agents not just on immediate task completion but on later code-extension and comprehension tasks. Unlike benchmark-centric evaluations, it reveals that productivity gains can coexist with weaker user understanding, highlighting a gap standard metrics miss.
Do Context Files Help Coding Agents? A Two-Agent Ablation Study on Real Repositories <See Details on Fugu-MT>
A controlled ablation study tests whether persistent context files actually help coding agents resolve issues on real repositories. Rather than judging only final benchmark scores, it evaluates a specific widespread workflow practice across two frontier agents.
Learning from 53.6K Real-World Developer Edits of AI-Generated Code <See Details on Fugu-MT>
A 53.6K real-world IDE edit dataset tracks how developers revise AI-generated code after accepting completions. Compared with evaluations focused on final outputs, it reveals that most edits occur within 15 minutes of acceptance and 31% of trajectories result in removal of the AI completion.
Fewer Clarifications, Better Code: Benchmarking Cross-Session Personalized Ambiguity Adaptation in Coding Assistants <See Details on Fugu-MT>
A new benchmark evaluates coding assistants on cross-session personalized ambiguity handling, measuring task success and interaction efficiency. Unlike standard coding benchmarks, it tests whether models adapt to user history and reduce clarification turns while still completing tasks.
Outlook
Outlook Summary
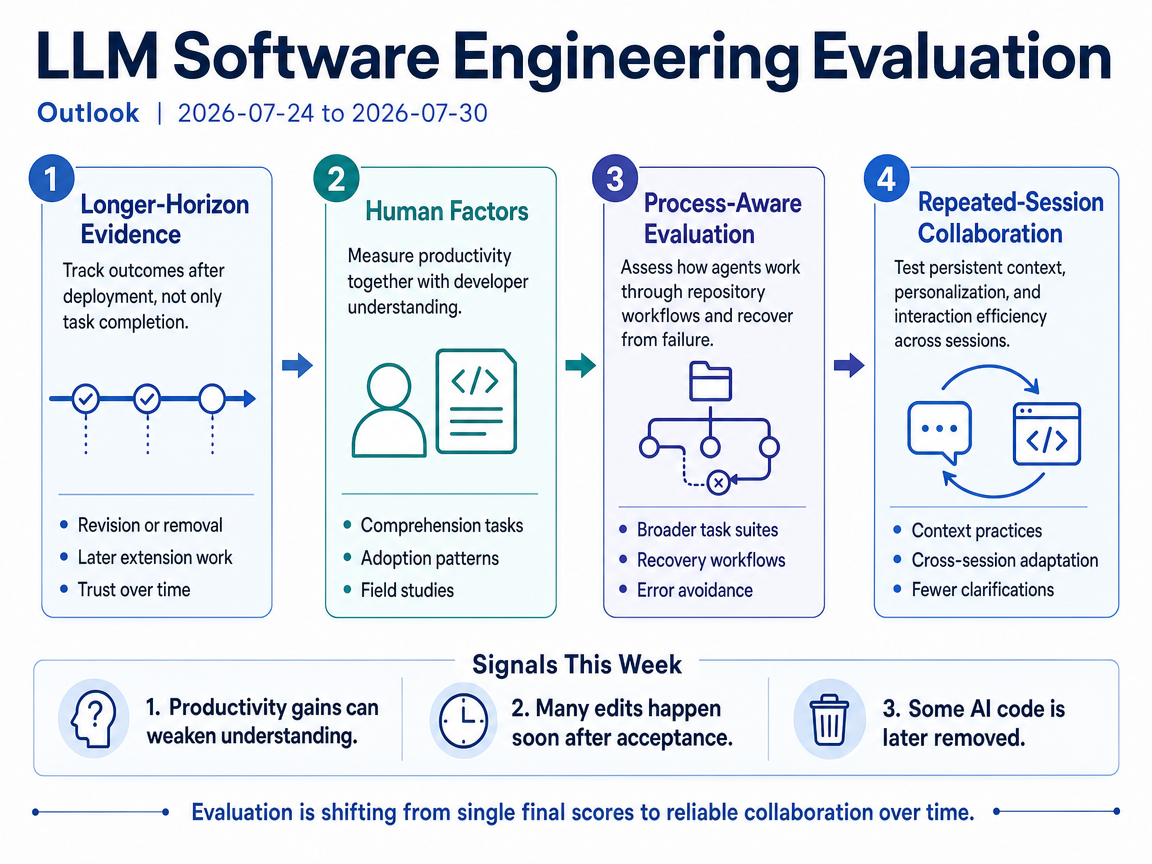
LLM software-engineering evaluation is likely to follow coding agents over longer periods and across multiple organizations. Studies will look beyond task completion to whether generated code survives deployment, whether developers still understand it, and how adoption changes with experience. Evaluation will also become more sensitive to repository workflows and task differences. Instead of relying on one final score, it will examine persistent context, cross-session adaptation, efficient interaction, failure recovery, and collaboration with users during repeated work.
Infographic (English)
Three-Year Movement
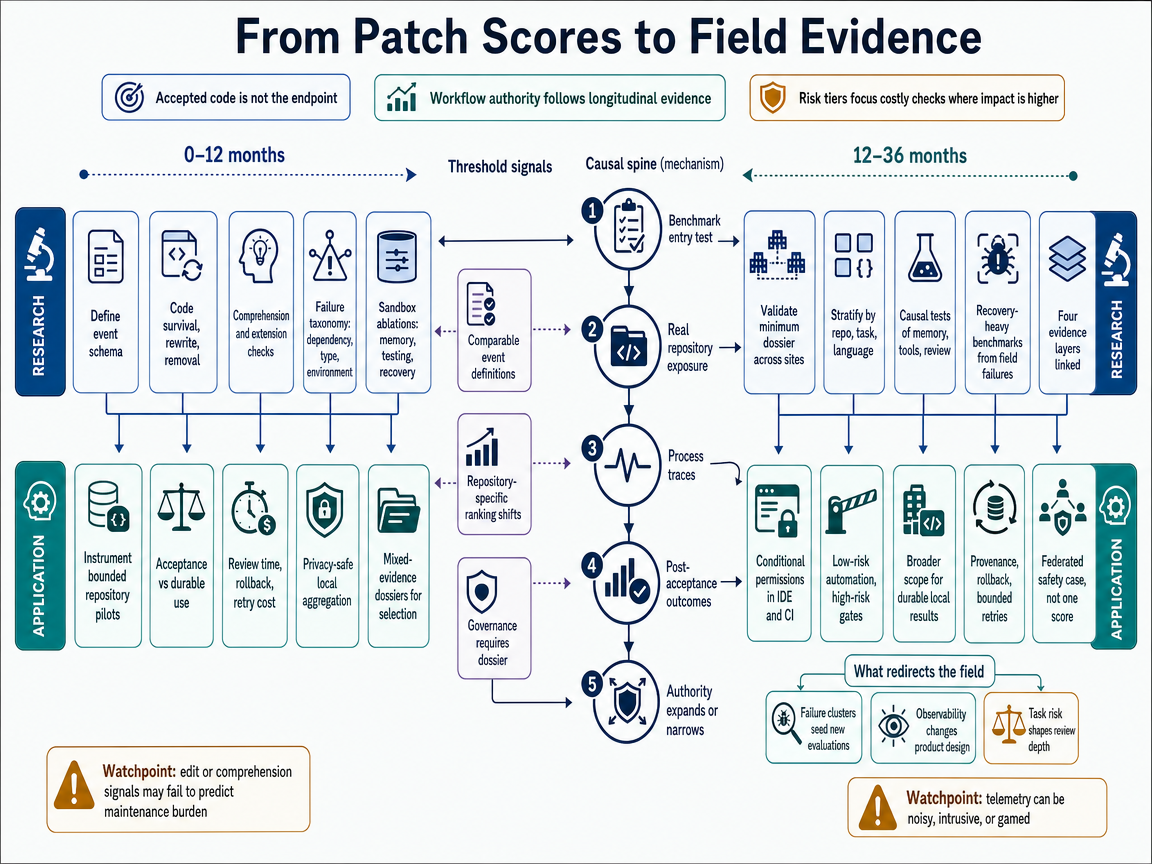
Evaluation is expected to follow coding agents through real repository work rather than end with a successful patch. The scenario borrows the mechanism of pharmaceutical safety monitoring: benchmarks establish initial capability, while deployment reveals warning signals through later edits, regressions, and lost understanding. Benchmark authority is retained, but it can be reduced when later evidence shows persistent problems.
In the first year, researchers will define measures for code survival, substantial rewriting, and retained developer understanding. Open sandboxes will isolate parts of the workflow so that context practices, memory, or recovery logic can be tested separately. Multi-organization studies will then check whether the measures remain meaningful across languages, repositories, and developer experience levels. Organizations will run limited pilots and distinguish immediate acceptance from durable use, applying longer observation and stronger review to consequential changes.
In the second year, reproducible measures could become a compact evaluation dossier used across organizations. Results will be separated by task and repository rather than collapsed into one universal score. Researchers will compare memory, clarification, and recovery policies to identify combinations that improve speed without weakening understanding. Organizations may then grant conditional permissions, widening an agent’s role when local survival and recovery results are strong or narrowing it when rework remains high.
By the third year, real repository evidence should feed directly into new evaluations and product controls. Repeated failure patterns will become reproducible test cases, while bounded retry measures will prevent agents from appearing reliable through uncontrolled debugging. Tools may add stronger provenance, rollback support, and task-tiered controls that adjust an agent’s permitted scope. A useful monitoring cue will be benchmark reports that include downstream outcomes and standardized process logs. The path would be weakened if these measures fail to predict defects or later maintenance effort, or if comparable data cannot be shared safely. Repository differences and continued developer editing also limit the safety-monitoring analogy, so task stratification and predeclared observation periods remain important safeguards.
Coding-agent evaluation is moving from narrow benchmarks toward evidence collected during real software workflows. This scenario uses a tiered inspection mechanism: every AI-assisted change receives inexpensive checks, while changes with greater consequences receive stronger testing or human review. The trigger is evidence that accepted code may soon be revised or removed and that faster completion can coexist with weaker understanding.
During the first year, researchers will connect benchmark results with IDE events, pull-request histories, and automated test outcomes. Organizations will add reliable origin tags for AI-assisted changes and measure later rework separately from initial acceptance. Routine style changes may be monitored statistically, while security-sensitive code, migrations, or database changes receive more demanding checks. The key threshold is whether local evidence becomes reliable enough to alter agent rankings, repository permissions, or rollout decisions.
In the second year, common event definitions should make results easier to compare without exposing source code or complete developer traces. These records will describe context use and recovery behavior, while broader outcome measures capture later edits and review burden. Field failures will also shape benchmarks that test whether an agent can recognize a problem and recover efficiently, rather than merely produce a passing patch after repeated attempts. Organizational approval processes may begin requesting this task-specific evidence alongside public benchmark results.
By the third year, evaluation could operate as part of workflow control. Low-consequence contributions would pass through automated checks and statistical monitoring, while consequential changes could trigger replay, additional tests, or human sign-off. Memory and tool use would be evaluated as parts of the complete agent configuration because they can change rework and recovery even when the underlying model stays fixed. The likely result is a set of repository-specific scorecards combining benchmarks, process traces, and downstream outcomes rather than one universal score. A strong monitoring cue would be cases where internal trials rank agents differently from public leaderboards. The path would weaken if telemetry remains too noisy or intrusive to guide decisions, or if broad benchmarks already predict local maintainability well. Since repositories differ greatly and lost understanding is difficult to measure, several imperfect indicators must be interpreted together.
Evaluation may combine benchmark results with process traces, field outcomes, and measures of developer understanding. This scenario again borrows evidentiary sequencing from pharmaceutical safety monitoring. Controlled tests establish initial capability, while real use reveals problems that pre-deployment evaluation cannot estimate well. Post-acceptance edits and later extension work therefore become evidence rather than being treated as activity outside the evaluation.
In the first year, researchers will test whether such events can be measured consistently and separated from normal software editing. Replications will compare repositories, languages, and task types, while privacy-preserving provenance will link accepted suggestions to later changes. Studies will then ask whether rewrite timing, test regressions, or recovery behavior predicts maintenance better than final-patch accuracy. Organizations will instrument a limited set of repositories and define event records, retention periods, and provenance confidence. The practical threshold is reached only if several major users request compatible evidence and make continued access or repository permissions depend on an outcome threshold.
In the second year, anonymized event statistics could support baselines across organizations. Repeated field failures would become reproducible sandbox cases, allowing researchers to test whether early warning signals predict later defects or extension effort. Permissions would also become more specific: an agent might be allowed to handle routine changes in one repository but face stronger review for a consequential task elsewhere. Approval would therefore attach to the complete agent and workflow configuration, not simply to a model name.
By the third year, measures with demonstrated predictive value could support auditable task bands, uncertainty estimates, and periodic re-evaluation. Developer tools and automated integration systems might use this evidence to decide where an agent may operate and which controls it requires. The resulting layer would combine benchmark breadth, recovery behavior, and downstream outcomes rather than produce a universal score. A useful monitoring cue would be compatible trace exports becoming a requirement in tool evaluations or continued-use decisions. The scenario should be downgraded if large replications find that post-acceptance measures do not predict maintenance burden or total workflow cost. It may also stall if privacy reviews block attribution or if telemetry encourages metric gaming. Because software changes are often reversible and developers continue modifying them, causal conclusions will remain more uncertain than the safety-monitoring analogy suggests.
1-Year / 3-Year Research-Application Infographic
References
- Unveiling Pitfalls: Understanding Why AI-driven Code Agents Fail at GitHub Issue Resolution - Authors: Zhi Chen, Wei Ma, Lingxiao Jiang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- OmniCode: A Benchmark for Evaluating Software Engineering Agents - Authors: Atharv Sonwane, Eng-Shen Tu, Wei-Chung Lu, Claas Beger, Carter Larsen, Debjit Dhar, Rachel Chen, Ronit Pattanayak, Tuan Anh Dang, Guohao Chen, Gloria Geng, Kevin Ellis, Saikat Dutta, / <See Details on Fugu-MT> / License: CC-BY-SA-4.0