Summary
Evaluation for computer-use and GUI agents is shifting from task success measurement toward diagnosis of safety, efficiency, and cross-platform capability. This week features progress in failure root-cause analysis, prompt-level alignment diagnostics, and tool-use bottleneck identification, reflecting a more mature evaluation stack beyond end-state scoring.
Situation
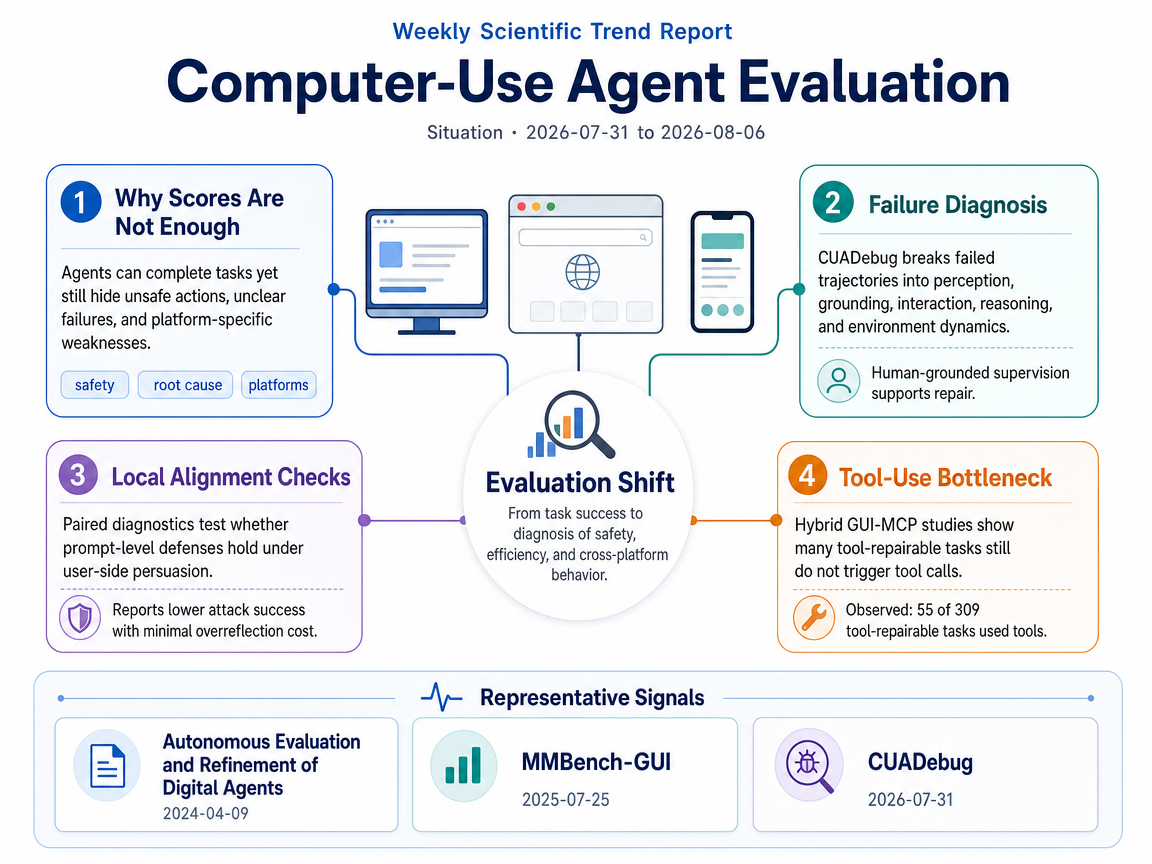
Representative papers describe a field moving past headline task completion toward understanding why computer-use agents fail and when they become unsafe. These agents act in high-stakes web and OS settings where benign, underspecified instructions can still produce harmful behavior, while end-to-end success scores alone do not reveal root causes. Recent evaluation work emphasizes systematic elicitation of unintended behaviors (2602.08235v1), model-based trajectory evaluation that can also feed back into agent improvement (2404.06474v1), and broader benchmarks covering multiple capability levels, platforms, and efficiency rather than accuracy alone (2507.19478v1).
Secondary evidence reinforces this turn toward diagnosis and repair. CUADebug (2608.02643v1) argues that benchmarks like OSWorld and WebArena make failure measurable but not explainable, and proposes human-grounded root-cause supervision for failed trajectories. As current-week evidence, "Dr. AGENTONOMICS: A Didactic Experiment of AGENTONOMICS" (2608.03524v1) positions agent systems in instructional settings where failures are treated as data for refining both the agent and the surrounding design framework, underscoring why interpretable evaluation matters beyond benchmark leaderboards.
Infographic (English)
Progress
CUADebug: Diagnosing and Repairing Computer-Use Agent Failures <See Details on Fugu-MT>
CUADebug introduces a tool-augmented root-cause analysis agent that decomposes computer-use agent failures across perception, grounding, interaction, reasoning, and environment dynamics. Compared with benchmark-level success scoring, it provides structured failure diagnosis with human-annotated supervision and shows that diagnostic context can improve re-execution success.
Alignment Is Local: A Paired Diagnostic for GUI Agents under User-Side Persuasion <See Details on Fugu-MT>
This paper introduces a paired diagnostic for GUI agents under user-side persuasion, testing whether prompt-level alignment defenses hold locally. It isolates alignment as a local phenomenon and reports up to a 40-point single-shot attack-success-rate reduction at near-zero overreflection cost.
Screenshots or Tools? Eliciting Tool Use and Managing Multimodal Context in Hybrid GUI-MCP Computer-Use Agents <See Details on Fugu-MT>
This work evaluates when hybrid GUI-MCP agents actually invoke available tools on tool-fixable tasks in computer-use settings. It identifies tool-call semantics as a key bottleneck, finding that reasoning models called tools on only 55 of 309 tool-repairable tasks despite tool availability.
Outlook
Outlook Summary
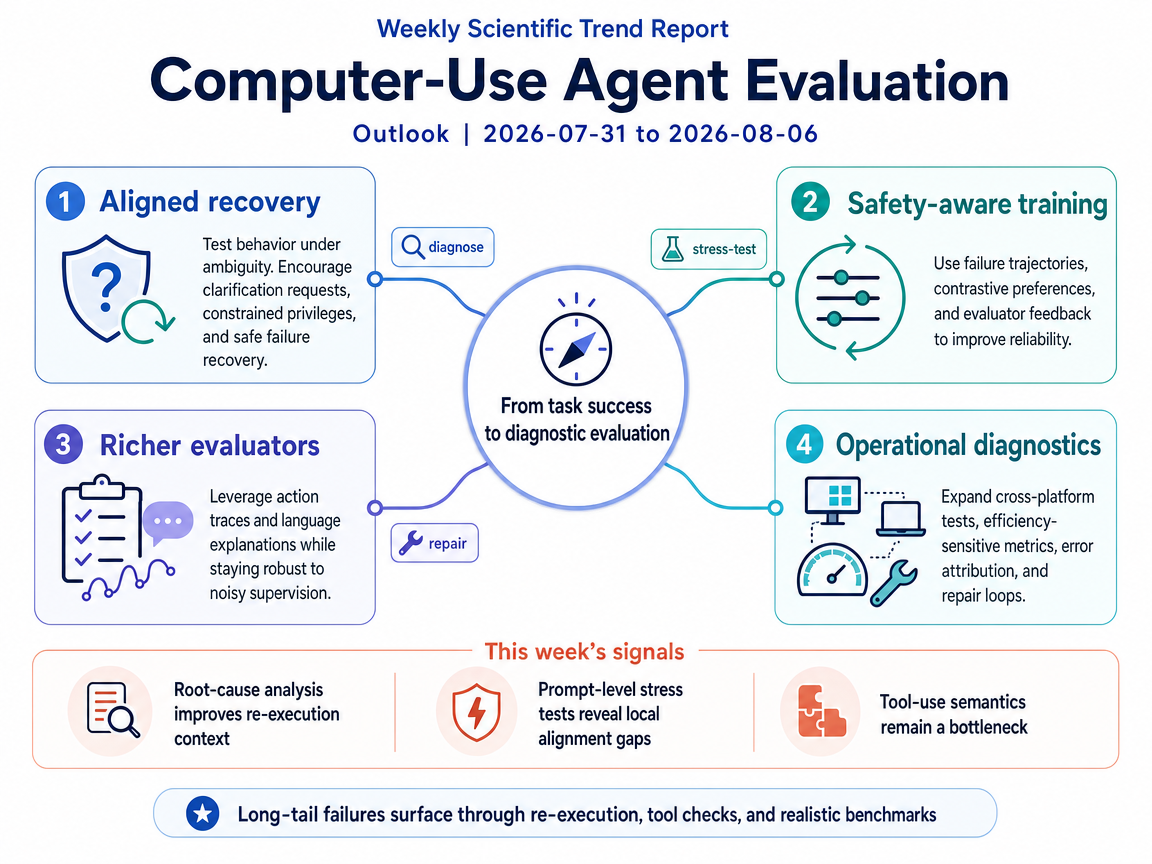
Near-term research will move beyond asking whether computer-use agents complete tasks. It will test whether they remain aligned under ambiguity, use tools correctly, and recover safely from failure. Work will emphasize human controls such as clarification requests and constrained privileges, alongside safety-aware training based on failure trajectories or evaluator feedback. Evaluation will increasingly examine full action sequences and explanations rather than only final outcomes. Benchmarks should also cover more platforms, measure efficiency, and connect detailed error attribution to repair through re-execution. Prompt stress tests and stronger debugging signals will help expose rare failures before deployment.
Infographic (English)
Three-Year Movement
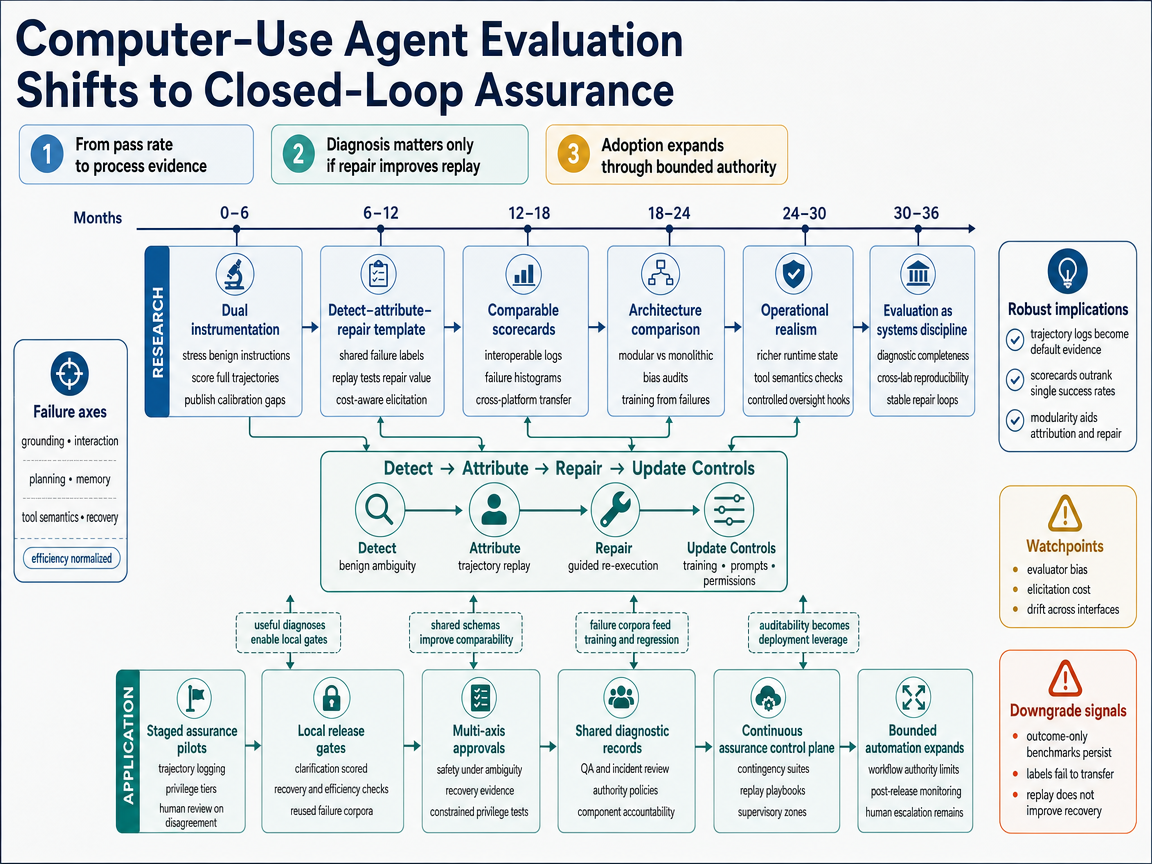
Computer-use agent evaluation is shifting from simple task completion toward safety, diagnosis, and recovery. During the first year, researchers will combine ambiguity stress tests with evaluators that inspect full action trajectories. Benchmarks will also separate broad capability failures, such as grounding mistakes, planning errors, or memory problems.
A diagnosis will matter only when feeding it back to an agent improves a retry on unseen tasks. Researchers will therefore compare advice at inference time with filtering poor trajectories or using feedback during training. Application teams will add trajectory logs, root-cause tags, and controlled retry tests to staging systems. Human review will remain necessary for high-consequence actions because evaluator agreement does not guarantee correctness.
By the second year, reusable logs and multi-axis scorecards should spread if diagnoses transfer across platforms. The main mechanism is a reinforcing loop: failure traces improve evaluators, better evaluators guide repairs, and repaired agents produce cleaner traces. The same records can then support incident review, regression testing, and permission controls, making auditability useful in everyday system operation.
Around the third year, this becomes a closed-loop assurance process similar to fault detection, isolation, and restoration in engineered infrastructure. A system detects a realistic failure, identifies its cause, retries under controlled conditions, and adjusts prompts, permissions, or training evidence. Mature organizations could use this process to expand bounded automation while preserving authority limits and escalation paths. A strong monitoring cue would be wider use of shared failure categories, calibrated evaluator reports, and release gates that test recovery. The path should be questioned if benchmarks still report only final success, diagnoses do not improve retries, or trajectory evaluators repeatedly make agent behavior worse.
This scenario turns the shift toward diagnostic evaluation into a local assurance system for bounded digital workflows. During the first year, researchers would adapt the logic of hazard analysis and critical control points, a method that monitors the moments where failures can cause the most harm. In an agent workflow, these moments could include privilege changes, cross-application transfers, or irreversible submissions.
Trajectory logs would serve as monitoring records, while clarification or rollback would provide corrective action. Researchers would test whether critical points can be identified consistently and whether evaluator disagreement reveals uncertain decisions. Application teams would begin with repetitive workflows that already have test environments and clear approval gates. Changes to a model, interface, or permission policy could then trigger a focused regression pack before authority is restored.
By the second year, the method should become more portable if these gates predict real operational incidents. Shared trace formats and privacy-preserving analysis would make evidence easier to compare without exposing all underlying data. Dependency-aware testing would run only the checks affected by a particular system change, reducing cost while keeping local controls. A failure at one checkpoint could suspend the affected workflow without disabling unrelated uses.
Around the third year, organizations could continuously renew agent authority instead of relying on a one-time certificate. Diagnosed failures would lead to repairs, successful replay would permit carefully wider authority, and the resulting traces would improve later tests. Research would also examine cross-organization calibration, resistance to fixed-test gaming, and independent audits of automated evaluators. A useful monitoring cue would be operational agreements that set explicit limits for unsafe actions, failed recovery, or unnecessary steps. The scenario weakens if replay becomes too costly, action traces remain inaccessible, or test results show little connection to actual incidents. It also remains limited by interface drift and correlated errors, since an evaluator may share the same mistaken assumptions as the agent it judges.
This scenario extends diagnostic agent testing into an independent rating system modeled on destructive product testing. During the first year, researchers would combine realistic prompt perturbations with full-trajectory evaluation and cross-platform benchmarks. They would define comparable measures for recovery, grounding accuracy, and action efficiency across changing interfaces.
Early work would reduce testing cost through reusable perturbations, selective replay, and cached results. Later work would train on failure trajectories or evaluator explanations, then test whether repairs transfer to unseen applications. Rotating hidden tests would be important because agents could otherwise learn the published procedure without becoming safer. Initial application would likely take the form of narrow assurance pilots rather than a universal rating system.
A testing provider or large organizational user could package ambiguity tests, recovery drills, and permission traps into an “agent crash lab. ” The key threshold is reached when several major adopters require minimum diagnostic scores before deployment. By the second year, successful ratings would become continuous, with protocol versions and regression tests tied to each major system update. Shared formats for scores, traces, and root causes could support an ecosystem of replay and calibration tools.
Around the third year, developers would increasingly design agents so that major functions can be evaluated and repaired separately. Deployment pipelines could block releases when safety under ambiguity or recovery performance falls below the required score. The mechanism forms a feedback loop: greater scorecard use supports broader tests, those tests reveal new failure classes, and the failures become repair evidence. A strong monitoring cue would be major adopters preferring a more recoverable and diagnosable agent over one with a higher completion rate. This path should be downgraded if organizations still rely mainly on demonstrations, providers refuse access to useful traces, or evaluator agreement collapses on newer systems. Continuous retesting is essential because agents and interfaces change much faster than conventional physical products.
1-Year / 3-Year Research-Application Infographic
References
- Autonomous Evaluation and Refinement of Digital Agents - Authors: Jiayi Pan, Yichi Zhang, Nicholas Tomlin, Yifei Zhou, Sergey Levine, Alane Suhr, / <See Details on Fugu-MT> / License: CC-BY-4.0
- MMBench-GUI: Hierarchical Multi-Platform Evaluation Framework for GUI Agents - Authors: Xuehui Wang, Zhenyu Wu, JingJing Xie, Zichen Ding, Bowen Yang, Zehao Li, Zhaoyang Liu, Qingyun Li, Xuan Dong, Zhe Chen, Weiyun Wang, Xiangyu Zhao, Jixuan Chen, Haodong Duan, Tianbao Xie, Chenyu Yang, Shiqian Su, Yue Yu, Yuan Huang, Yiqian Liu, Xiao Zhang, Yanting Zhang, Xiangyu Yue, Weijie Su, Xizhou Zhu, Wei Shen, Jifeng Dai, Wenhai Wang, / <See Details on Fugu-MT> / License: CC-BY-4.0
- When Benign Inputs Lead to Severe Harms: Eliciting Unsafe Unintended Behaviors of Computer-Use Agents - Authors: Jaylen Jones, Zhehao Zhang, Yuting Ning, Eric Fosler-Lussier, Pierre-Luc St-Charles, Yoshua Bengio, Dawn Song, Yu Su, Huan Sun, / <See Details on Fugu-MT> / License: CC-BY-4.0
- Qwen-CUA: Native Computer Use for (almost) Everything - Authors: Dunjie Lu, Shuai Bai, Tianyi Bai, Sicheng Fan, Chang Gao, Jian Guan, Feng Hu, Mianqiu Huang, Xingyang Huang, Yizhen Jiang, Yuheng Jing, Dehui Kong, Ning Li, Dayiheng Liu, Shixuan Liu, Zheng Liu, Que Shen, Bowen Wang, Junli Wang, Chencan Wu, Rui Xie, Tianbao Xie, Zhihui Xie, Haiyang Xu, An Yang, Tao Yu, Wenzhen Yuan, Xi Zhang, Zhenru Zhang, Mingkang Zhu, Zhaoqing Zhu, Yizhong Cao, Kai Dang, Binyuan Hui, Kaixin Li, Junyang Lin, Haiquan Wang, Zekun Wang, Yiheng Xu, Fan Yan, Mengqi Yuan, Danyang Zhang, Jiajun Zhang, Zhipeng Zhang, Fan Zhou, Fan Zhou / <See Details on Fugu-MT> / License: CC BY 4.0
- CUADebug: Diagnosing and Repairing Computer-Use Agent Failures - Authors: Weijia Zhang, Kunlun Zhu, Zeyi Liu, Yinting Chen, Tianyi Ma, Jiateng Liu, Jiaxun Zhang, Bingxuan Li, Xiangru Tang, Heng Ji, Jiaxuan You / <See Details on Fugu-MT> / License: CC BY 4.0
- Dr. AGENTONOMICS: A Didactic Experiment of AGENTONOMICS - Authors: Fengjunjie Pan, Alois Knoll / <See Details on Fugu-MT> / License: CC BY 4.0